Opus 5.5 performs at the level of Claude Fable 5.1 for most tasks while running ~30% faster and ~40% cheaper per task than Opus 5. Perplexity's WANDR benchmark scored it 0.610 at $4.13 per task, beating Fable 5.1 while costing 67.6% less per task.
Claude spent 21 hours and ~210M tokens across ~950 parallel agents scanning 200,000+ reverse transcriptases, narrowing to 3,500 candidates and then 20. The find, named ART (array-associated reverse transcriptases), sits in bacteriophage DNA; CRISPR co-inventor Feng Zhang called it "genuinely intriguing."
The two text-to-speech models offer 2,000+ production-ready voices, custom voice design across 100+ languages, and voice replication from a 30-second sample. Flash TTS debuts at #1 on Artificial Analysis's Pronunciation Robustness benchmark at 89.5%, ahead of Gemini 3.1 Flash TTS at 88.2%.
FLUX 3 Action is an open-weights 7B World Action Model that takes first place on the RoboLab benchmark, beating the previous best open model by 6.1 percentage points with 56% fewer parameters and up to 3.95x faster runs.
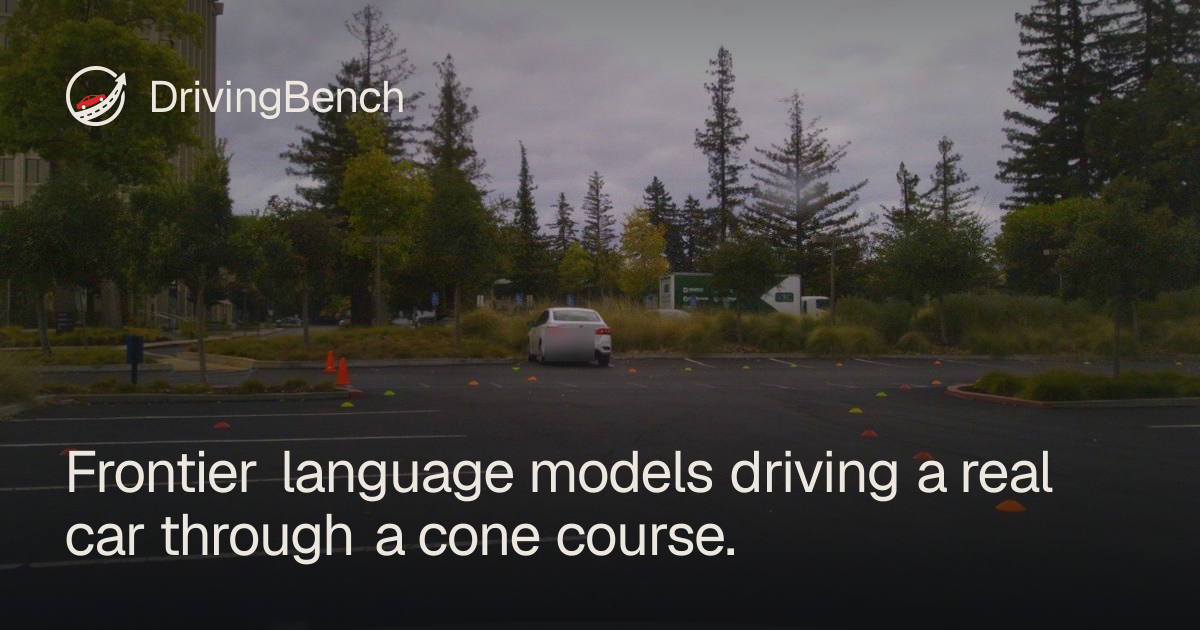
DrivingBench gave frontier models control of a Toyota Corolla's steering, accelerator and brakes on a fixed cone course. GPT-6 Astra (Codex, medium) hit 100% progress and finished in 5:22 on attempt 2; Claude Fable 5.1 reached 45% and Grok 4.6 11%.