llama.cpp PR fuses MoE gate/up matmuls and GLU in MMQ for CUDA
Read original source →github.com
Pull request #31188 by anujj reports prompt-processing gains on DGX Spark (GB10): +17.2% on Qwen3-30B-A3B Q4_K_M and +9.9% on Qwen3.6-35B-A3B Q4_K_M versus master. The change targets MoE gate/up matmul and GLU fusion in the MMQ CUDA path.
1 source
More stories today
Law firm subreddit debates whether AI delivers real leverage
A r/LawFirm poster asks whether anyone has found AI uses beyond email drafting and first-pass document review with Claude, saying current tools save only a few hours a week. The question targets freeing up roughly 50 hours weekly.
r/LawFirm·53 minutes agoMeta's Muse models teased in researcher post
AI at Meta·59 minutes agoWired tests Codex-run AI agents on a fantasy soccer team
Wired's Will Knight had Codex build a multi-agent harness that reads news, analyzes results, and critiques picks; the first roster benched Erling Haaland. Splitting agents into specialized roles improved picks, but scaling past 100 agents only raised the API bill.
Wired·1 hour ago

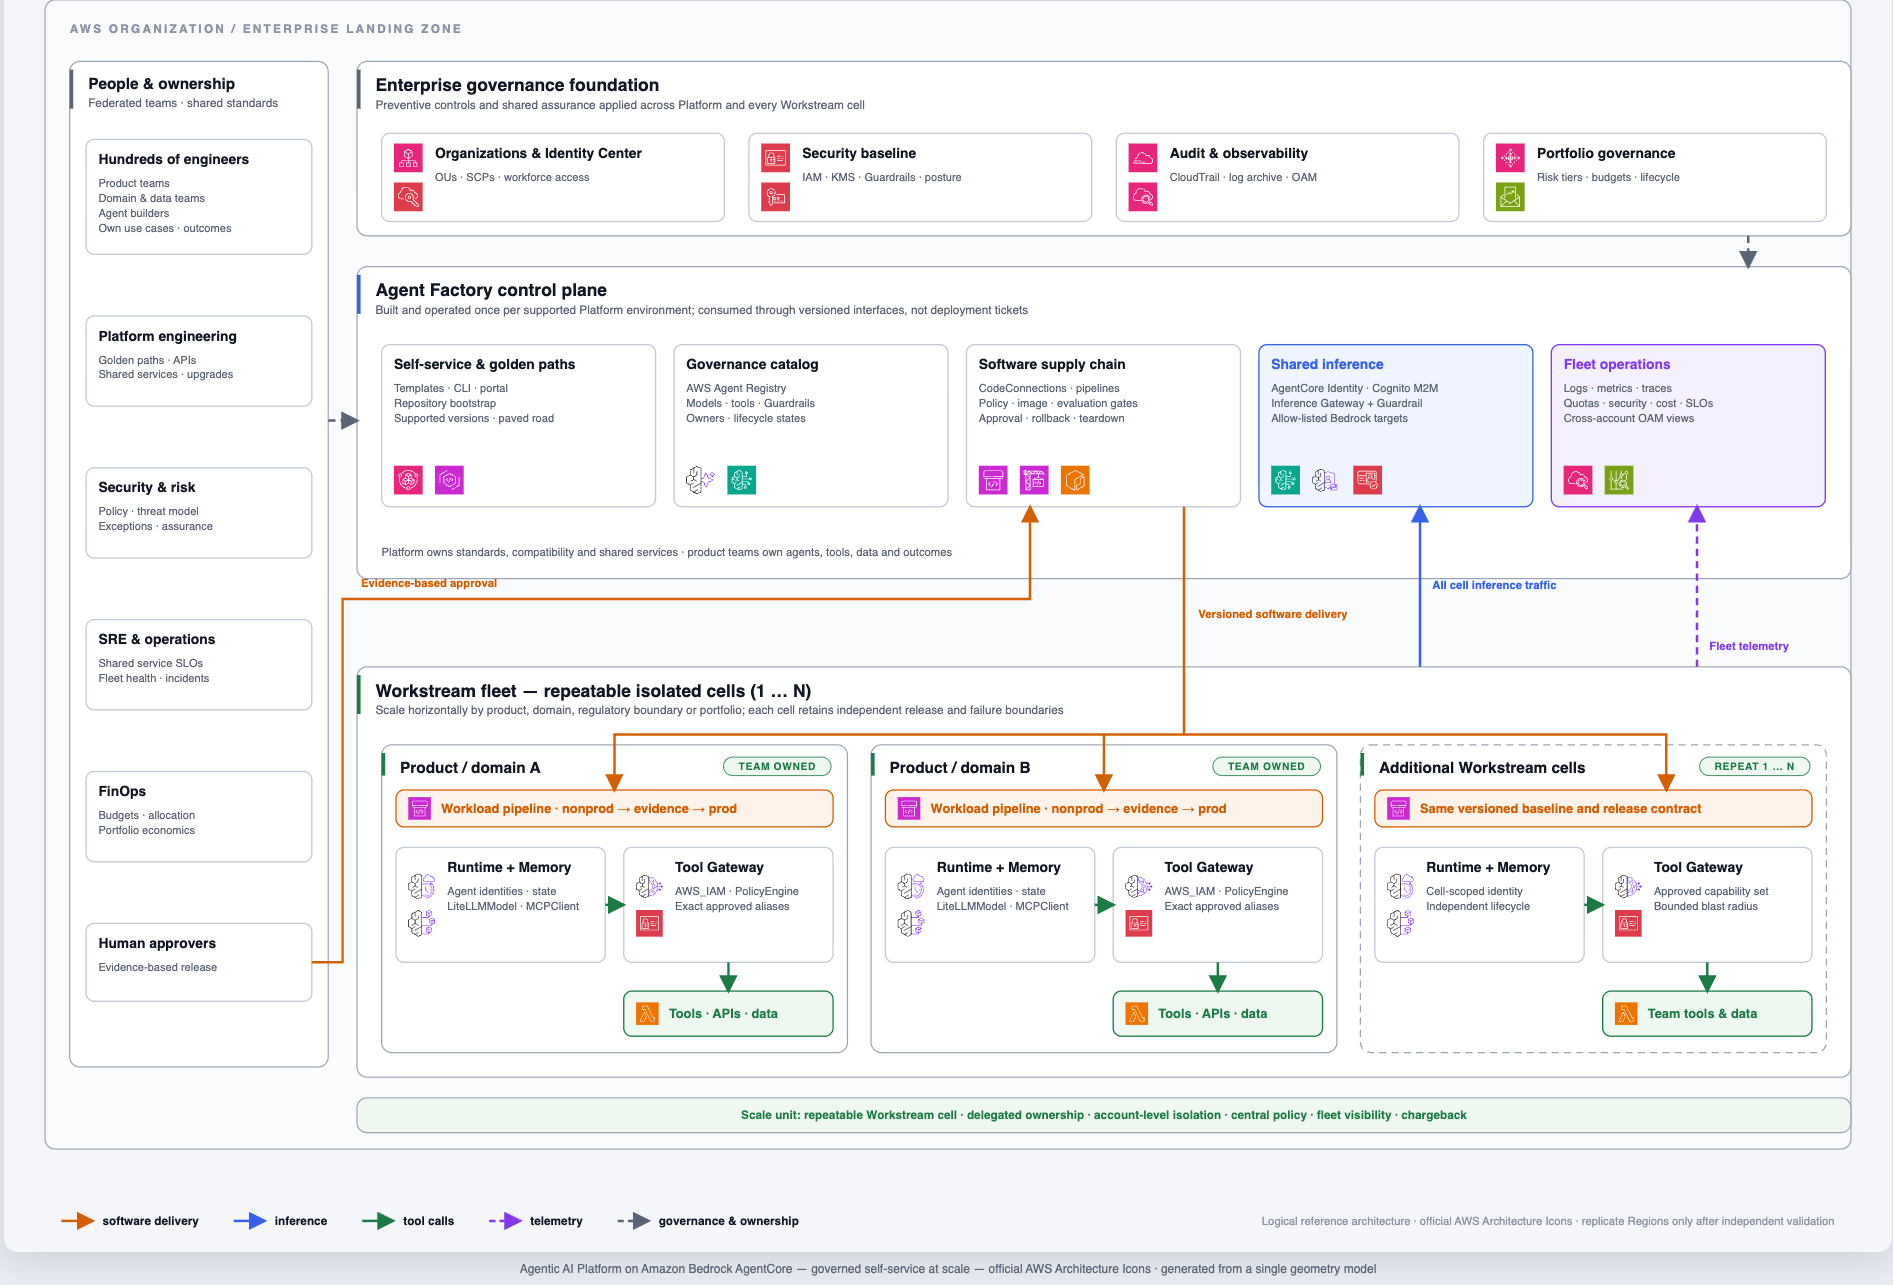
AWS publishes guide to building an agentic AI platform on Bedrock AgentCore
The AWS post argues the model and tool use aren't the production blocker — governance around them is: how many teams can build in a secure environment, which team owns each model and tool, and keeping AgentOps and error handling inside a pre-defined boundary.
AWS AI Blog·1 hour ago
Clarida: AI boom complicates Fed's demand-versus-supply call
Former Fed Vice Chairman Richard Clarida says the central bank is weighing whether AI-driven growth is a demand shock that could call for higher rates, or whether productivity gains will eventually boost supply and ease inflation.
Bloomberg Technology·1 hour ago
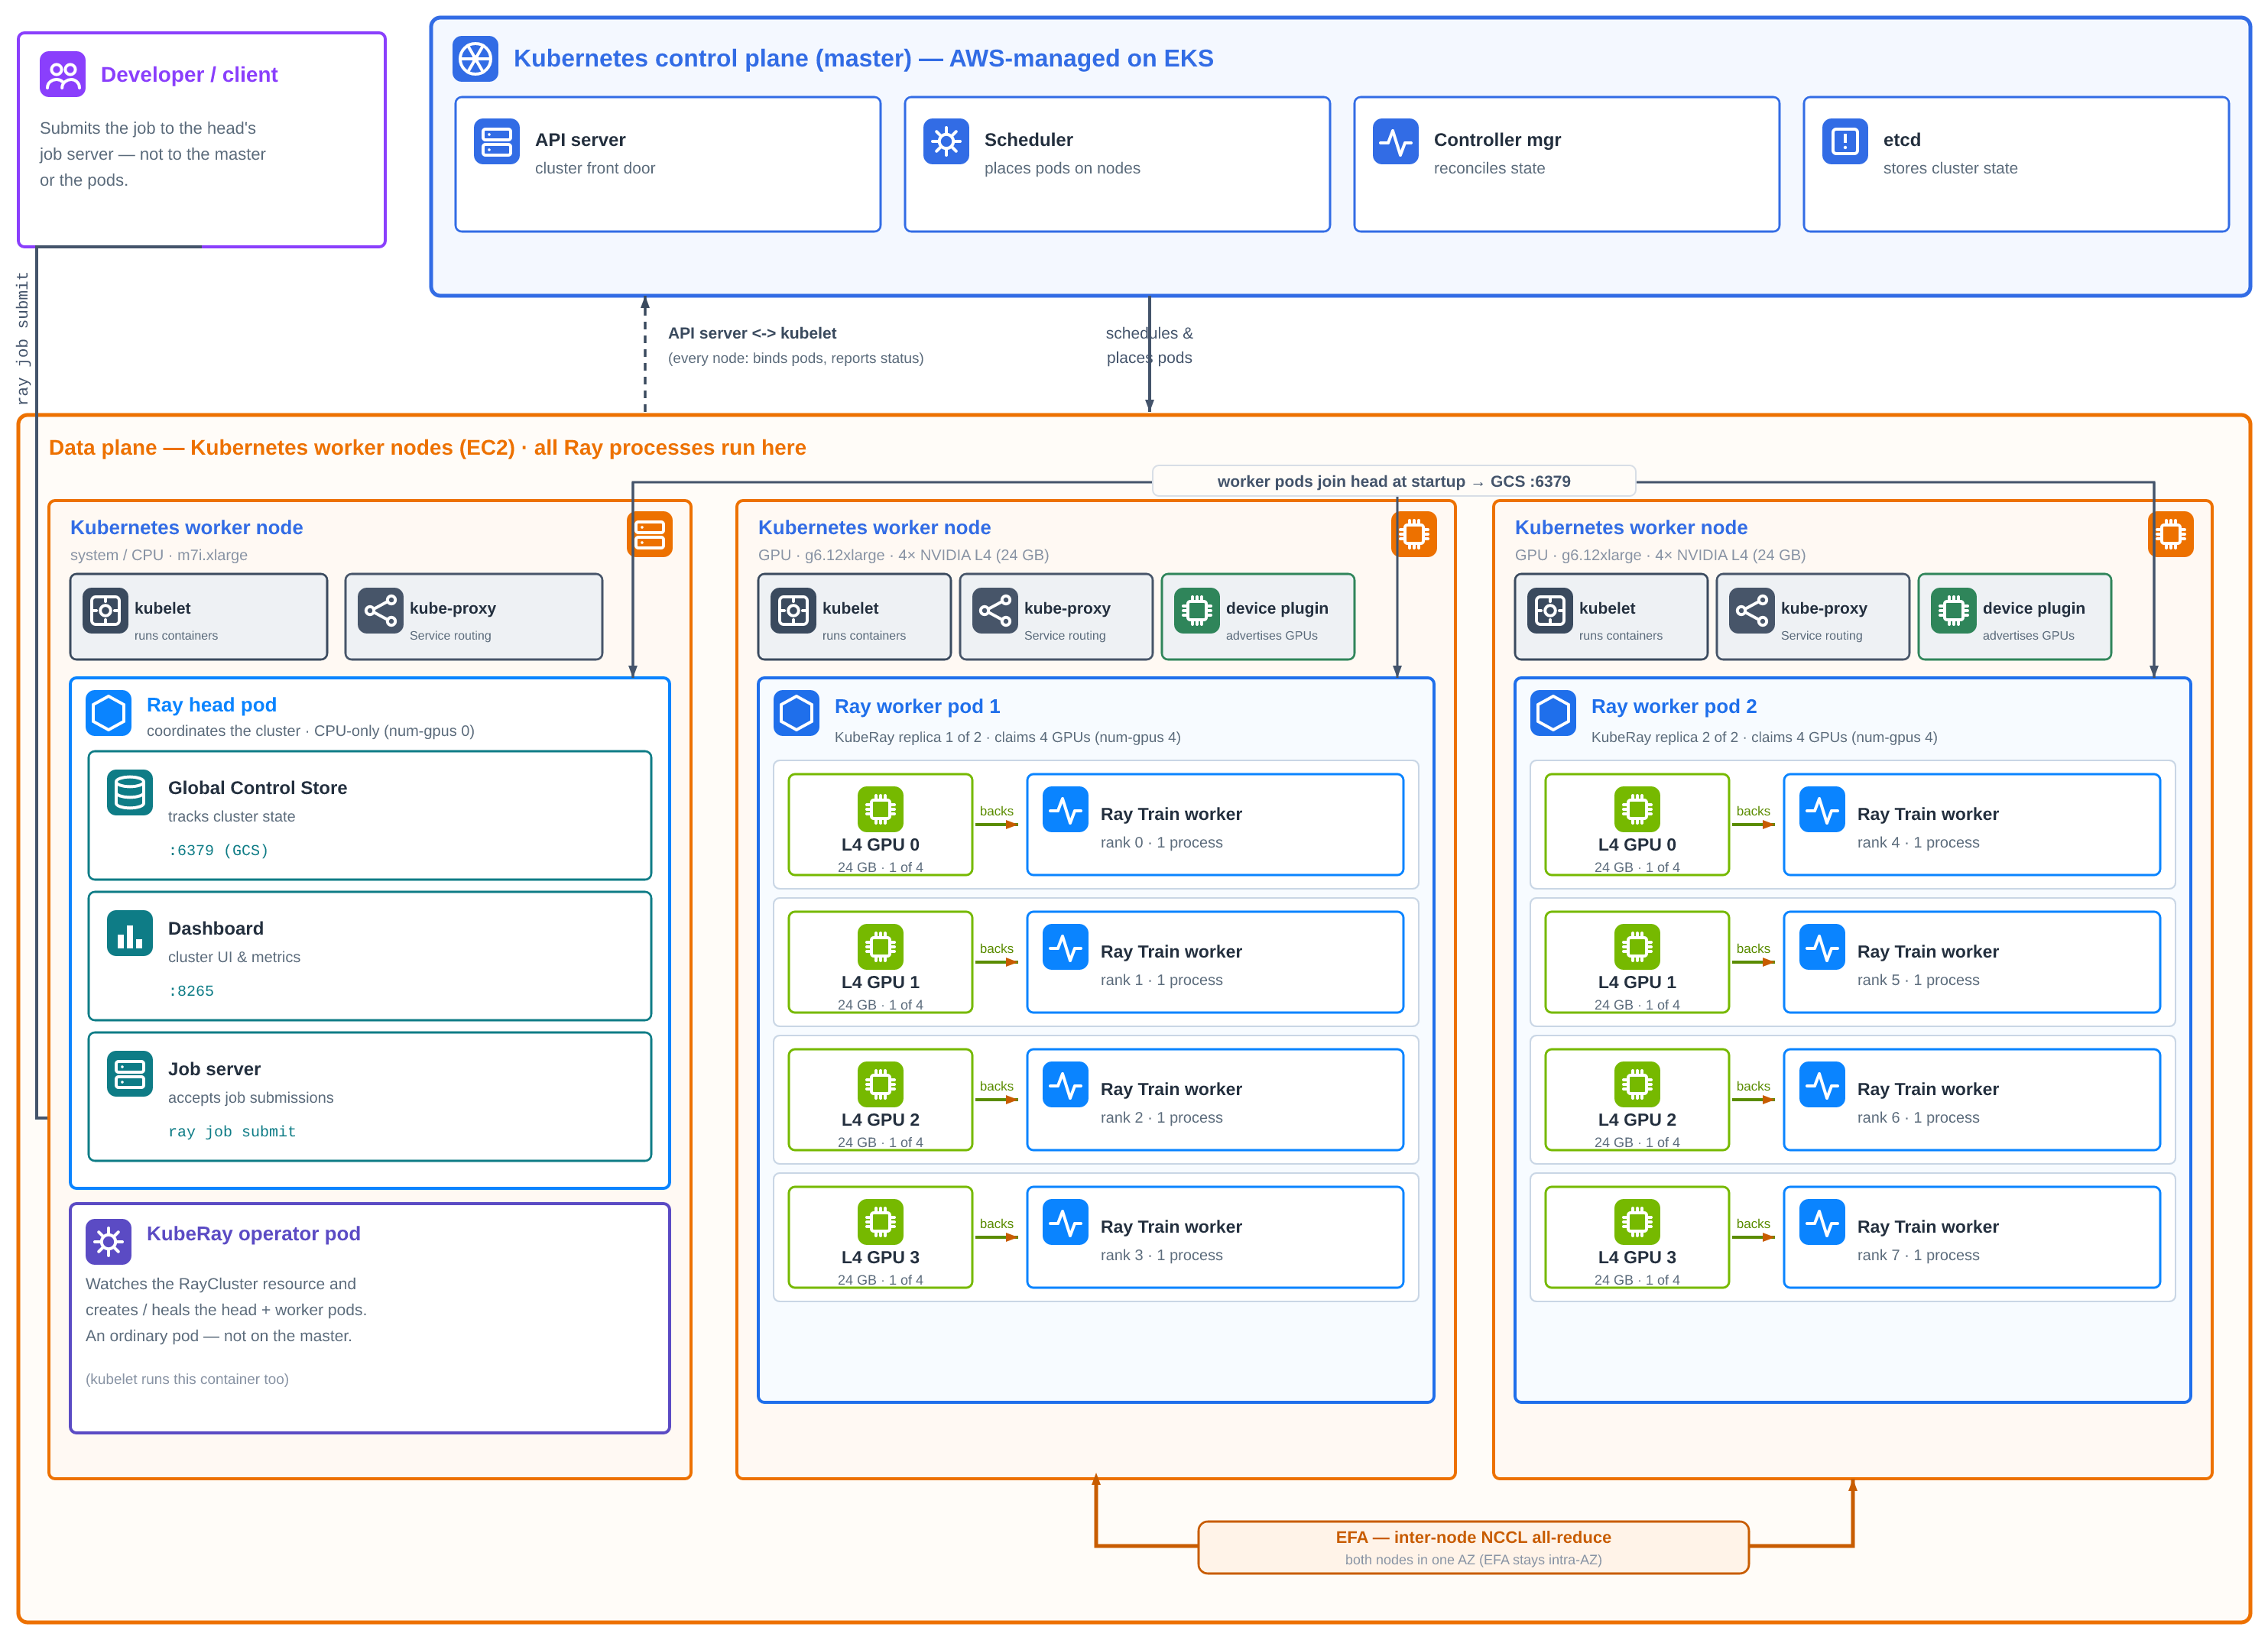
AWS shows distributed PyTorch training with Ray Train DLCs and EFA on EKS
AWS's walkthrough targets the container, not the model code, as the usual blocker to scaling PyTorch across a cluster — each container needs a matching CUDA runtime, a PyTorch build compiled against it, NCCL, and EFA userspace libraries.
Reddit user asks how to do reverse engineering with AI despite safety filters
A hobbyist reverse engineer says mainstream AI assistants block their personal RE work, ranking Gemini as the strictest, then ChatGPT, then Claude. They ask r/ChatGPT for ways to work around the refusals.
r/ChatGPT·1 hour agoReddit user tests GPT 6.1 Terra Max on 3js horse model
Prompted to build a realistic horse model and walking animation in three.js, the model took ~15 minutes and consumed 30% of a 5-hour Plus limit. The user had to stop it from fetching existing horse models online and require it to generate the model itself.
r/ChatGPT·1 hour ago