GSQ-RCO GGUFs released for Qwen3.8-Flash-Next, plus 50% expert-pruned build
Read original source →reddit.com
Community release quantizes Qwen3.8-Flash-Next with GSQ and RCO, alongside a capability-targeted build with half the experts removed at ~1.89 bpw. The sparse MoE model has 512 routed experts per layer across 48 layers, 176.9B parameters, and 354 GB at full precision.
1 source
More stories today
Hugging Face policy chief says embedded AI evaluators need standardization
Irene Solaiman said at TechCrunch Disrupt that evaluations are "an evolving science" the industry doesn't know how to meaningfully compare, and that reproducibility hinges on open weights. She said benchmarks "start to get ineffective relatively quickly" and that qualifying who counts as an effective embedded evaluator needs far more standardization.
TechCrunch·29 minutes ago

OpenAI improves ChatGPT coding in COBOL, Fortran, Visual Basic
OpenAI says its latest model advances strengthen building and migrating software in low-resource languages like COBOL, Fortran, and Visual Basic, which power bank, government, and business systems. It added new evaluations covering software engineering, SQLite, and COBOL migration.
OpenAI Blog·43 minutes ago
ChatGPT Slides adds real-time collaborative editing
TestingCatalog News·50 minutes ago
Scoble: AI content generated on two DGX Sparks
Robert Scoble·1 hour ago
Microsoft launches Guardian Agents to monitor enterprise AI agents
Guardian Agents is part of Project Perception, Microsoft's June product that launched red-team, blue-team and green-team agents. CEO Satya Nadella warns enterprises must not trust model providers' safety assurances: "we need to separate the supply of intelligence from the authority over it."

Databricks adds Agent Memory to Agent Bricks
Agent Memory on Agent Bricks, in beta, gives agents durable long-term memory stored on Lakebase inside the customer's Databricks workspace, so each conversation starts with what the agent learned previously.
YouTube·1 hour ago
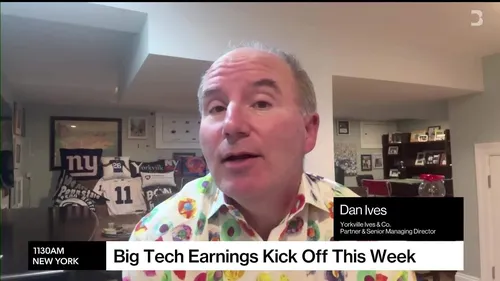
Ives: Big Tech earnings will test AI confidence
Dan Ives of Yorkville, Ives and Company says upcoming earnings from major tech companies will be an important test of confidence in AI. He also discusses giving investors a chance to invest in private AI companies.
Bloomberg Technology·1 hour ago
Anthropic launches OSS Scanner for free open-source vuln scans
Claude Developers·1 hour ago