Apple researchers pretrain first tri-modal masked diffusion model
Read original source →machinelearning.apple.com
Apple's study pretrains a Masked Diffusion Model from scratch on text, image-text, and audio-text data, reaching 3B parameters over 6.4T tokens with results in text generation, text-to-image, and text-to-speech. It reports the largest systematic open study of multimodal discrete diffusion models to date.
1 source
More stories today
NVIDIA's Nemotron 3.5 Lightning lands free on Vercel AI Gateway
Nemotron 3.5 Lightning is a 30B-parameter open-weight reasoning model with 3B active per token, a hybrid Mamba-2/MoE design, and a 1M-token context window. It is free on AI Gateway as nvidia/nemotron-3.5-lightning-free, served by NVIDIA, with tool calling and structured outputs.
Vercel Blog·2 hours ago
Dreamina Seedance 2.5 climbs to #3 on Text-to-Video Arena
ByteDance Seed's Dreamina Seedance 2.5 rose from #4 to #3 with a score of 1159.2, up from 1104.6, in a snapshot that reshuffled 10 models. Utopai X leads at 1165.6, with MiniMax H3 (768p) at 1158.2 and MiniMax H3 Max falling from #2 to #5.
Artificial Analysis Leaderboard·2 hours ago
Utopai X tops Artificial Analysis Text-to-Video Arena
Utopai Studios' Utopai X scored 1165.6 to take #1 on the Artificial Analysis Text-to-Video Arena snapshot dated 2026-10-14. It edges ByteDance Seed's Dreamina Seedance 2.5 (1159.2) and MiniMax H3 at 768p (1158.2).
CoreWeave shares tumble as AI debt concerns mount
CoreWeave shares sank 15% and its bond yields neared 15% as investors repriced risk in the AI borrowing binge. Intel and Broadcom CEOs warned capital access could become AI's biggest bottleneck, while Rishi Sunak said tech firms may out-issue the US government in long-term debt by 2027.
CNBC Technology·2 hours ago

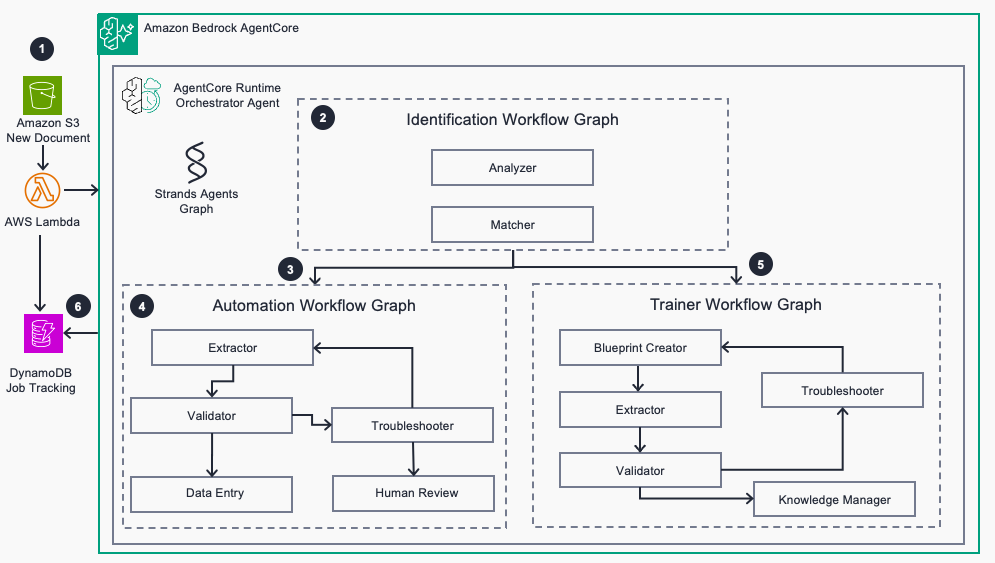
AWS shows self-improving document processing on Bedrock AgentCore
AWS tutorial builds a self-improving document pipeline on Amazon Bedrock AgentCore, targeting invoice layouts that vary by supplier and change without notice. It cites IDC figures of $19,732 lost per information worker annually and a 21.3% productivity hit from document challenges.
AWS AI Blog·2 hours ago
Cohere: coding agent teams reach frontier at 30% of cost
Cohere's controlled testbed study finds teams of coding agents can match frontier results at roughly 30% of the cost. It cites prior runs: 16 Claude agents wrote a 100,000-line C compiler for ~$20,000 in API costs, and Bun was ported from Zig to Rust in 11 days with 64 parallel Claude agents.
Cohere Blog·2 hours ago
Apple researchers detect code-switching directly from speech encoders
Whisper-small encoder hit a mean F1 of 0.798 across 14 language pairs in CS-FLEURS, beating a CNN (0.776) and a HuBERT linear baseline (0.751). The method finds language-selective hidden-state dimensions using monolingual recordings, avoiding reliance on multilingual transcription.
Apple ML Research·2 hours ago
Third Moment Research runs 10,000 agents for 36+ hours on GPT-6 Astra
Third Moment Research uses GPT-6 Astra, GPT-6.1 Sol, Codex, and Daybreak for cybersecurity to build agents that focus for days and improve with use.
OpenAI Blog·2 hours ago