vLLM uses coding agents to optimize Kimi K3 inference
Read original source →vllm.ai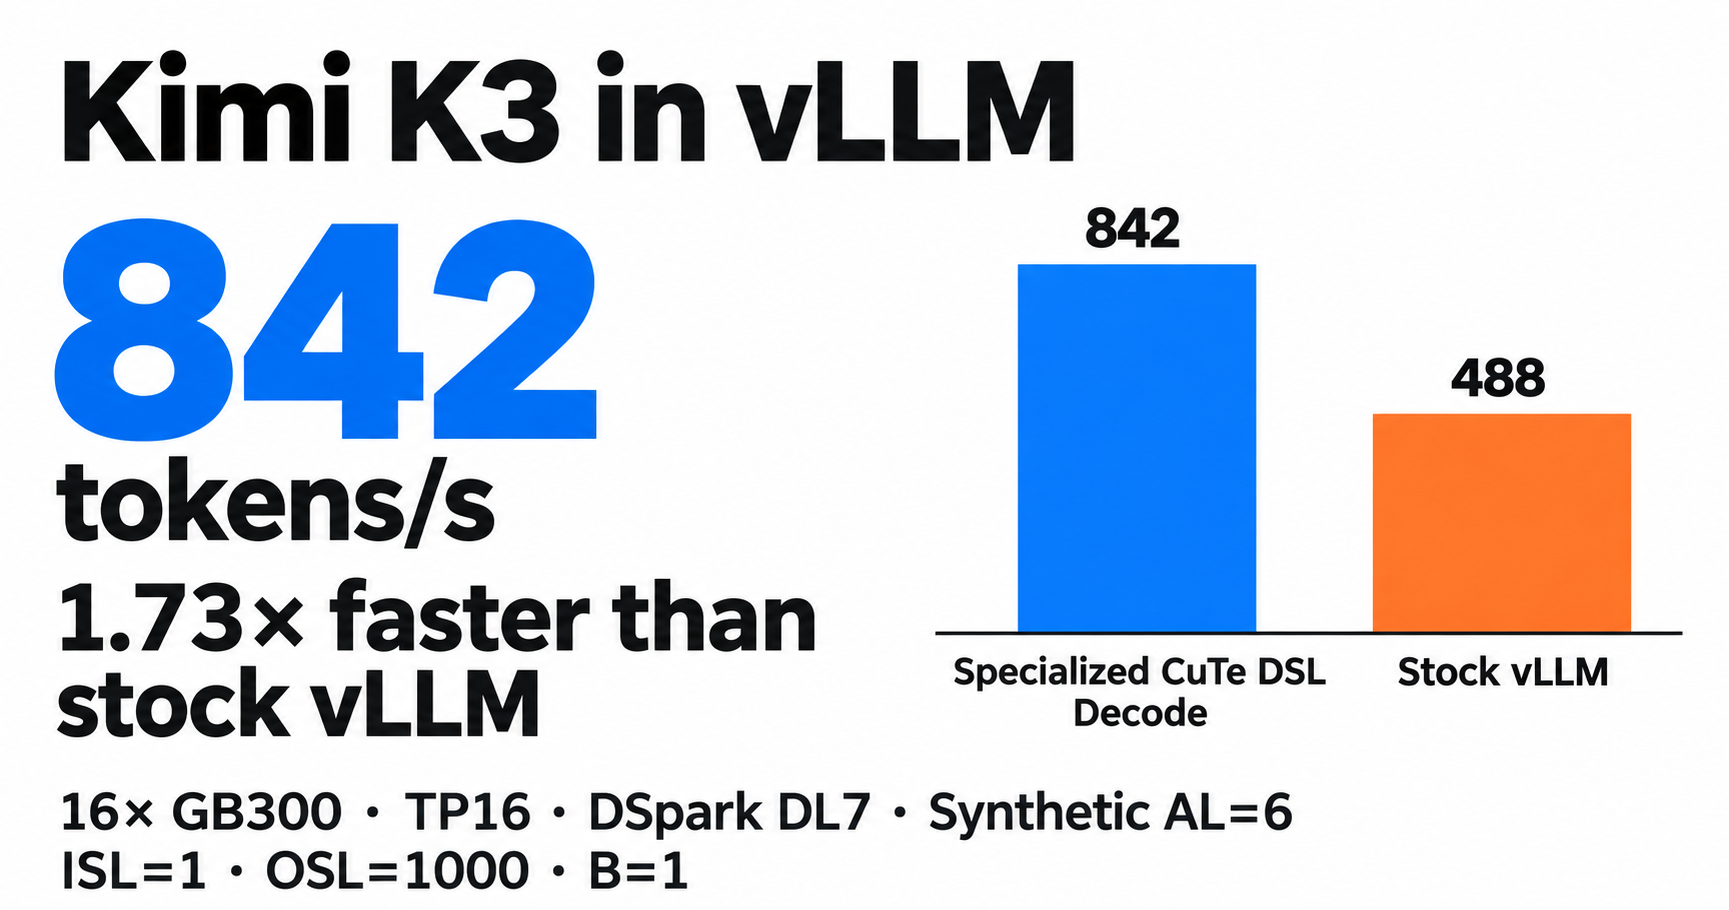
Agent-assisted CuTe DSL decode path on NVIDIA GB300 hits over 840 tokens/s at batch 1 on 16 GPUs with DSpark, with 1.5–2× higher decode throughput in several tested configs and up to 1.8× higher P90 interactivity on AgentX.
1 source
More stories today
Jack Clark tells IMF the singularity has begun
In an October 17 Per Jacobsson lecture at the IMF meeting in Bangkok, the Import AI author argued AI is reaching the frontier of human science, sometimes autonomously, and told economists and policymakers to expect rapid change. He framed the talk around foresight and restraint in sharing AI's benefits.
Import AI·1 hour ago
Space Bunny model arrives on Together AI
Together AI·1 hour ago
MiniMax announces M3.1 Flash, scoring 74% on DeepSWE
MiniMax M3.1 Flash, previously known as "Space Bunny" on OpenRouter, costs $0.15/$0.60 per 1M input/output tokens. Weights arrive October 23, and MiniMax is also preparing a Pro variant.
TestingCatalog News·1 hour ago
Terence Tao discusses AI's role in a 22-million-problem math project
In a Futurology conversation with Dawn Nakagawa, Tao describes a project built around 22 million algebra problems and argues useful failures should be shared openly. He also explains how experts can extract value from unreliable AI tools.
AI Signal·1 hour ago
DeepMind's Lila Ibrahim discusses AI risk and access in interview
Google DeepMind Chief AI Readiness Officer Lila Ibrahim speaks with ET's Tech Editor Surabhi Agarwal about whether AI companies can credibly warn about risks while racing to build more powerful models. The conversation also covers who ensures AI's benefits reach beyond the people and countries already ahead.
ET Digital·1 hour ago
SonicBoom v0.0.3: compiler-first AI runtime claims faster decode than llama.cpp
HardenedLinux's GPLv3 SonicBoom runtime has no Python at build or run time — one shared library, a C ABI, and Guile Scheme as its first-class language. The community is now crowdsourcing GPU benchmarks for v0.0.3.
r/LocalLLaMA·1 hour ago
Guide covers tmux setup for running Claude Code agents
Guide walks through session-per-project naming, pane layouts, send-keys scripting and capture-pane readback for running Claude Code in tmux. Notes Claude Code's built-in claude --worktree --tmux flags handle the single-agent-on-a-branch case, and that limits appear around four agents.
Hacker News·1 hour ago
Brockman: OpenAI moved 25% of production engineers to security
OpenAI reassigned a quarter of its production engineers to security and used its top AI model to hunt vulnerabilities in its own systems, per President Greg Brockman on No Priors. Brockman argued security spend "should actually vastly outstrip software spend."
YouTube·2 hours ago