Google releases Gemini 4 Argon, its latest frontier model
Read original source →blog.google
Google DeepMind's Gemini 4 Argon scores 97.5% on ARC-AGI-3 and 91.3% on ARC-AGI-2, and tops Scale Labs' Humanity's Sixth Sense benchmark at 55.4%, edging GPT-6-Astra's 53.6%. It is available to developers, enterprises, scientists and consumers, and in Perplexity for Pro and Max subscribers.
People · Koray Kavukcuoglu, Raluca Ada Popa
How this story unfolded
4 days · 25 reports · 47 community posts · 72 of 76 shown
- Oct 13
Gemini 4 Argon: Built to solve your hardest problemsblog.google
Gemini 4 Argon for Roboticsdeepmind.google
Optimizing a 200,000-line Python codebase overnight with Gemini 4 Argondevelopers.googleblog.com
Teaching a humanoid robot to play cornhole with Gemini 4 Argonyoutube.com
Gemini 4 Argon now available on AI Gatewayvercel.com
Google makes Gemini 4 Argon broadly available with limited-time low API pricing of $2/$10 per 1M tokenventurebeat.com
Gemini 4 Argon debuts with a unified 1M input/output token limitthenewstack.io
Gemini 4 Argon in Google Antigravityantigravity.google
Google finally releases Gemini 4 Argontheverge.com
Gemini 4 Argon is now available in Devindevin.ai
Gemini 4 Argon begins rolling out in Gemini app and Antigravity, but only if you payarstechnica.com
llm-gemini 0.35simonwillison.net
- Oct 14
- Oct 15
- Oct 16
- Oct 17
More stories today
Indie dev spends $1,000 a day keeping AI driving sim demo live
Developer of the Steam demo "Teach my little sister how to drive" went into debt covering roughly $1,000 per day in AI inference costs to keep the demo running, per Kotaku. The AI-fueled driving simulator's running costs outpaced what the demo earned.
r/artificial·39 minutes ago
AcademiaSD LoRAlab Trainer Studio adds MOSS-Image LoRA training support
The LoRAlab Trainer Studio now supports MOSS-Image, enabling LoRA training for the Apache 2.0 model on hardware with under 6 GB of VRAM. It is the 12th model family integrated into the studio, which uses 4-bit NF4 loading for consumer GPUs.
r/StableDiffusion·59 minutes ago
Reddit users debate whether newer GPT models lack intuition
A r/ChatGPT poster argues recent models (Astra and 6) need everything spelled out explicitly and lack agency and initiative, unlike GPT 5.6, which added imaginative details unprompted.
r/ChatGPT·59 minutes agoReddit post shares benchmark scores for an unnamed Chinese model
A r/Singularity gallery post titled "New chinese model benchmark scores are INSANE!" shares benchmark charts, but the snippet contains no model name, scores, or source.
r/Singularity·1 hour ago
ADI whitepaper frames physical AI as sensing and control challenge
Analog Devices argues the next AI hurdle is acting under imperfect measurements, timing constraints, and real-world consequences, not better model performance. The Wilmington, Mass. company says success requires advances across sensing, simulation, computing, connectivity, and control.
The Robot Report·1 hour ago
Meta drops scraping clause from new commercial terms after backlash
Meta removed a provision, effective October 30, that let it crawl and use content from domains "associated" with business accounts to "train" its AI products. Legal experts told Nieman Lab it could override robots.txt and dodge licensing fees; Meta says crawling behavior is unchanged.
TechCrunch·1 hour ago

Gemini 4 Argon builds a Fall Guys clone in demo
Matthew Berman's video shows Gemini 4 Argon generating a Fall Guys-style game. The clip is a creator demo, not an official Google release announcement.
YouTube·1 hour ago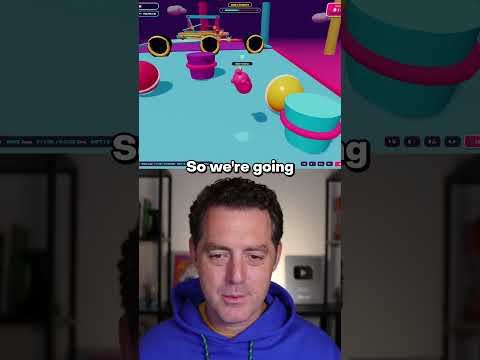
NVIDIA RTX Spark laptops ship from $2,399 with 128GB unified memory
RTX Spark pairs a Blackwell RTX GPU with a Grace CPU for up to 1 petaflop of FP4 AI compute and 128GB unified memory, in systems from ASUS, Dell, HP, Lenovo, Microsoft and MSI. Artificial Analysis clocked a local agent workload on Qwen3.8 27B at 18.7 minutes.
blogs.nvidia.com·2 hours ago