SpecPilot autonomously tunes speculative decoding for faster LLM serving
Read original source →arxiv.org
SpecPilot searches for deployment-specific algorithms and system optimizations — parallel drafters, tree verification, batching, weight quantization — to maximize speculative decoding speedups without quality loss. The paper argues released stock systems may not attain the full speedup parallel drafting permits.
2 sources
More stories today
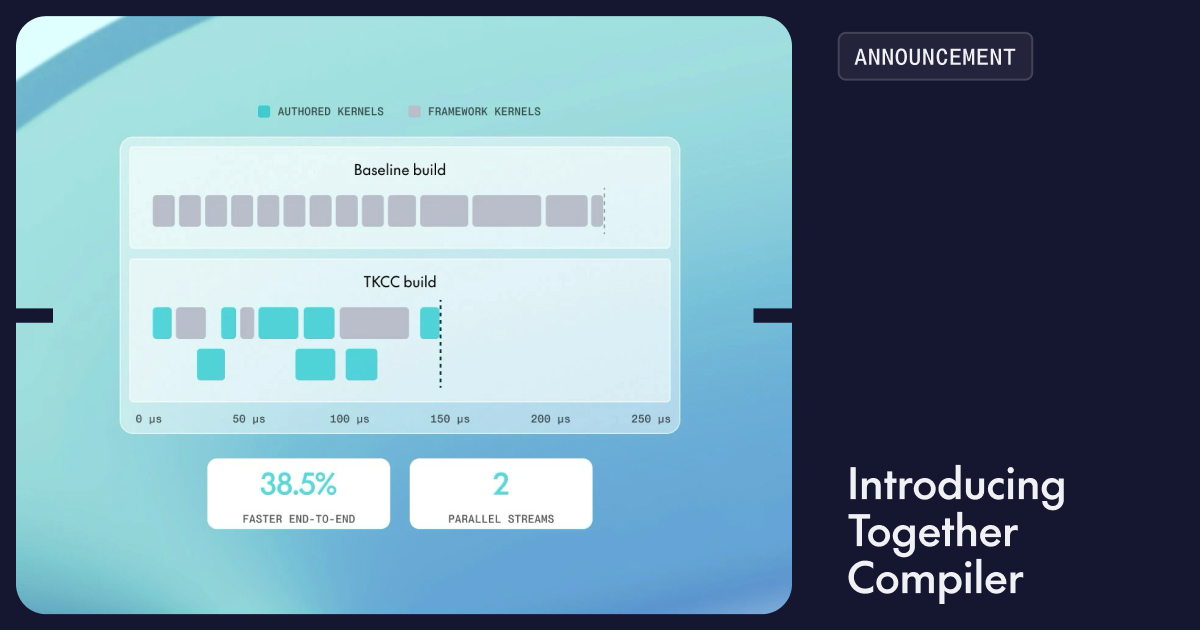
Together AI launches Together Compiler for continuous inference tuning
Together Compiler (TKCC) uses high-throughput agents to re-optimize open models in under 24 hours, hitting up to 2.6x higher TPS on Kimi K3, GLM 5.3, MiniMax M3.1-Flash and DeepSeek v4.1-Flash. It sets SOTA on SemiAnalysis' InferenceX low-latency benchmark at 1111 TPS on MiniMax M3.1-Flash and 1205 TPS on DeepSeek v4.1-Flash.
Together AI Blog·1 hour ago
Altman walks back RAM remarks, rebrands as 'Ram Altman' on X
After saying on the Cheeky Pint podcast it's "quite terrible" for people to hoard DRAM used 5% of the time, Altman said the quote was taken out of context and he's long argued for ramping memory production. Intel expects the shortage to last through at least next year; SK Hynix says it could drag on until 2030.
The Verge·1 hour ago
Sysdig launches AI Defense for runtime agent security
Sysdig AI Defense monitors every action an AI agent takes, down to kernel-level processes, and blocks risky behavior in line before an action completes. CTO Loris Degioanni says agents now ship code and change infrastructure faster than teams can review by hand.
SecurityWeek·2 hours ago

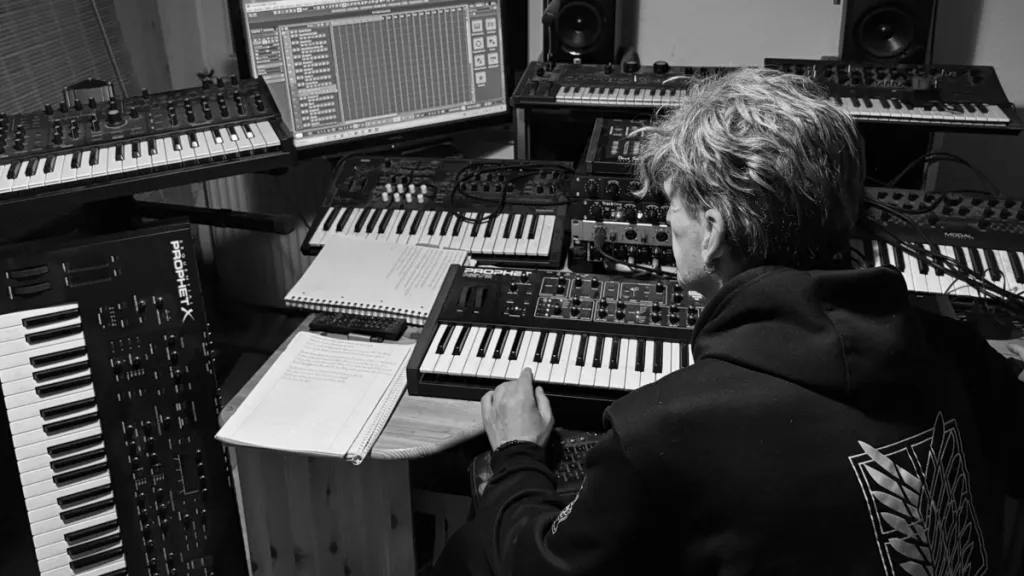
AI detectors falsely flag indie musicians' original tracks as AI-made
AI music detectors can mislabel handmade electro-synth tracks as AI-generated — including original recordings made in the 1980s. The false positives create a new risk for indie artists in a music industry already grappling with AI.
Digital Music News·2 hours ago
Indian Community School educator details AI literacy curriculum push
Pattie Morales, who develops AI literacy curriculum at the intertribal Indian Community School in southeastern Wisconsin, describes writing AI policies for tools that get updated or replaced before approval. She argues schools should teach how AI works before students use it, framing it around Indigenous values and responsibility to future generations.
EdSurge·2 hours ago
Living Brain claims 22.6x token savings via retrieval
Hasan Toor·2 hours ago
Cloudflare adds analytics and access policies for personal AI agents
Security Analytics gains a "Personal Assistants" bot category alongside Verified Bot and Likely Human, plus a Top statistics widget listing which agents visit a site and their request counts. Granular access policies let site owners set terms per agent instead of blocking all automated traffic.
Cloudflare AI Blog·2 hours ago

Shopify: AI channels drive 2.6x traffic, 3.3x order growth
Shopify president Harley Finkelstein said AI traffic is up 2.6x year-over-year and orders 3.3x, with AI channels sending shoppers to product pages at 3x the rate of organic search and converting 64% more often. He named Muse, Instinct, Claude Duet and Grok Bot as agent partners, plus ChatGPT and Microsoft.
Music Ally·2 hours ago
