Arena study finds LLM judges favor their own answers
Read original source →arena.ai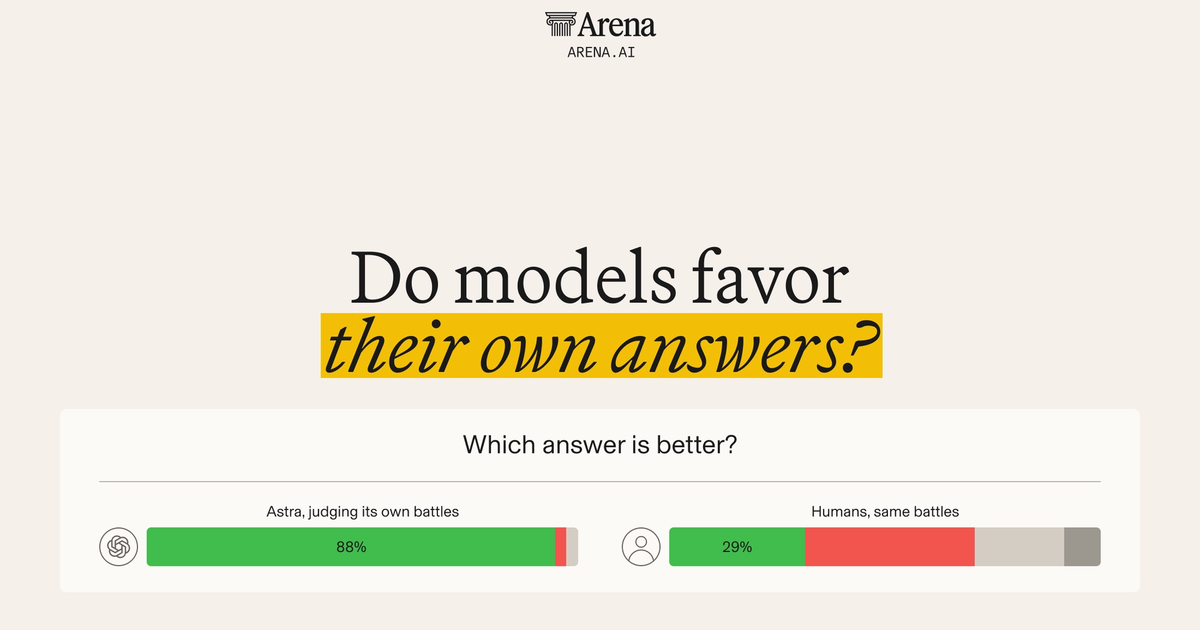
Across 12 LLMs, judges picked their own answer 58% of the time versus 34% for humans — about 70% more self-preference. Astra backed itself in 88% of battles and Fable in 72%; OpenAI-family judges rated OpenAI models 37 points above human ratings.
1 source
More stories today
Geometry Duo for ComfyUI adds depth and normal guidance
Two ComfyUI nodes, ComfyUI-Depth-Anything-3 and ComfyUI-Lotus-2, target clean 'white models' and normal guidance for video diffusion workflows. The release names MiniMax H3 and Wan 2.1 as supported models.
r/ComfyUI·3 hours ago
Explainer video covers latent space behavior in diffusion models
A short explainer video walks through what a latent space is and how it behaves, made in response to a request on r/StableDiffusion. It is aimed at readers working with diffusion image models.
r/StableDiffusion·3 hours ago
Reddit user asks for prompt tips on MiniMax H3 character sheets
A r/StableDiffusion post asks which prompt to use with MiniMax H3's reference-video feature to make it read a character sheet as one person across different poses, angles, and distances.
r/StableDiffusion·3 hours agoReddit users seek consistent character replacement in Minimax video
A r/StableDiffusion thread asks for a reliable way to achieve the perfect motion and character replacement seen in recent AI videos using Minimax. The poster says Viggle and replacement LoRAs fall short of that quality.
r/StableDiffusion·3 hours ago
Developer compares Claude Opus 5.5 and Codex Sol 6.1 costs
A developer building an architecture/interior design SaaS reports paying $200/month for Claude and $100/month for ChatGPT while using Claude Fable/Opus for roughly 90% of the build, with Codex used occasionally. The post cites a large cost gap between Claude Opus 5.5 and Codex Sol 6.1 for scraping furniture and finishes into an internal catalogue.
r/OpenAI·3 hours agoBlog recounts a rough month for Codex users after GPT-6 Sol
The post chronicles 30 days of setbacks for Codex users: GPT-6 Sol shipped alongside Opus 5.5 but underperformed even the older Luna, and OpenAI cut usage on its $200 plan from 20x to 10x at the same price just before DevDay.
Hacker News·3 hours ago
Engineer calls Claude Code work "soul-sucking"
An engineer posting anonymously as voxium says Claude Code now generates specs, tests, tickets and reports, leaving staff working 12 to 13 hours a day "just to press enter." He says everyone from L1 to L7 engineers does the same thing, with no time to review output or resolve bugs.
Hacker News·3 hours ago
Lead dev asks when experienced engineers stop reviewing AI code
An 8-year lead dev on r/ClaudeAI describes moving from ChatGPT to Copilot to Claude Code, now running it through worktree-oriented IDEs, and says he no longer switches models with every update. He asks other experienced devs when they stopped reviewing everything the AI writes.
r/ClaudeAI·3 hours ago