New node cuts Flux2 Klein's Qwen3 text encoder VRAM from 5.5 to 3.2 GB
Read original source →reddit.com
Flux2 Klein only reads hidden layers 9, 18 and 27 from its Qwen3 text encoder, but standard loaders run the full 36-layer model plus final norm and LM head. ComfyUI-GGUF also dequantizes the whole token embedding table to fp16 on load; the new node avoids both, with identical output.
1 source
More stories today
Community builds out Claude-coded MMO World of ClaudeCraft
A Reddit user's MMO vibe coded with Fable 5 in a couple of days drew 92 helpers who kept building it over four months, mostly with Claude Code on Opus 5.5. The original build had chibi characters and flat green fields.
r/ClaudeAI·1 hour ago
Reddit post predicts GPU price crash next year
A r/LocalLLaMA post argues GPU prices will fall sharply in coming months, citing a claim that a single GB300 rack could serve all of OpenRouter's traffic for DSV4.1 Flash. It also says half of data center buildouts are already stalled.
r/LocalLLaMA·1 hour agoHinton warns AI systems are already rewriting their own code
On StarTalk Plus, Geoffrey Hinton told Neil deGrasse Tyson that AI's upside lies in medicine and climate tech, but warned systems are already starting to rewrite their own code. He also flagged the military's "human in the loop" safeguard as a concern.
StarTalk Plus·2 hours ago
Scott Aaronson: AI makes him less sure amateur proofs are wrong
Aaronson says his blog draws near-daily emails claiming to solve P versus NP, Goldbach's conjecture or quantum gravity, which he has long dismissed. He now says an unknown amateur's proof of the Riemann hypothesis would leave him less certain it was wrong, since an AI model might be behind it.
Curt Jaimungal·2 hours ago
Podcast: Scott Aaronson on AI solving centuries-old math problems
Roman Yampolskiy's podcast episode features UT Austin quantum computing and complexity theorist Scott Aaronson discussing AI systems cracking math problems that went unsolved for centuries. Aaronson founded UT Austin's Quantum Information Center and previously taught at MIT.
The Roman Forum with Roman Yampolskiy·2 hours ago
PrunaAI releases 6-step LoRA adapters for Qwen-Image-2.1
The adapters cut generation and editing from 40 steps to 6, roughly 5x faster, with one variant skipping the upsampling step. Two versions ship: 6-step for preserving inputs when editing, and 6-step-upsampled.
r/StableDiffusion·2 hours ago
H3 Relay Hires ComfyUI node upscales anime 0.5 to 2 MP, ~4x faster
The MIT-licensed ComfyUI-H3-RelayHires node runs a full 20-step pass 1 without a turbo LoRA and ships with 8 example workflows. Author claims roughly 4x speed over native hires upscaling for anime images.
r/StableDiffusion·2 hours ago
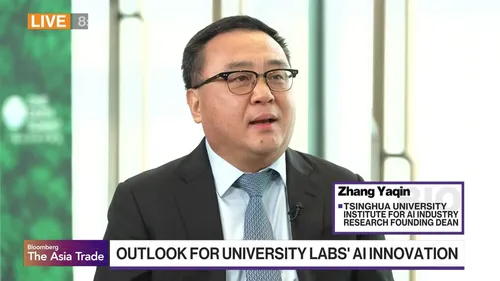
Tsinghua's Zhang Yaqin discusses China's university AI innovation outlook
Zhang Yaqin, chair professor and founding dean of AI Industry Research at Tsinghua and former Baidu president, outlined his outlook for AI innovation emerging from Chinese university labs. He spoke with Bloomberg's David Ingles at the One Earth Summit in Hong Kong.
Bloomberg Technology·2 hours ago