Apple's RLTL;DR lifts Qwen 3.5 9B Pass@1 from 0% to 12-13%
Read original source →machinelearning.apple.com
Apple researchers introduce RLTL;DR: after each failed attempt the policy writes a one-line TL;DR insight from verifier output, and the next rollout is conditioned on all prior insights. On tool-calling and coding sets filtered to Pass@128 = 0, GRPO training of a Qwen 3.5 9B Thinking policy stays at 0-1% Pass@1, while RLTL;DR reaches 14-31% with insights in context and 12-13% without them at eval.
1 source
More stories today
NVIDIA ships DOCA agent skills for BlueField DPU development
DOCA AI agent skills are now available on GitHub, packaging verified API signatures, hardware capability requirements, and build constraints into SKILL.md files. Skills span the DOCA library including Flow, GPUNetIO, and PCC.
NVIDIA Developer Blog·59 minutes ago

Harvard and Google DeepMind researchers discuss regulating physical AI
Runway·2 hours ago
AWS post details contextual bandits for personalization
AWS machine learning blog walks through using contextual bandits on AWS to lift conversion across the acquisition funnel, pairing them with generative AI personalization on Amazon Bedrock. The post follows an earlier one on producing personalized content at scale within brand guidelines and guardrails.
AWS AI Blog·2 hours ago
Shopify debuts Canvas, an AI chat-based store builder
Canvas lets merchants build and customize Shopify stores by chatting with the Sidekick AI agent, which renders the store's real code in real time rather than a static preview. Sidekick can now work directly with theme files, and takes screenshots to see the same view as the merchant.
TechCrunch·2 hours ago

CISO governance advice for shadow AI security blind spots
The New Stack column by John Sapp argues enterprises now face AI's "harsh reality" before finishing the hype phase, framing shadow AI as a governance and roadmap problem for CISOs.
The New Stack·2 hours ago

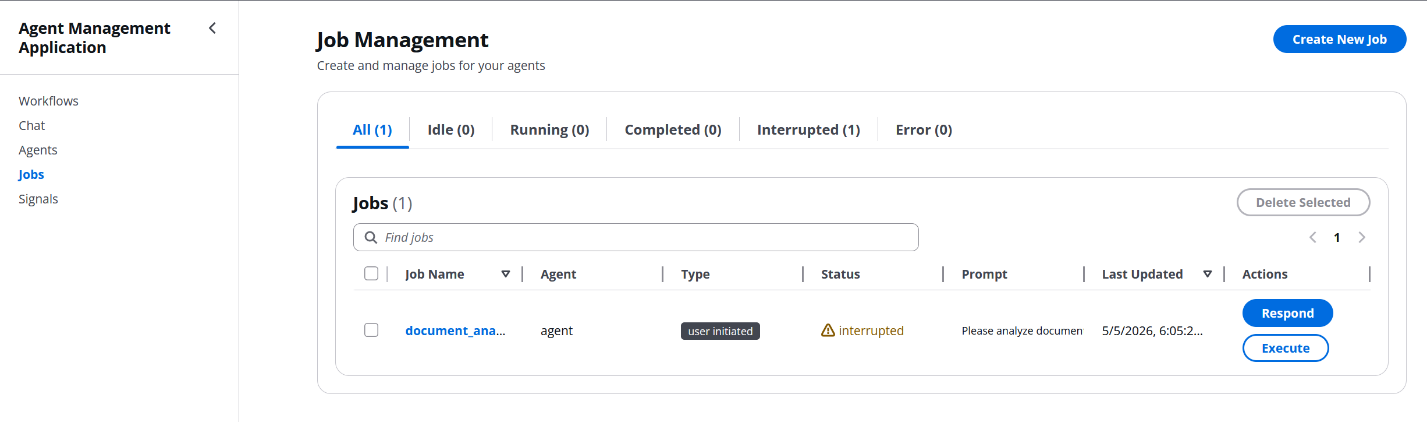
AWS shows ambient agents on Bedrock AgentCore
AWS post walks through building event-driven "ambient agents" on Amazon Bedrock AgentCore, from storage and alert signals to human-in-the-loop review. Aimed at teams doing document triage at scale.
AI Snake Oil essay argues x-risk warnings may be sincere but wrong
Arvind Narayanan's Normal Tech essay rejects both the "x-risk is imminent" and "it's a psyop" narratives, proposing a third: warnings are sincere but unsound and counterproductive to AI safety. It cites a 2019 WHO/World Bank report warning a respiratory pathogen could kill 50-80 million people, with adequate preparedness costing $1-2 per person per year.
AI Snake Oil·2 hours ago
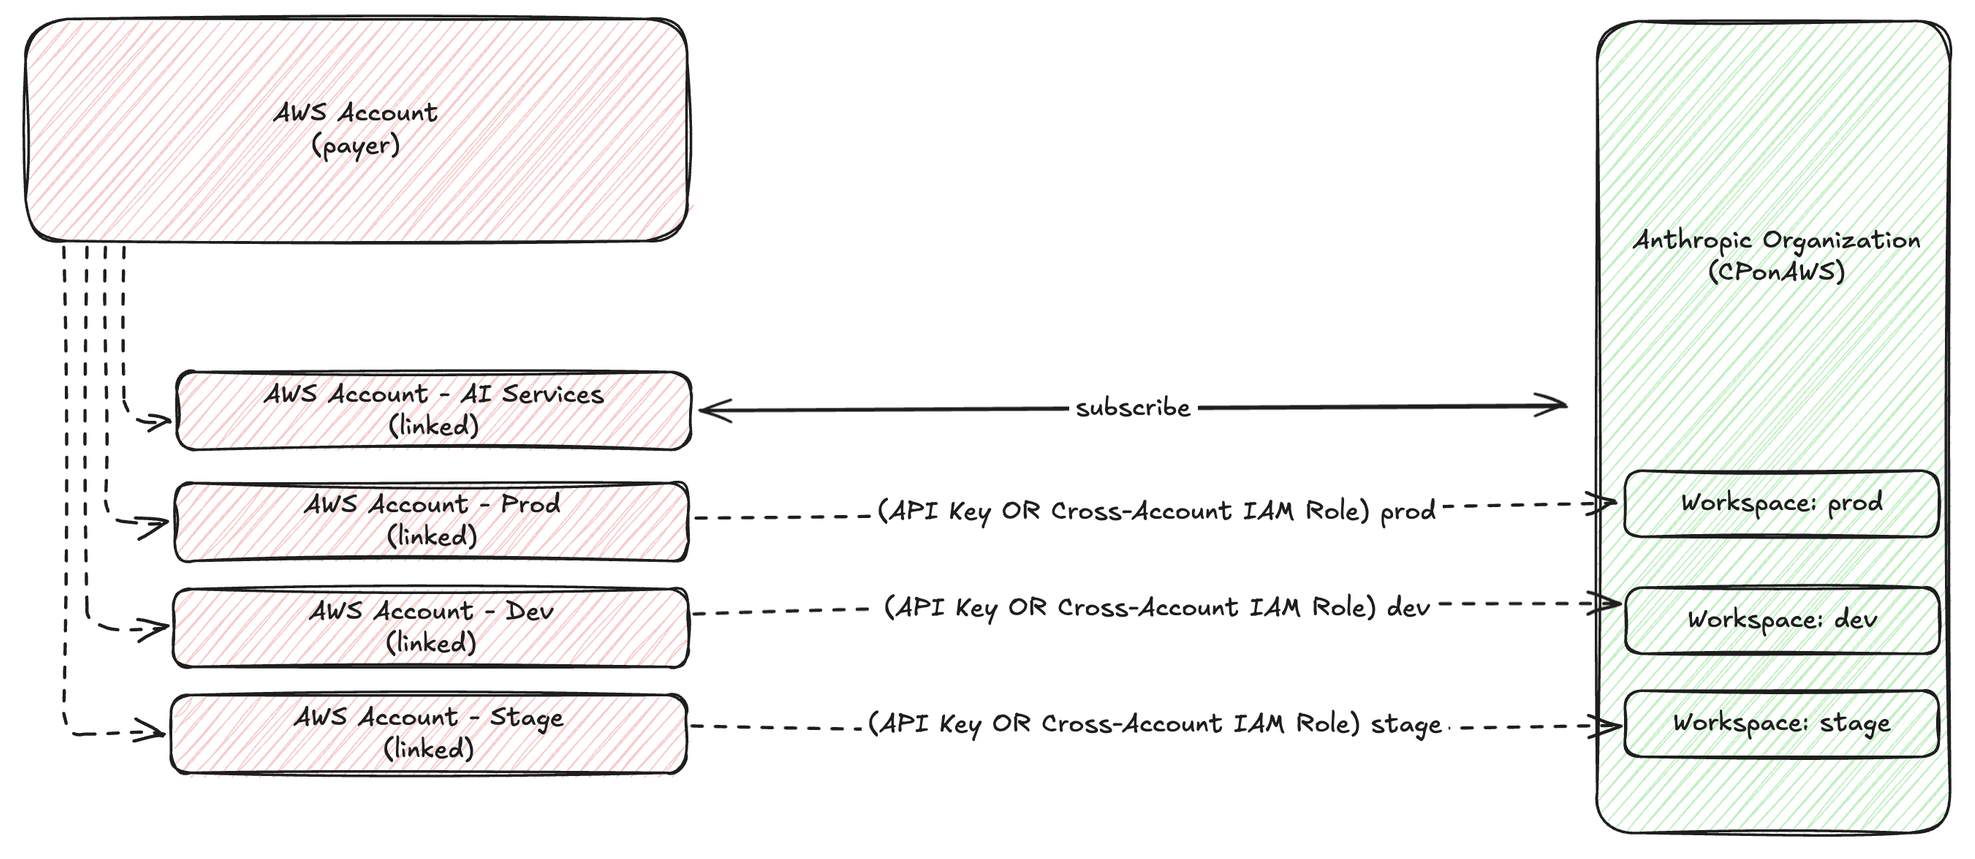
AWS blog details multi-environment access for Claude Platform on AWS
AWS published a technical how-to on giving Claude Platform on AWS (CPonAWS) inference to three environments: production workloads on AWS, developer laptops, and external services on other clouds or on-prem CI/CD pipelines.