ISTA-DASLab releases 2-bit GSQ-RCO quants of DeepSeek-V4.1-Flash
Read original source →huggingface.co
ISTA-DASLab's GSQ-RCO GGUFs compress DeepSeek-V4.1-Flash-1017 to 1.75–2.25 bits per weight; the base model is a 763.2B-parameter sparse MoE with 384 routed experts (6 active per token) and a 1M-token context. Reddit users question the benchmarks, noting AIME25 scores 100 for every version and no KLD data is published.
How this story unfolded
1 day · 1 report · 3 community posts · from Oct 24
More stories today
Reddit user reports Qwen 3.8 FN matched frontier cloud model on private task
A Reddit poster says Qwen 3.8 FN solved a work problem requiring local-model privacy with the same skill as a frontier cloud model. The task involved tracking students and supervisors for an MSc dissertation module.
r/LocalLLaMA·3 hours agoLocalLLaMA builders squeeze Qwen3.8-Flash-Next onto consumer hardware
Community inference engines and quants run the 125B–177B MoE model on setups as small as 8 GB VRAM plus 32 GB RAM, with one report hitting 900 t/s prompt processing and 30 t/s generation. capy-flash v0.7.1 runs the 125B model in 64 GB RAM at 234 tok/s on two 16 GB cards.
r/LocalLLaMA·3 hours ago
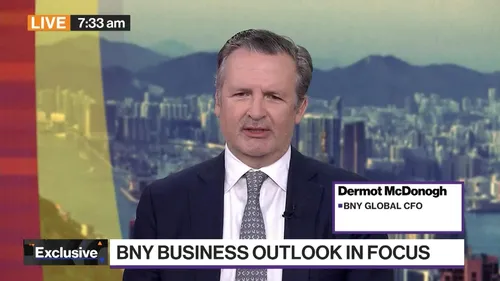
BNY CFO says bank is monitoring AI spend to avoid overspending
BNY Global CFO Dermot McDonogh said he is monitoring the bank's AI spending to avoid overspending on related tools, in an interview with Bloomberg's Paul Allen and Haidi Stroud Watts. He also discussed the bank's growth and business strategy outlook.
Bloomberg Technology·5 hours ago
OpenAI's dots assistant grew out of its coding tools
OpenAI released dots at its late-September developer day; it's available in ChatGPT desktop and mobile to Pro-tier subscribers and up, with plans starting at $100/month. Enterprise product lead Alexander Embiricos said much of dots' functionality was already reachable via the Codex coding app, but required more hand-holding.
TechCrunch·6 hours ago

NYT profiles Marissa Mayer's AI startup Dazzle
The New York Times Style section profile, by Alexandra Alter, centers on Mayer struggling with a task for her daughter Marielle's 10th birthday before turning to her new AI startup Dazzle. Daring Fireball's John Gruber criticizes the piece's framing of Mayer.
The New York Times·7 hours ago
AI security benchmarks proliferate but none cover the whole picture
A growing patchwork of AI security benchmarks each measures different variables, and none substitutes for testing models against your own code and workflows, Dark Reading reports.
Dark Reading·7 hours ago

Reddit post predicts Qwen-3.8-FN agents will sweep ARC-AGI-3 Kaggle
A r/LocalLLaMA post claims all winning notebooks in this year's ARC-AGI-3 Kaggle competition will be Qwen-3.8-FN agents unless something changes within a week. The author hedges that the model's capabilities are only "supposedly" established.
r/LocalLLaMA·8 hours agoReddit user switches from Gemini to Claude for coding
A developer who started with ChatGPT and moved to Gemini 1.5 Pro says they regret not trying Claude sooner for AI-assisted coding. The post describes directing the model on functions and design systems rather than pure vibe coding.
r/ClaudeAI·8 hours ago