Qwen3.8 Flash Next 176B runs on 16GB laptop GPU via SSD offload
Read original source →github.com
Two r/LocalLLaMA builders ran the 176B/177B MoE model on consumer hardware: an RTX 3080 Laptop with 16GB VRAM and 32GB RAM using TensorSharp, and an RTX 5070 12GB with 32GB DDR4 hitting 11.5 tok/s, up from ~7 tok/s, via llama.cpp expert streaming.
2 sources
More stories today
Reddit user says Qwen3.8 Flash Next fixed a GNOME extension
A LocalLLaMA poster reports using Qwen3.8 Flash Next in "DeepSeek Harness" to repair the Dash2Dock Lite GNOME extension after a major GNOME update broke it, restoring their dock in about an hour.
r/LocalLLaMA·1 hour ago
LangChain's Harrison Chase touts Managed Deep Agents vision
Harrison Chase·1 hour ago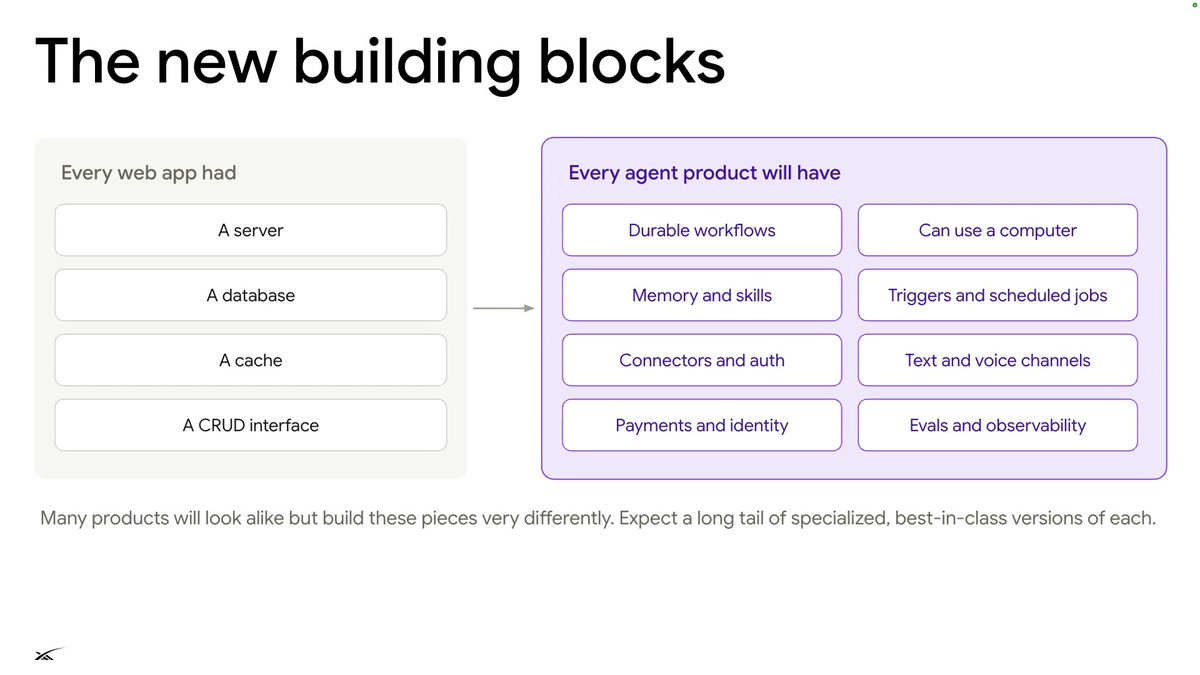
Talk shows self-learning loops for AI agents
Arize AI's Fuad Ali walks through a Wonder Toys shopping assistant that returned out-of-budget products because its price filter was broken, using the failure to demo a loop: collect the trace, investigate the code, propose a fix, and test it.
YouTube·1 hour ago
Developer builds web app to turn images into Gaussian Splats
The tool targets orbit-style videos from video models such as Minimax H3 in ComfyUI as input for Gaussian Splatting, skipping the usual COLMAP, trainer, and CUDA setup.
r/StableDiffusion·2 hours ago
Google DeepMind's Thor Schaeff demos building live voice agents with Gemini
Thor Schaeff, who works on developer experience at Google DeepMind, runs live demos of Gemini's real-time and media models, building an illustrated story with Gemini Live. The talk covers agents that hear, see, and answer in the user's language in real time.
YouTube·2 hours ago
AWS engineers demo Strands Agents customer service workflow
AWS's Elizabeth Fuentes Leone and Sandhya Subramani build a customer service agent that looks up accounts, checks orders, and handles refunds using Strands Agents. The talk focuses on controlling what happens between those steps and keeping that control in production.
YouTube·2 hours ago
Talk on AI development slides shared
Harrison Chase·2 hours ago
Reddit thread debates skepticism over AI coding quality
A r/ChatGPT post argues critics still repeat 2024-era claims that AI code is buggy and unmaintainable, citing Windows, the Linux kernel, Debian and Chromium as counterexamples. The poster also points to AI-enabled projects like anyps5 and Adobe-style art tools.
r/ChatGPT·2 hours ago