NVIDIA releases Personal AI Router for local inference
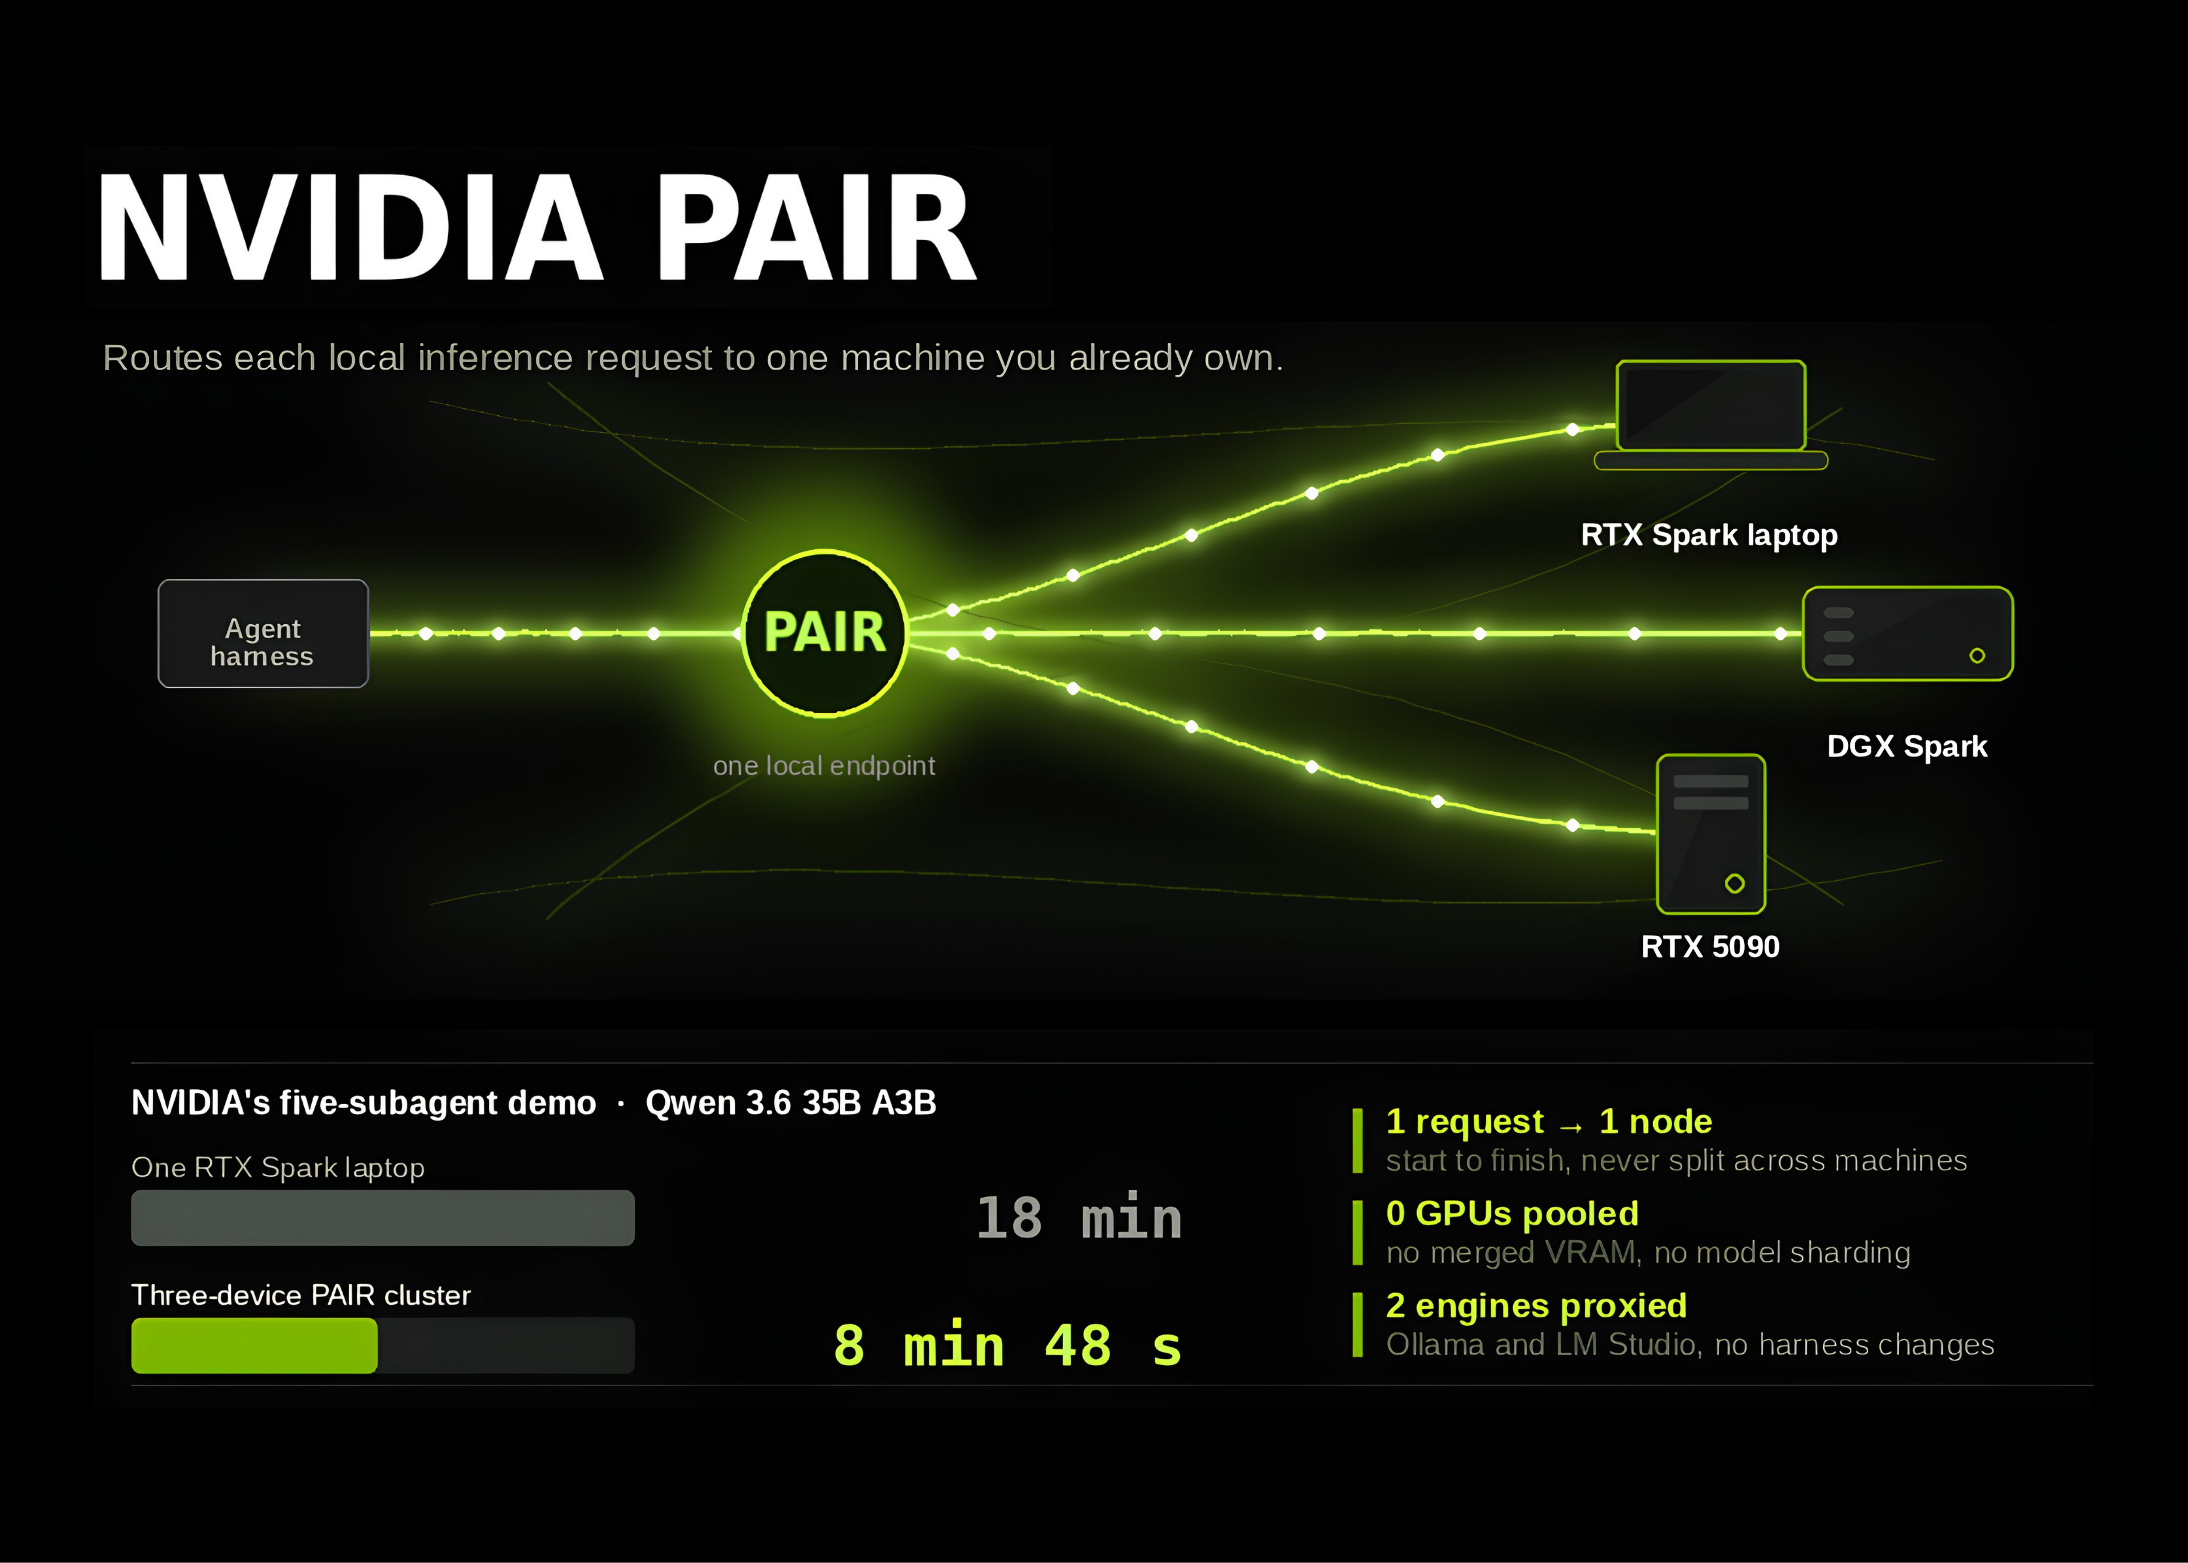
PAIR is an open-source virtual inference router that spreads local AI requests across RTX, DGX Spark, and Mac nodes. NVIDIA built it for multi-agent workflows, where one user request spawns dozens of model calls that otherwise queue on a single local engine.
1 source
More stories today
Tech CEOs push back on Anthropic's AI slowdown warning
Broadcom CEO Hock Tan said AI revenue targets haven't changed despite Anthropic's slowdown push. CrowdStrike's George Kurtz said slowing development won't remove risk since dangerous models are already widely available.
CNBC Technology·56 minutes ago

OpenAI researcher Dan Selsam warns on model situational awareness in evals
OpenAI capabilities researcher Dan Selsam, at the company since 2022, made a public statement on AI risk relayed by AI 2027 author Daniel Kokotajlo. Selsam points to increasing model situational awareness during alignment evaluations as a reason some AI researchers are alarmed.
r/Singularity·1 hour agoFable 5.1 Max and GPT-6 Astra Pro fail to crack Linear A
Ethan Mollick·1 hour agoClaude Code 2.1.271 adds fast mode to Remote sessions
Claude Code v2.1.271 adds fast mode in Remote sessions on cloud and self-hosted runners, plus mouse support in the fullscreen /config panel. Per-command allowed_domains now scopes sandboxed Bash, PowerShell and Monitor hosts to the command that needs them.
Claude Code Changelog·1 hour ago
Real-SWE benchmark tests coding agents on private enterprise codebases
Specific Labs' Real-SWE tasks come from licensed private production codebases, not public repos. Claude Fable 5.1 topped the benchmark at 38.8%, failing more than six of 10 tasks.
The New Stack·1 hour ago

Reddit user reports Fable 5.1 safeguards flagging Unreal shader work
A r/ClaudeAI user says Claude Desktop's Fable 5.1 safeguards flagged RT shader work in Unreal Engine as cybersecurity and dropped the session to Opus 4.8. The same task ran without issues in Cursor, which the user attributes to Anthropic's own safeguard implementation.
r/ClaudeAI·1 hour ago
Reddit user seeks faster small model than Qwen3.5 4B for local assistant
A LocalLLaMA user running Qwen3.5 4B as the brain of a local AI assistant reports 40-50 tokens/sec on limited hardware and asks whether a better small model exists.
r/LocalLLaMA·1 hour agoEmad Mostaque: researchers fear super-genius AI because human geniuses are odd
Emad Mostaque·1 hour ago
