Guide compares decision models for automated evals
Read original source →hamel.dev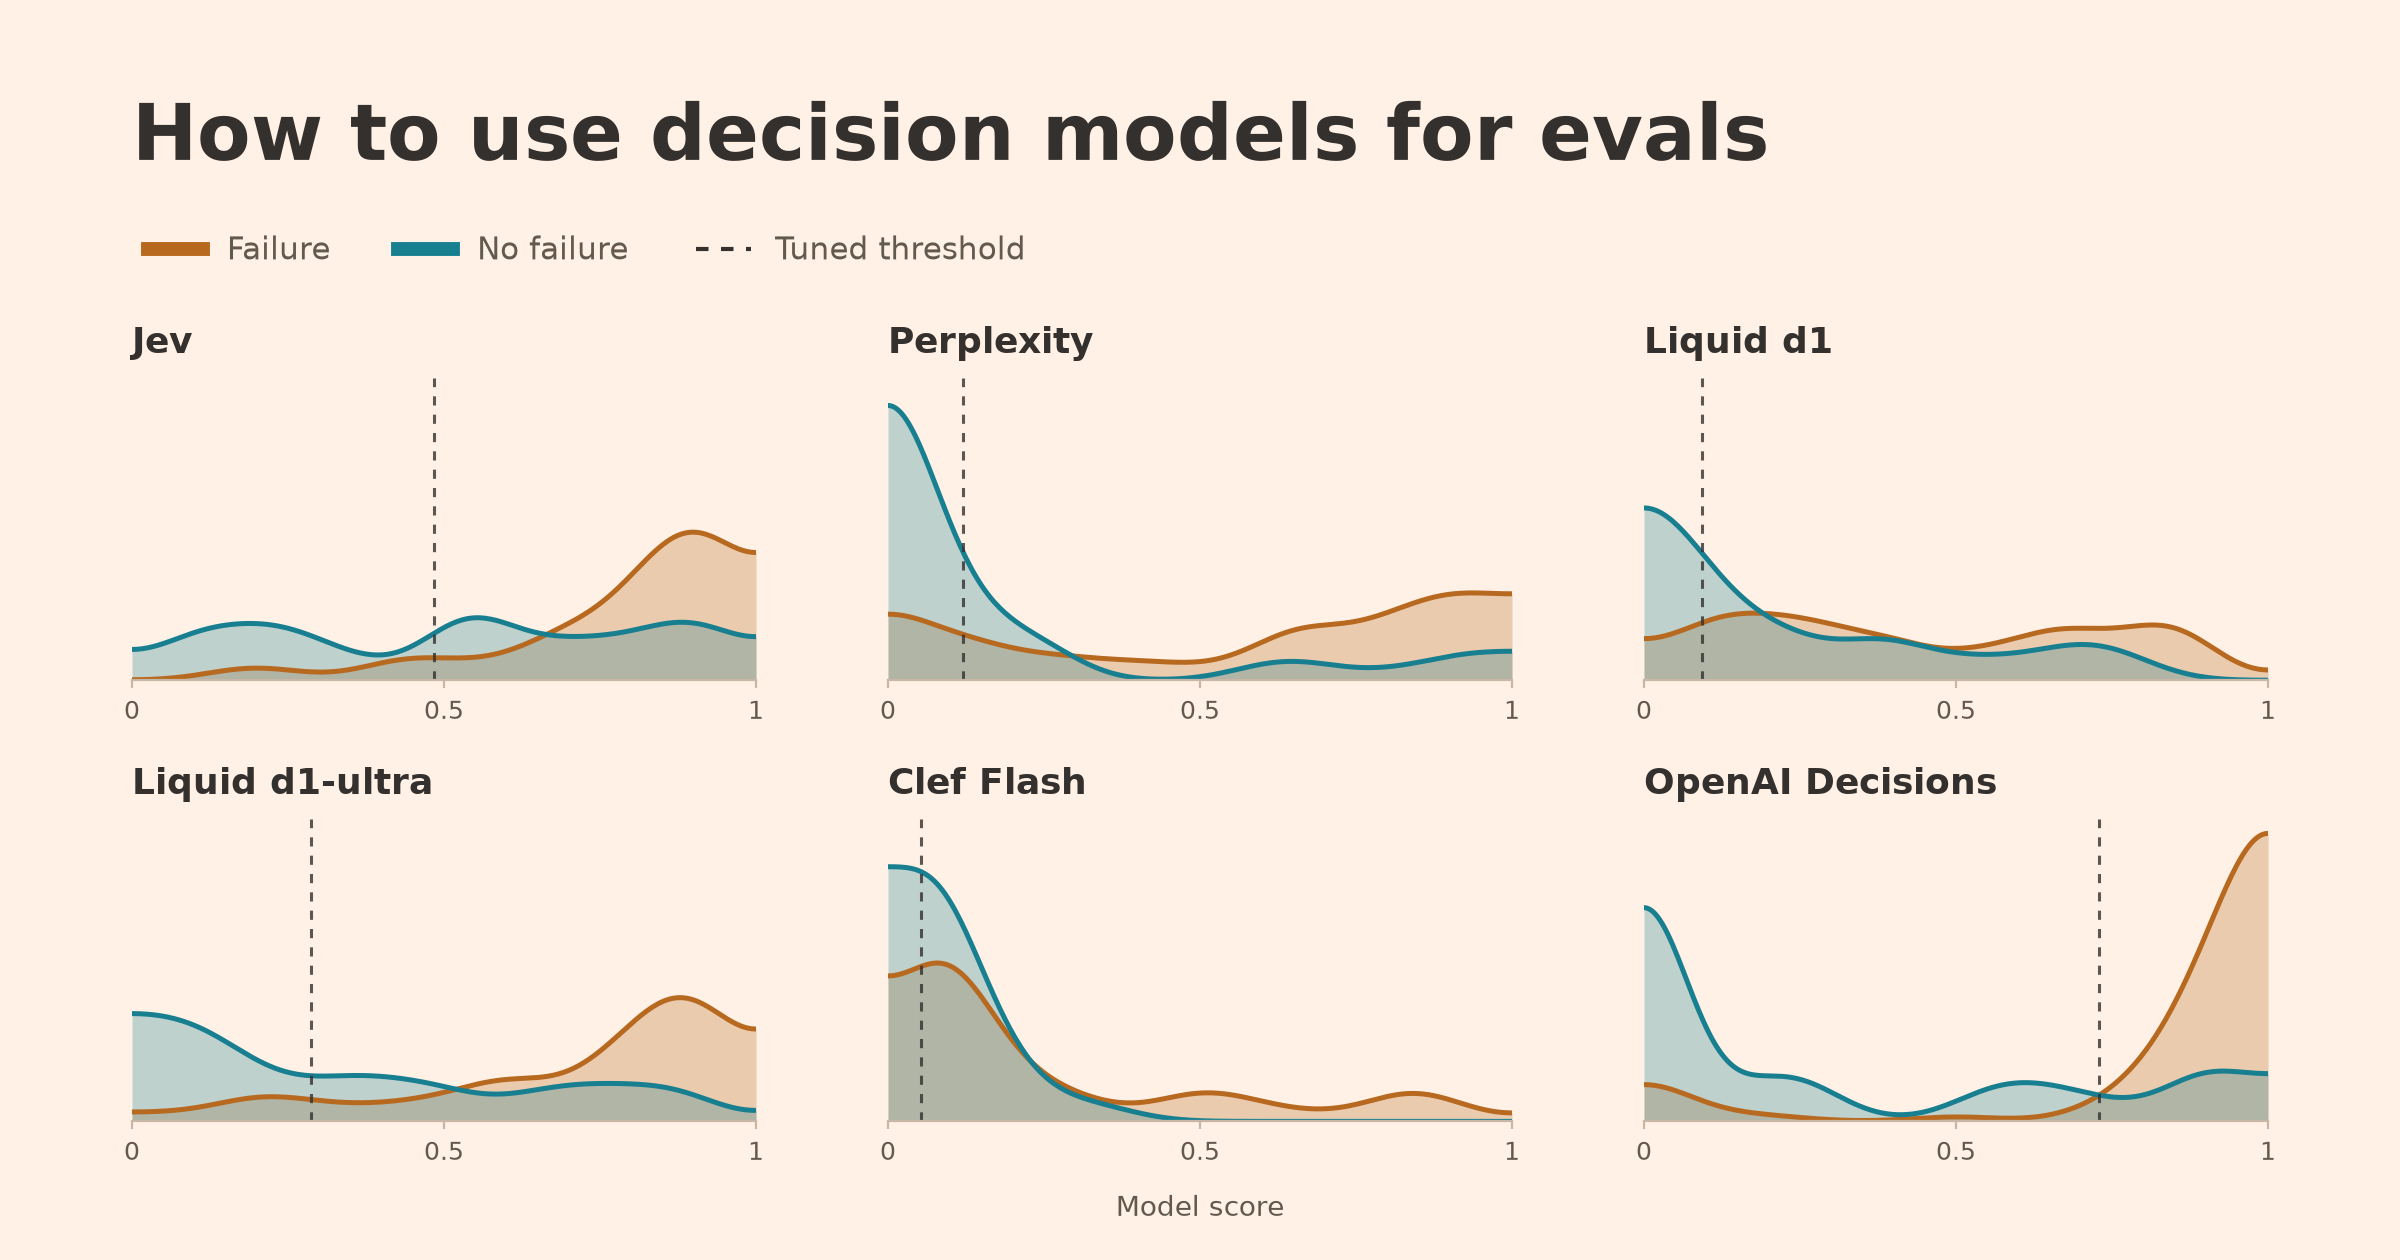
Hamel Husain post benchmarks Jev 1.13, Perplexity Decider 1.1 27B, Liquid d1/d1-ultra, Cloudflare Clef Flash and OpenAI Decisions (GPT-6 Luna) on 100 apartment-leasing agent traces for failure detection. It argues the default 0.50 threshold leaves performance on the table and covers calibration of scores as confidence estimates.
1 source
More stories today
LangChain's Learning Loop talks tackle continual learning
LangChain·1 hour ago
SEC names AI 'super intelligence' a systemic market risk for FY2027
The SEC's Division of Examinations added "super intelligence and other advanced technologies" to its FY2027 exam priorities, covering more than 34,000 registrants. Tokenization was listed separately under market infrastructure risks alongside Treasury clearing reforms.
Decrypt·1 hour ago
Claude adds MCP Tasks and Elicitations support
Claude Developers·1 hour ago
GPT SOL 6.1 builds 3D axe in Blender via MCP in 7 minutes
Max·2 hours ago
Reddit thread debates which tasks AGI should tackle first
A r/Singularity post argues AGI is "more likely to happen in 2-24 months than ever" and asks what it should solve first beyond global warming, with the poster's own pick being low-impact energy work. No concrete model, benchmark, or lab result is cited.
r/Singularity·2 hours agoReddit user points to Alignment Forum guide on becoming a mech-interp researcher
A r/ChatGPT post links an Alignment Forum post, "How to Become a Mechanistic Interpretability Researcher," as the starting point for getting into the field, with learning Python as the first step.
r/ChatGPT·2 hours ago
Mystery AI Hype Theater 3000 episode to cover AI in sports
Emily M. Bender·2 hours agoAi2 attends EMNLP 2026 with papers and talks
Allen Institute for AI (Ai2)·2 hours ago

