Explainer: speculative decoding speeds LLMs by shifting GPU work, not cutting it
Read original source →jbarrow.ai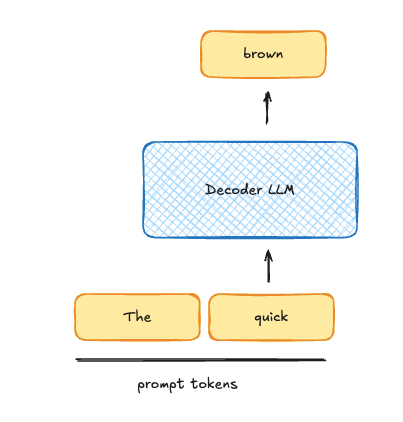
Speculative decoding executes more total FLOPs per sequence, not fewer — a small draft model proposes tokens that the big model verifies in one parallel forward pass. The gain comes from moving the GPU off memory-bound single-token decoding, where all active parameters (e.g. 27B for Qwen3.5-27B) must be streamed per token.
1 source
More stories today
AI21 pitches open models post-trained on customer data
AI21 Labs·2 hours ago
Just 4 Noise launches ethically-trained AI kick-drum generator
Berlin-based Just 4 Noise trained Just 4 Kicks on fully owned, in-house audio recorded in studios worldwide over months. It costs €79 upfront with free future updates, and Just 4 Snares, Just 4 Hats and Just 4 Drums are planned next.
Music Ally·2 hours ago

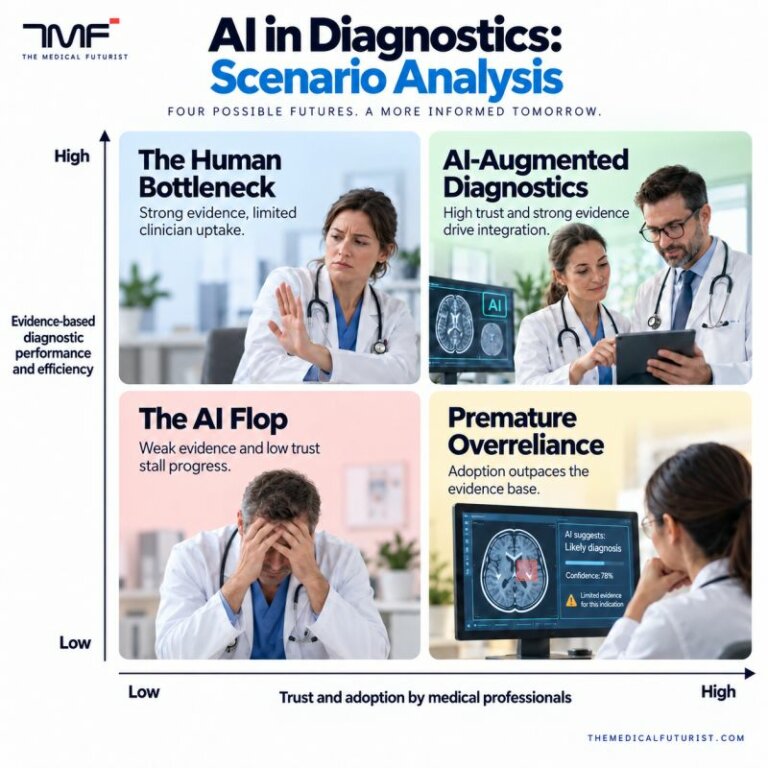
The Medical Futurist maps four scenarios for AI in diagnostics
Scenario analysis uses evidence-based diagnostic performance as the driving force and clinician trust and adoption as the major uncertainty. The piece argues healthcare needs a workforce that understands AI well enough to use it appropriately.
The Medical Futurist·2 hours ago
Reddit user reports Qwen 3.8 Flash Next faster, more precise
A r/LocalLLaMA post describes Qwen 3.8 Flash Next as drastically faster and more precise at reaching results when generating Python-drawn paintings. The model reportedly self-checks its first draft and adds corrections quickly.
r/LocalLLaMA·2 hours agoBiohub's Alex Rives discusses virtual cells and $1.8B data push
Podcast interview with Alex Rives, Head of Science at Biohub and former lead of the ESM protein language model project, on building a predictive world model of life. The effort is backed by an expanded $1.8 billion Virtual Biology Initiative with partners including the Department of Energy.
YouTube·2 hours ago
Otter.ai raises $320M from General Catalyst growth fund
The $320M comes from General Catalyst's Customer Value Fund, which supplies capital without diluting equity and earns returns on marketing results. Otter has raised just $50M total before this, crossed $100M ARR last year, and claims 40M users to date, up from 25M.
TechCrunch·2 hours ago

Yelp adds AI voice agent that calls restaurants to check wait times
Yelp's "Check for Me" feature lets users enter party size and phone number, then an AI agent calls the restaurant and texts back wait times. The app also gains an OpenTable booking integration, 30-day chat history, and custom reminders.

Vals AI: DeepSeek V4.1 Flash 1017 tops GPT 6 Sol on offensive security task
Vals AI reports DeepSeek V4.1 Flash 1017 beat GPT 6 Sol on its multi-step offensive cybersecurity task. Sol was evaluated through the Daybreak trusted access program.
r/LocalLLaMA·2 hours ago