Apple introduces DLR-Lock to protect pretrained model weights

DLR-Lock replaces standard MLP layers with deep low-rank residual networks to increase backpropagation memory overhead. This method creates architectural mismatches that complicate fine-tuning for unauthorized users while maintaining the original model's performance.
1 source
More stories today
Mollick: language drift, not errors, is the worst part of long agentic runs
Ethan Mollick·2 hours agoAlexandr Wang: Muse is "pretty insanely good"
Alexandr Wang·2 hours agoReddit post claims hospitals adopting AI fastest saw fewest deaths in 2026
A r/Singularity post cites a Hedgeye X post claiming hospitals that adopted AI fastest recorded the fewest deaths so far in 2026. No study, dataset, or named hospital system is provided in the cluster.
r/Singularity·2 hours ago
Reddit thread debates financial security if AI agents take over the internet
A r/Singularity poster notes they hold almost no physical cash, with checking, brokerage, stocks and retirement all existing as online numbers, and asks how that money is protected if AI agents take over the internet.
r/Singularity·3 hours agoReddit user benchmarks Qwen 3.8 27B on triple RTX 3090 setup
A r/LocalLLaMA user running Qwen 3.8 27B at UD-Q8_K_L across two RTX 3090s in tensor parallel reports it as the best fit for a 3x 3090 rig, after previously avoiding low-bit quantization and quantized KV cache.
r/LocalLLaMA·3 hours ago
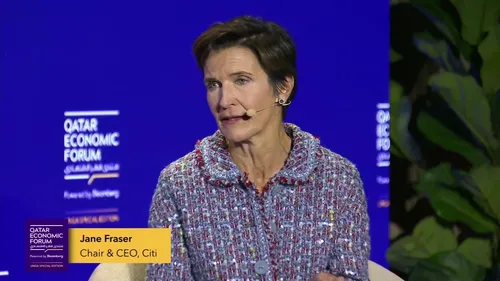
Citi CEO Jane Fraser Warns of 'Tsunami' of AI Security Patching
Citigroup CEO Jane Fraser said companies are racing to build defenses against AI models, describing a coming "tsunami of patching." She said when "Mythos" came out, "that was not a good day."
Bloomberg Technology·3 hours ago
Harrison Chase: "Decision Model" names a new model class
Harrison Chase·3 hours ago
llama.cpp PR enables sparse flash attention for Qwen4 on CUDA
Pull request #28770 by am17an adds sparse flash-attention support for Qwen4 in ggml-org/llama.cpp's CUDA backend, described as another Qwen Flash Next speedup.
r/LocalLLaMA·4 hours ago