Student's handwritten essay flagged 72% AI by Turnitin
Read original source →reddit.comA Reddit user says a four-page essay they wrote was flagged by Turnitin at 72% AI, prompting a professor email. They ask how to prove they did the work themselves.
1 source
More stories today
Community merges two Minimax-H3 finetunes with PRISM algorithm
A Reddit user combined Minimax-h3_Singularity v2 with 10Eros-Max (8-Step Turbo beta 6) using a custom spectral/geometric merge method called PRISM. The post notes that merging fast turbo models into base models often introduces artifacts.
r/StableDiffusion·3 hours ago
Quinn Slack: models fixed SvelteKit hydration jitter over hours
Quinn Slack·3 hours ago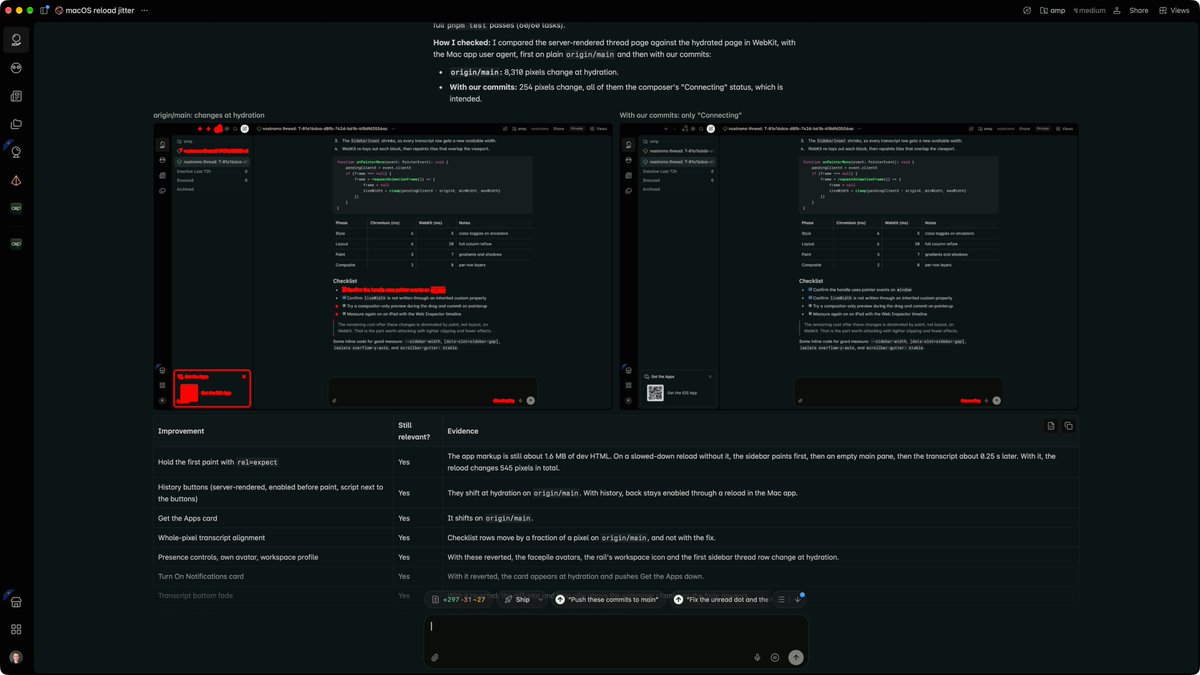
Deedy Das: inference providers hit $1M/mo fast on open models
Deedy Das·3 hours ago
ComfyUI users discuss an RTX unlock for 3090 and 4090 cards
A r/ComfyUI thread asks for a plain-language explanation of a rumored "unlock" affecting RTX 3090 and 4090 GPUs, with the poster using a car-speed analogy. No technical details, benchmarks, or official confirmation appear in the post.
r/ComfyUI·3 hours agoKepler's Vinoo Ganesh: models cite numbers but never write them
Kepler's architecture has retrieval find the source and deterministic code do the math, so models never generate figures themselves. A post-processing filter strips any number the model invents, a constraint Ganesh ties to finance's rule that you never show a figure you can't trace.
YouTube·5 hours ago
Claude Code patches Flight Simulator 95/98 to run on 64-bit Windows
A longtime Flight Simulator fan used Claude Code to get FS95 and FS98 running on 64-bit Windows, after seeing it mash up unrelated games without breaking them.
r/ClaudeAI·5 hours ago
SoftBank's Son plans $50B Malaysia tech outlay, PM says
Masayoshi Son chose Malaysia sites for $50 billion in technology investments, per the country's prime minister, accelerating his global bet on AI infrastructure.
Bloomberg Technology·5 hours ago
Kaggle Benchmarks lead: most AI benchmarks don't reflect real work
Janie Gu, who leads Kaggle Benchmarks at Google DeepMind, says benchmarks are expensive to keep current and their scores can't be verified. After reproducing 65 industry benchmarks, Kaggle found models reading other answers.
YouTube·6 hours ago