Test pits 10 coding agents against Qwen 3.8 27B on one llama-server
Read original source →reddit.com
Run on a MacBook Pro M5 Max with 64 GB, Qwen 3.8 27B Q4 in llama.cpp with thinking off, across 5 small coding tasks each containing a trap. Token use and cache reuse varied more between agents than pass rates did.
1 source
More stories today
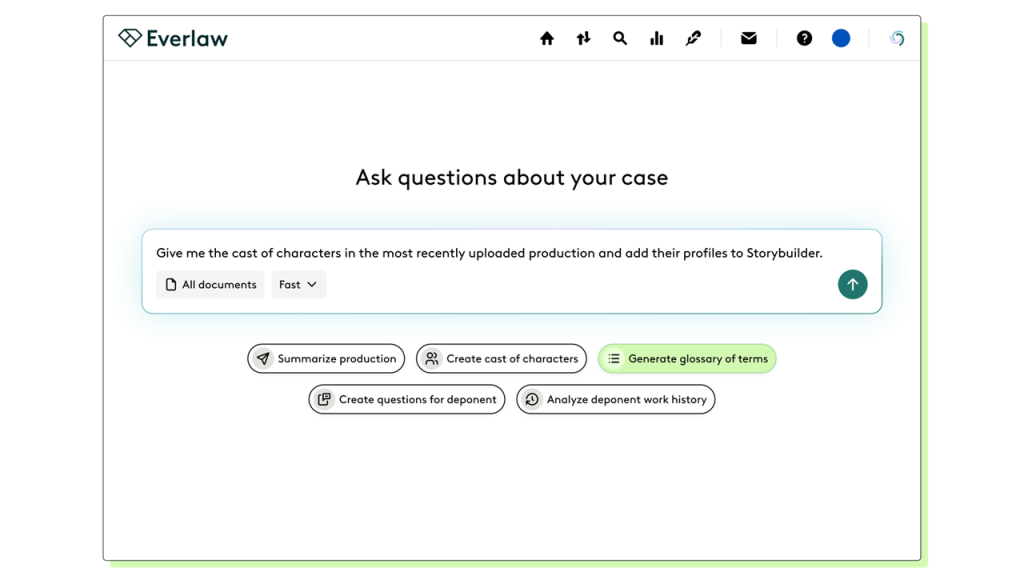
Everlaw launches Omni agentic AI suite and MCP connectors
Everlaw unveiled Omni, an agentic investigation suite that subsumes its Deep Dive tool, plus drag-and-drop Workflows and an Everlaw for Word add-in. CEO AJ Shankar said the bigger news is "Everlaw Everywhere" — free MCP connectors to Claude, ChatGPT, Copilot, Gemini, Harvey and Legora, with MCP usage more than doubling monthly.
LawSites·1 hour ago
Post claims Anthropic blocks game-based benchmarks like Minecraft
Kimmonismus·1 hour ago
Speridlabs' idol turns a single image into a 3D Gaussian splat
Idol converts one photo, render, or generated image into up to 1,048,576 Gaussians written as a standard 3DGS .ply, after removing the background and framing the object. It runs on consumer GPUs at 7.2 GB of VRAM.
Suvaditya Mukherjee·1 hour ago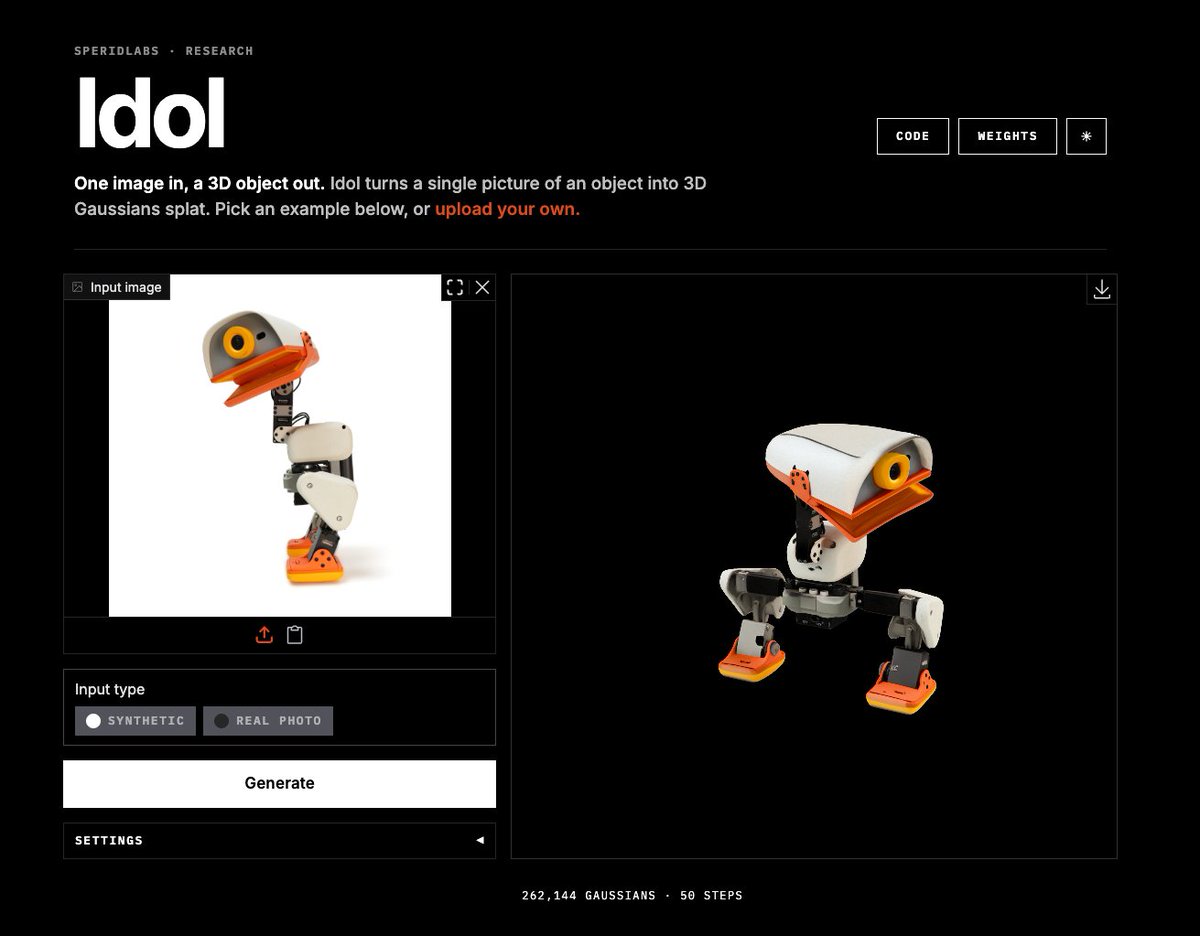
GLM 5.3 can autonomously compromise recent Firefox versions
Epoch AI publication on the open-weight models patch gap cites GLM 5.3 autonomously compromising recent versions of Mozilla Firefox. The Reddit post links to the Epoch AI report as the source.
r/artificial·1 hour ago
UMG's Grainge warns AI music volume outpaces safeguards
UMG CEO Sir Lucian Grainge cited Deezer data showing over 90,000 fully AI-generated tracks uploaded to streaming services daily. He said as many as five of the top 10 blues albums on some services come from AI acts without clear labeling, and called for de-monetizing AI slop.
Music Ally·1 hour ago

Microsoft releases Mage-VL-Cowork on Hugging Face
Microsoft published Mage-VL-Cowork, a vision-language model, as a Hugging Face model release. The card carries no benchmark scores, parameter counts, or licensing details.
Hugging Face Models·2 hours ago

Community fine-tune gives Gemma 4 31B a more human chat style
The release ports the creator's Humanlike-Chat 2.0 method from Qwen3.8-27B to the official Gemma 4 31B base, after the earlier GGUF repo drew 136k downloads across v1 and 2.0. It was prompted by a top comment asking how Gemma 4 31B would do with the same training approach.
r/LocalLLaMA·2 hours ago
Grok Bot adds per-bot voice and language settings
TestingCatalog News·2 hours ago