New research papers propose methods to optimize visual token pruning in VLMs
Recent papers introduce techniques like RUTA, DIVE, and GSTEP to reduce the computational cost of processing long visual token sequences in vision-language models. These methods aim to improve inference efficiency for images and videos by optimizing how redundant tokens are identified and pruned.
How this story unfolded
4 days · 4 reports · from Aug 6
- Aug 6
- Aug 10
More stories today
Essay offers de-anthropomorphizing alternatives to "AI" language
Emily M. Bender and Nanna Inie propose replacing anthropomorphizing terms like "cognizer" and "artificial intelligence" with functionality-based descriptions, drawing on their paper Inie et al 2026. They outline three steps: noticing anthropomorphizing word choices, finding alternatives, and building the habit of using them.
Lobsters·2 hours ago
AI-powered 90s TV runs Codex via GPT Real Time
Riley Brown·2 hours ago
Alexandr Wang: "i'm engaging with you as a human being"
Alexandr Wang·2 hours ago
Angi names Michael Steib CEO to lead AI-focused turnaround
Angi Inc. appointed Michael Steib as chief executive officer to steer the digital home-improvement platform's push toward artificial intelligence.
Bloomberg Technology·3 hours ago
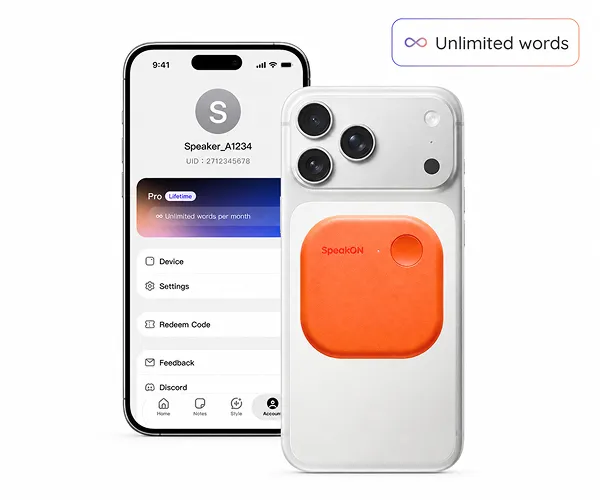
SpeakON ships MagSafe AI voice button with built-in microphone
SpeakON's hardware button attaches via MagSafe and captures voice through its own microphone, aiming to turn raw speech into polished text and actions across apps. The company frames the problem as output quality, not input: dictation tools return fillers and false starts that users must clean up and move elsewhere.
MarkTechPost·3 hours ago
Fable/Opus builds hard sci-fi starship combat game with orbital mechanics
Ethan Mollick·3 hours ago
Illinois governor Pritzker establishes AI cabinet to assess risks
Illinois Gov. JB Pritzker created an AI cabinet to assess risks and protect Illinoisans, per WGN-TV. The move drew criticism in r/LocalLLaMA, where a poster urged residents to contact the governor over what they called an attack on open weights.
r/LocalLLaMA·4 hours ago
NVIDIA AI Day Singapore showcases Southeast Asia AI push
NVIDIA AI Day Singapore runs Sept. 22-23 at the Raffles City Convention Centre, with partners showcasing AI work across Southeast Asia. Singapore's HTX will research public-safety AI using NVIDIA Nemotron 3 Super and Nemotron 3 Nano Omni models.
Nvidia AI Blog·4 hours ago