DFlash2 drafter for Qwen3.8-Flash-Next now works in llama.cpp
Read original source →huggingface.co
Community GGUFs of the DFlash2 drafter for Qwen3.8-Flash-Next now run in llama.cpp v0.8.0, the first release with DFlash2 support. The original authors report roughly 20% faster than MTP at concurrency 1; one tester measured +17% on average.
2 sources
More stories today
Score-centering RL paper compiles train-inference mismatch methods
Nathan Lambert·1 hour agoDatabricks and SAP partner on end-to-end enterprise data and AI
Databricks and SAP announced a joint push to connect data and AI capabilities end to end for enterprise AI transformation. The post argues capable models still lack the business context needed to deliver value.
Databricks Blog·1 hour ago

NVIDIA tutorial runs Nemotron-3.5 Lightning on DGX Spark via TensorRT Edge-LLM
The trtedge CLI downloads a model and builds TensorRT engines for Spark's new 64GB configuration, tested with TensorRT Edge-LLM 0.11.1 and TensorRT 10.16.1.11. DSpark speculative decoding speeds generation, and the same runtime deploys to Jetson Thor, DRIVE AGX Thor and IGX Thor.
NVIDIA Developer Blog·1 hour ago

Tweet outlines building an AI-native engineering org
A single X post by sgondala2, shared on Hacker News, sketches how to structure an engineering organization around AI. No concrete metrics, tooling, or case data appear in the available snippet.
Hacker News·2 hours agoNVIDIA Halos SAFE links road testing and simulation for AV safety
NVIDIA Halos SAFE AV connects real-world testing, simulation, and vehicle hardware into one continuous evaluation loop. Omniverse NuRec reconstructs real driving scenarios while Cosmos generates variations across traffic, weather, and edge cases.
YouTube·2 hours ago
vLLM adds PLE disk offload support on nightly builds
A merged vLLM pull request adds PLE disk offload, landing in nightly builds rather than a tagged release. The change lets PLE data be paged to disk instead of held in memory.
r/LocalLLaMA·2 hours ago
Vercel's fx coding agent hits v0.0.16 at 5.97 MiB
Guillermo Rauch·2 hours ago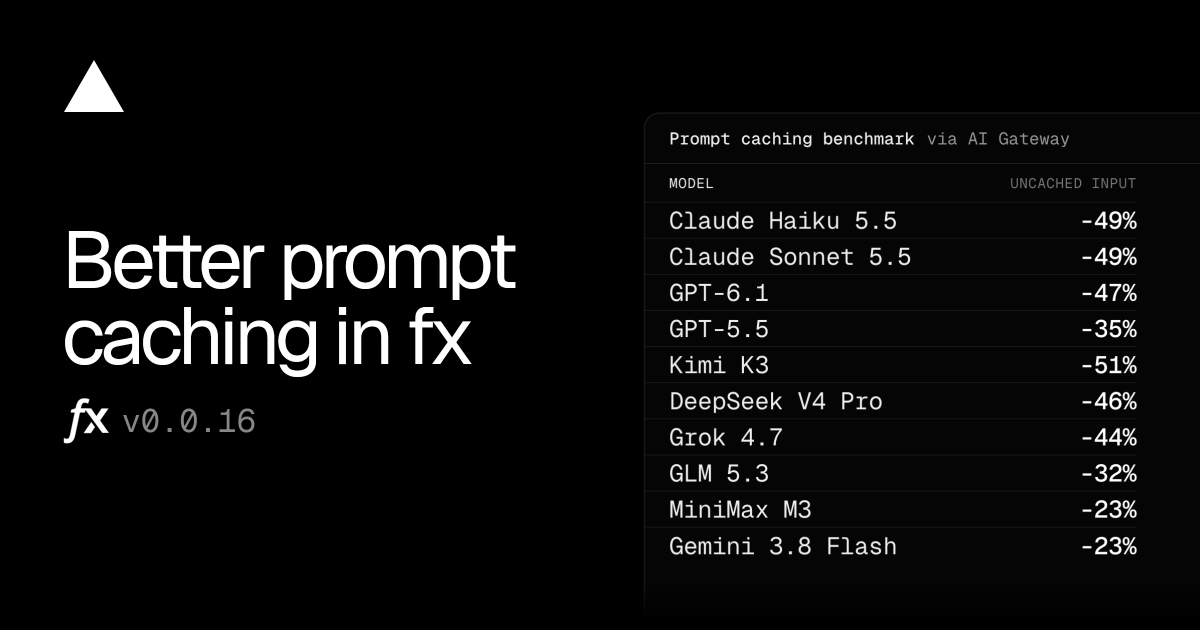
Databricks blog argues deliberate decisions drive enterprise AI value
Databricks' blog post frames rising expectations and spreading experimentation as the backdrop for its argument that enterprise AI value comes from deliberate decision-making rather than fast adoption.

