LangChain: How to monitor AI agents in production
Read original source →langchain.com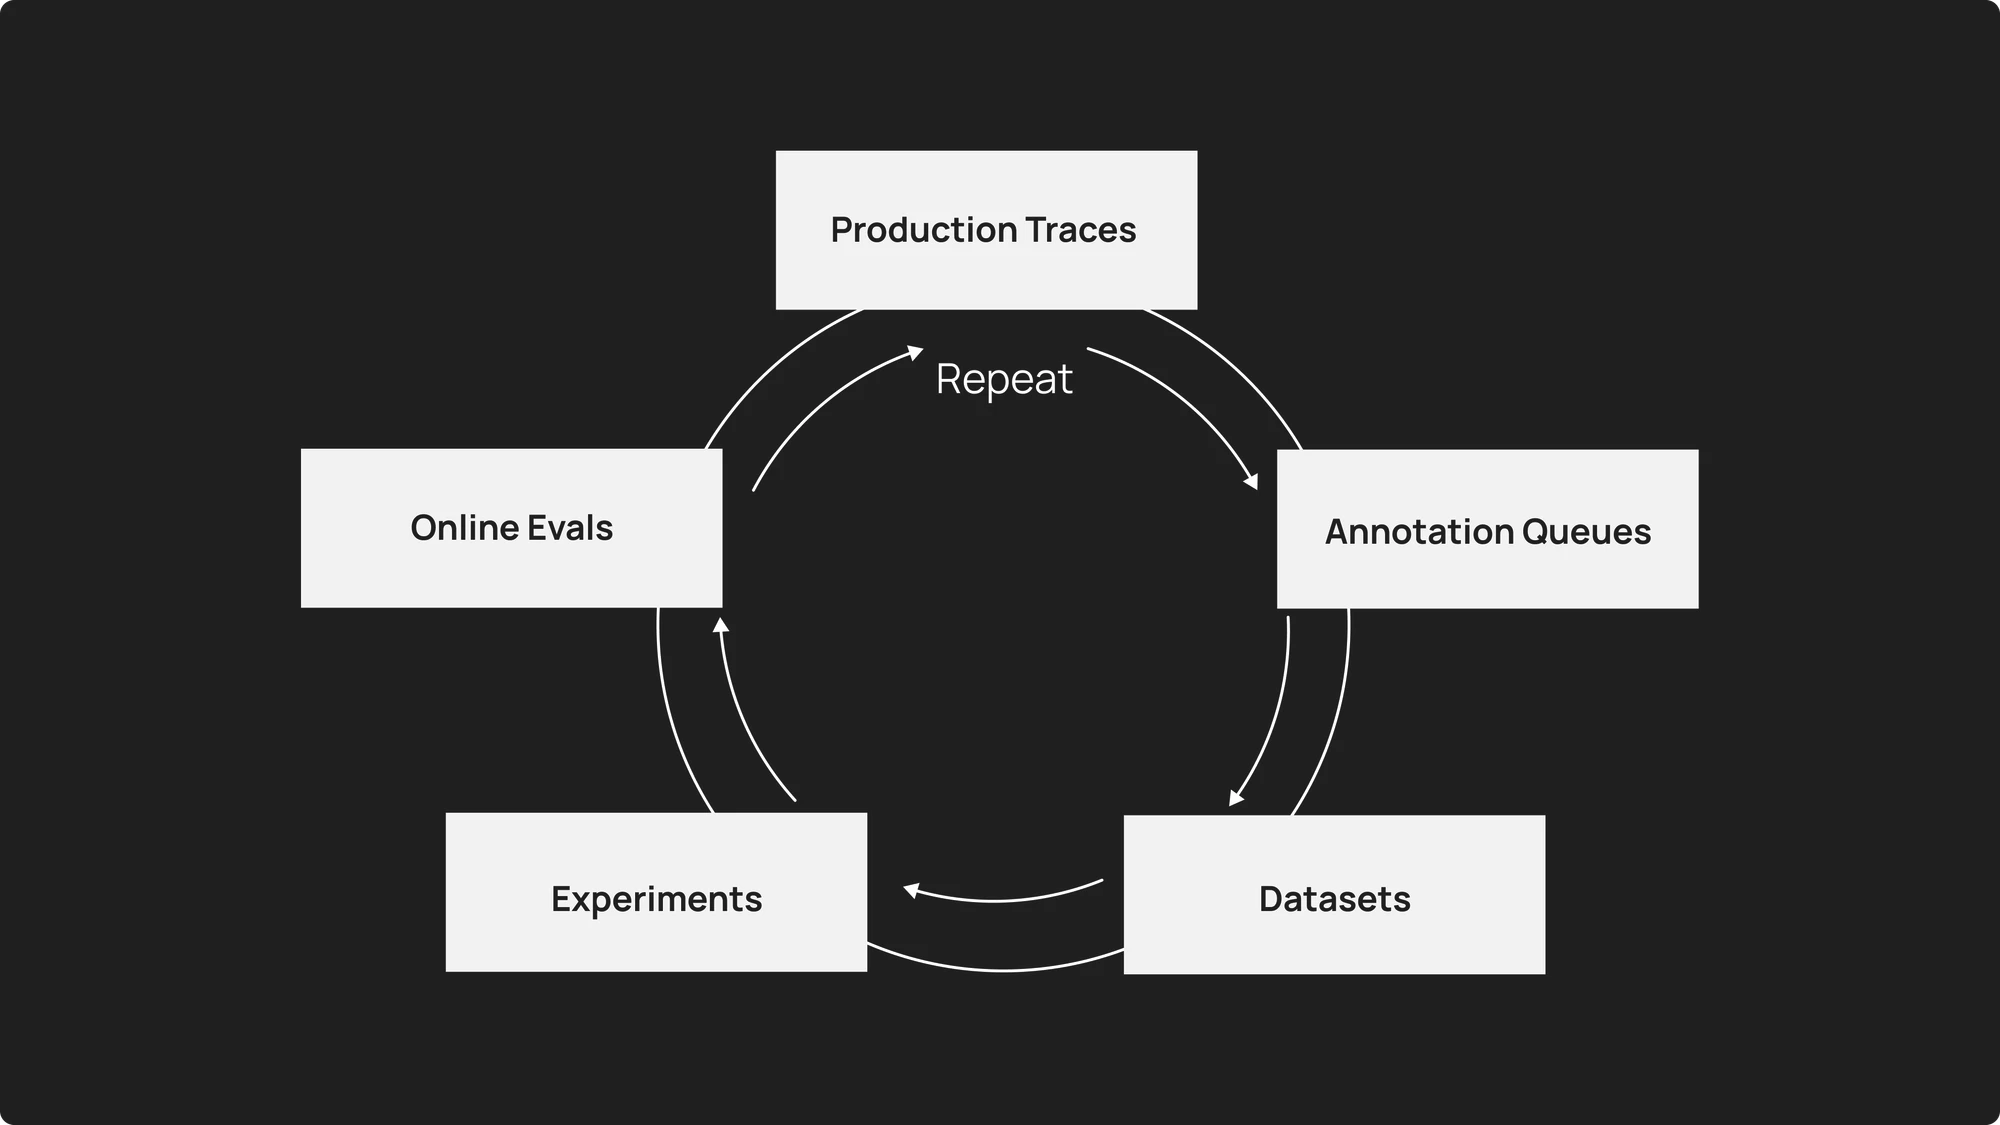
The guide argues agents can't be monitored like traditional software — natural-language input is unbounded, behavior is non-deterministic, and quality lives in conversations. It covers what to monitor, scaling evaluation, and using production traces for continuous improvement.
2 sources
More stories today
Reddit post flags issue with Opus 5.5
A single r/Singularity post titled "Houston we have a problem: Opus 5.5" reports a problem with Opus 5.5, but the post carries no body text or linked article, so no details on the nature or scope of the issue are available.
r/Singularity·2 hours ago
r/LocalLLaMA user proposes pinned per-model setup guides
A r/LocalLLaMA post calls for a pinned section featuring a detailed guide for each model, covering the best engine to run it and the minimum setup needed to match claimed benchmark results. The poster also suggests updating or adding guides when Unsloth quantizations are released.
r/LocalLLaMA·2 hours agoRauch warns AI "slop grenades" erode trust in reading
Guillermo Rauch·2 hours agoMusk says Grok 4.7 is not as good as Anthropic's Opus 5.5
In a China Media Group interview, Musk called Grok 4.7 "a solid workhorse of a model" but said it is "not as good as" Opus 5.5, which released September 22. He expects SpaceXAI to catch up "sometime next year," citing Tesla and SpaceX real-world engineering data as its edge.
r/ClaudeAI·3 hours ago
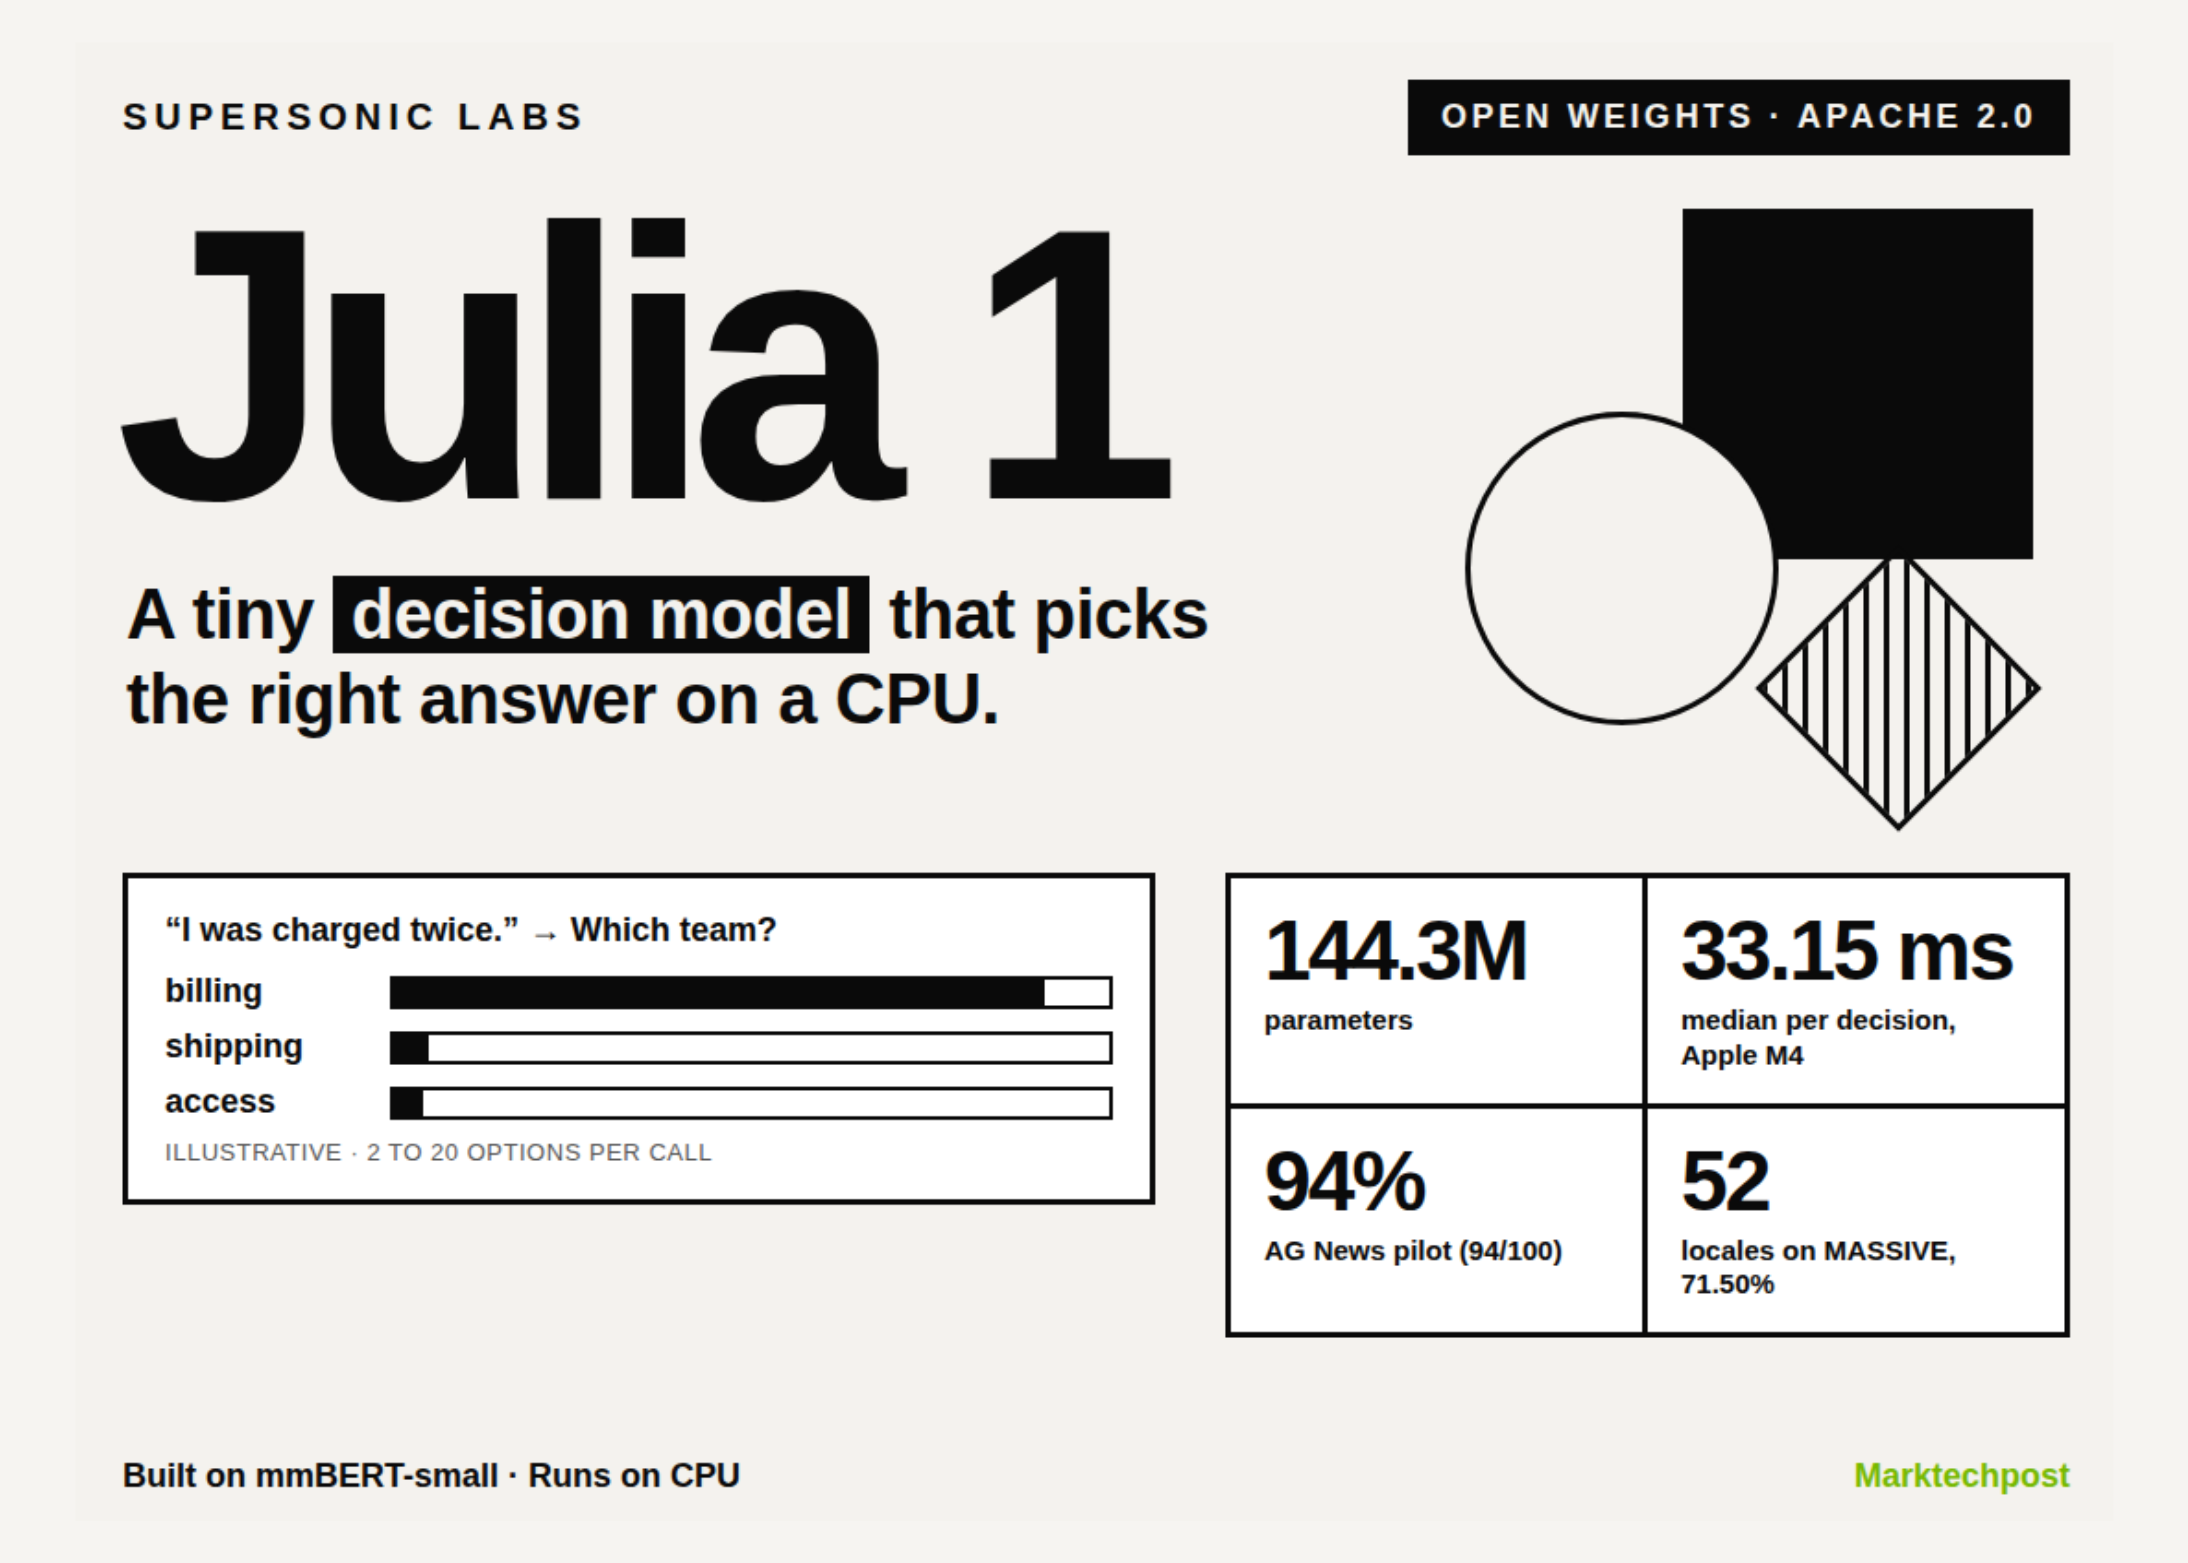
Supersonic Labs releases Julia 1, a 144.3M-parameter decision model that runs on CPU
Julia 1 is a compact decision model, not a chatbot: given context, a question, and 2 to 20 candidate answers, it picks one and returns a probability for every option. The Brazilian lab's model has 144.3M parameters and runs on a plain CPU.
MarkTechPost·3 hours ago
Reddit thread questions developer enthusiasm for each new coding model
r/ExperiencedDevs post asks what engineers are actually cheering for when models like Claude, Codex, Opus 5.5 and GPT Astra are credited with finishing features in 30 minutes or solving bugs other models could not.
r/ExperiencedDevs·3 hours agoWeco agent rewrote another agent's harness for 8 days
Weco let an AI coding agent rewrite another agent's code, prompts and tools for eight days while the underlying language model stayed fixed. MLST's Tim Scarfe asks co-founder Zhengyao Jiang what the reported gains over two years of human engineering actually demonstrate.
YouTube·3 hours ago
OpenAI teases DevDay announcements 72 hours out
OpenAI Developers·3 hours ago