Xenova runs LFM3-Omni-2B fully in-browser via WebGPU
Read original source →x.com
Custom WebGPU kernels run the 2B omni model end-to-end at ~280 tok/s on an M4 Max, accepting visual, audio, or text with no separate ASR or TTS models. A r/LocalLLaMA post sarcastically titled "INCREDIBLE" points to poor responses in Liquid AI's own demo video.
2 sources
More stories today
Liquid AI's LFM3, Mistral Large 4 and Recursive's Flint lead model drops
Llama·55 minutes ago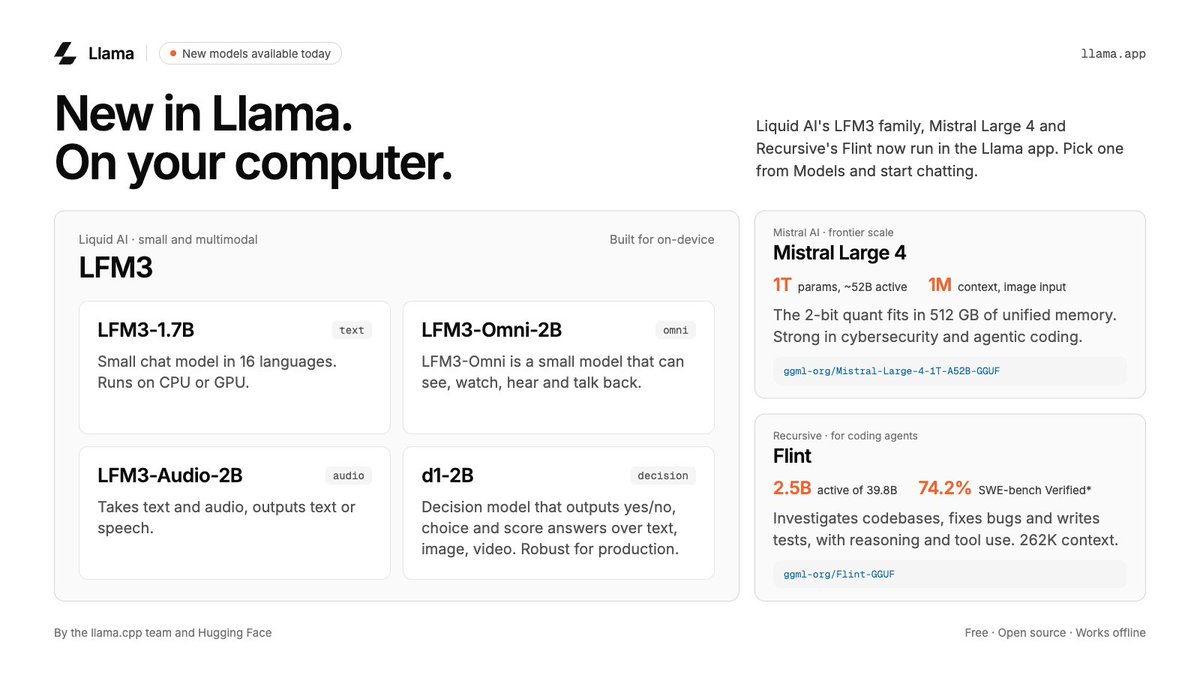
Dan Ives warns Anthropic IPO faces valuation pressure
Yorkville Ives & Co.'s Dan Ives says Anthropic's upcoming IPO faces valuation pressure, framing hyperscaler capital raising as the "start of winners and losers" in the AI trade. He also expects chip stocks to fall another 10%-12%.
Bloomberg Technology·1 hour ago
Mistral CFO and Sovereign AI Fund partner discuss Europe's AI sovereignty
Bloomberg Tech 2026 London panel with Mistral CFO Johan Bergqvist and Sovereign AI Fund managing partner Suzanne Ashman covers which parts of the AI stack Europe must control and where partnerships matter.
ComfyUI node wraps LATO.2 for low-poly mesh retopology
LATO.2, from HUST and Meshy under an MIT license, generates a new low-poly mesh from dense TRELLIS.2 or Hunyuan3D output, taking a requested vertex count of 200–5,000. The community ComfyUI node targets 500k–1M-triangle meshes that are otherwise unusable for games or animation.
r/ComfyUI·1 hour ago
Survey: 77% of parents want schools teaching students to use AI
National Parents Union survey of 1,528 parents found 77% want K-12 public schools teaching effective AI use and 85% back AI safety instruction. Only 46% think their state handles school technology well enough, and 4 in 10 teachers report no AI training at all.
EdSurge·1 hour ago
Reddit user asks how to set up Obsidian with Claude
A r/ClaudeAI post asks for guidance on pairing Obsidian with Claude, noting Obsidian's markdown files are natively readable by the model. The poster says prior Claude results were unsatisfying and wants to know what the Obsidian setup offers.
r/ClaudeAI·1 hour agoBBVA and OpenAI discuss integrating AI models into banking systems
BBVA's global head of AI transformation Antonio Bravo and OpenAI's global head of forward deployed engineering Colin Jarvis discussed the integration at Bloomberg Tech in London. No deployment figures or timelines were disclosed in the session description.
Shield AI CEO plans $1B+ raise to fund autonomous fighter jet
CEO Gary Steele said Shield AI plans to raise more than $1 billion to fund production of its latest autonomous fighter jet. The defense startup also intends further M&A.