GRPO training instability across scales and new stabilization methods
Read original source →arxiv.org
A Reddit experiment shows the same GRPO recipe on three from-scratch LLMs (353M/316M/672M) yields three different outcomes with no clean scale relationship. Two new papers propose fixes: RTPO (Reverse-Turn Policy Optimization) stabilizes multi-turn agentic RL, and GUPO (Gradient Uncertainty-aware Policy Optimization) improves GRPO post-training.
How this story unfolded
2 days · 3 reports · 1 community post · from Aug 19
- Aug 19
- Aug 20
- Aug 21
More stories today
NanoMuse launches as open-source AI agent for phone and computer
Show HN post introduces NanoMuse, an open-source AI agent that runs on both phones and computers. The project is hosted on GitHub under the nano-muse organization.
Hacker News·50 minutes agoNvidia fine-tunes Nemotron for gold-level IOI and IMO results
Nvidia reports gold-level results in both the International Olympiad in Informatics and the International Mathematical Olympiad from a single fine-tuned Nemotron model family.
Hugging Face Blog·1 hour ago
FastH3 V2/V3 project status update posted
FastH3 V2 shipped three weeks before this status post; the update covers the open-weight FastVideo FastH3 V2/V3 project.
r/StableDiffusion·1 hour ago
ChatGPT users report stricter image guardrails
Reddit users say image generation prompts that worked for over a year are now denied, with one reporting 25 wasted generations in 24 hours. No official explanation from OpenAI appears in the thread.
r/ChatGPT·1 hour agoHumanCulture launches predictive analytics for music marketing
HumanCulture claims 82-90% accuracy predicting social content performance before posting, analyzing up to a year of an artist's Instagram and TikTok posts. First clients include Defected, Red Light Management and Armada Big Family; pricing starts at £65 per talent per month.
Music Ally·1 hour ago

Confidence-threshold feature cuts AI reasoning time
Guillermo Rauch·1 hour ago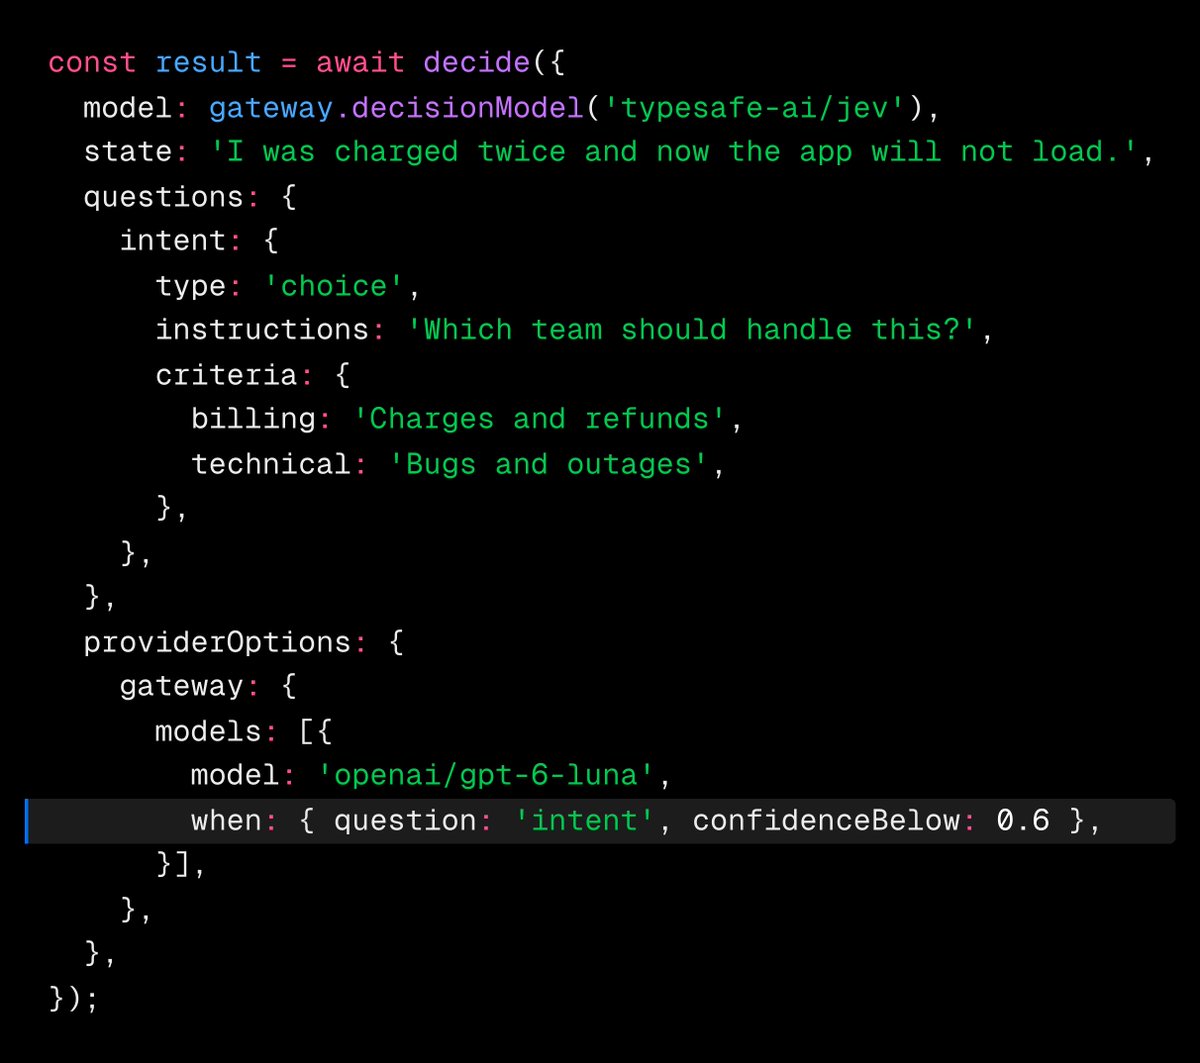
ComfyUI-Extended-Lora-Loader extension released
A Reddit user shared a ComfyUI extension for the Lora package, built primarily for personal use. The author says the code was written with Qwen 3.8 rather than by hand, with a detailed description on GitHub.
r/ComfyUI·1 hour ago
Sam Altman discusses Elon Musk and AI's future in Vanity Fair interview
Vanity Fair's "Fair Game" published part one of an interview with Sam Altman covering Elon Musk, the term "artificial," and the future of humanity. No new product, model, or company announcement is included in the segment.
Fair Game by Vanity Fair·1 hour ago