OpenAI releases GPT-6 Sol and Luna, cutting API prices 50%
Read original source →openai.com
Sol costs $2/$10 per 1M input/output tokens and Luna $0.10/$0.50, both 50% below GPT-5.6 promo pricing. The models sit below GPT-6 Astra and roll out in ChatGPT Work and Codex for Plus, Pro, Business, Enterprise, and Edu users.
How this story unfolded
1 day · 7 reports · 19 community posts · from Sep 22
- Sep 22
OpenAI releases GPT-6 Sol and Luna — and cuts token prices in halfthenewstack.io
GPT-6 SOL AND LUNA ARE OUT!!!youtube.com
OpenAI launches GPT-6 Sol and Luna, boasting lower cost and fewer mistakestechcrunch.com
Introducing GPT-6 Sol and Lunaopenai.com
OpenAI releases GPT-6 Sol and Luna models, slashing API costs 50% or moreventurebeat.com
- Sep 23
More stories today
Muse turns camera photos into product shots
Alexandr Wang·53 minutes ago
Hebbia tests GPT-6 Astra on financial research, cites double-digit gains
In Hebbia's prerelease tests, GPT-6 Astra led the best alternative by 13.6 percentage points on required source types cited and 14.4 points on presentation requirements. Cited excerpts were relevant 99.5% of the time, and 97.9% of applicable presentation requirements were met.
OpenAI Blog·56 minutes ago
Ultrafast mode on ChatGPT Pro 200 speeds up GPT-6.2 Astra and Sol builds
OpenAI Developers·1 hour agoStandard Bank Group automates generative AI risk assessment on AWS
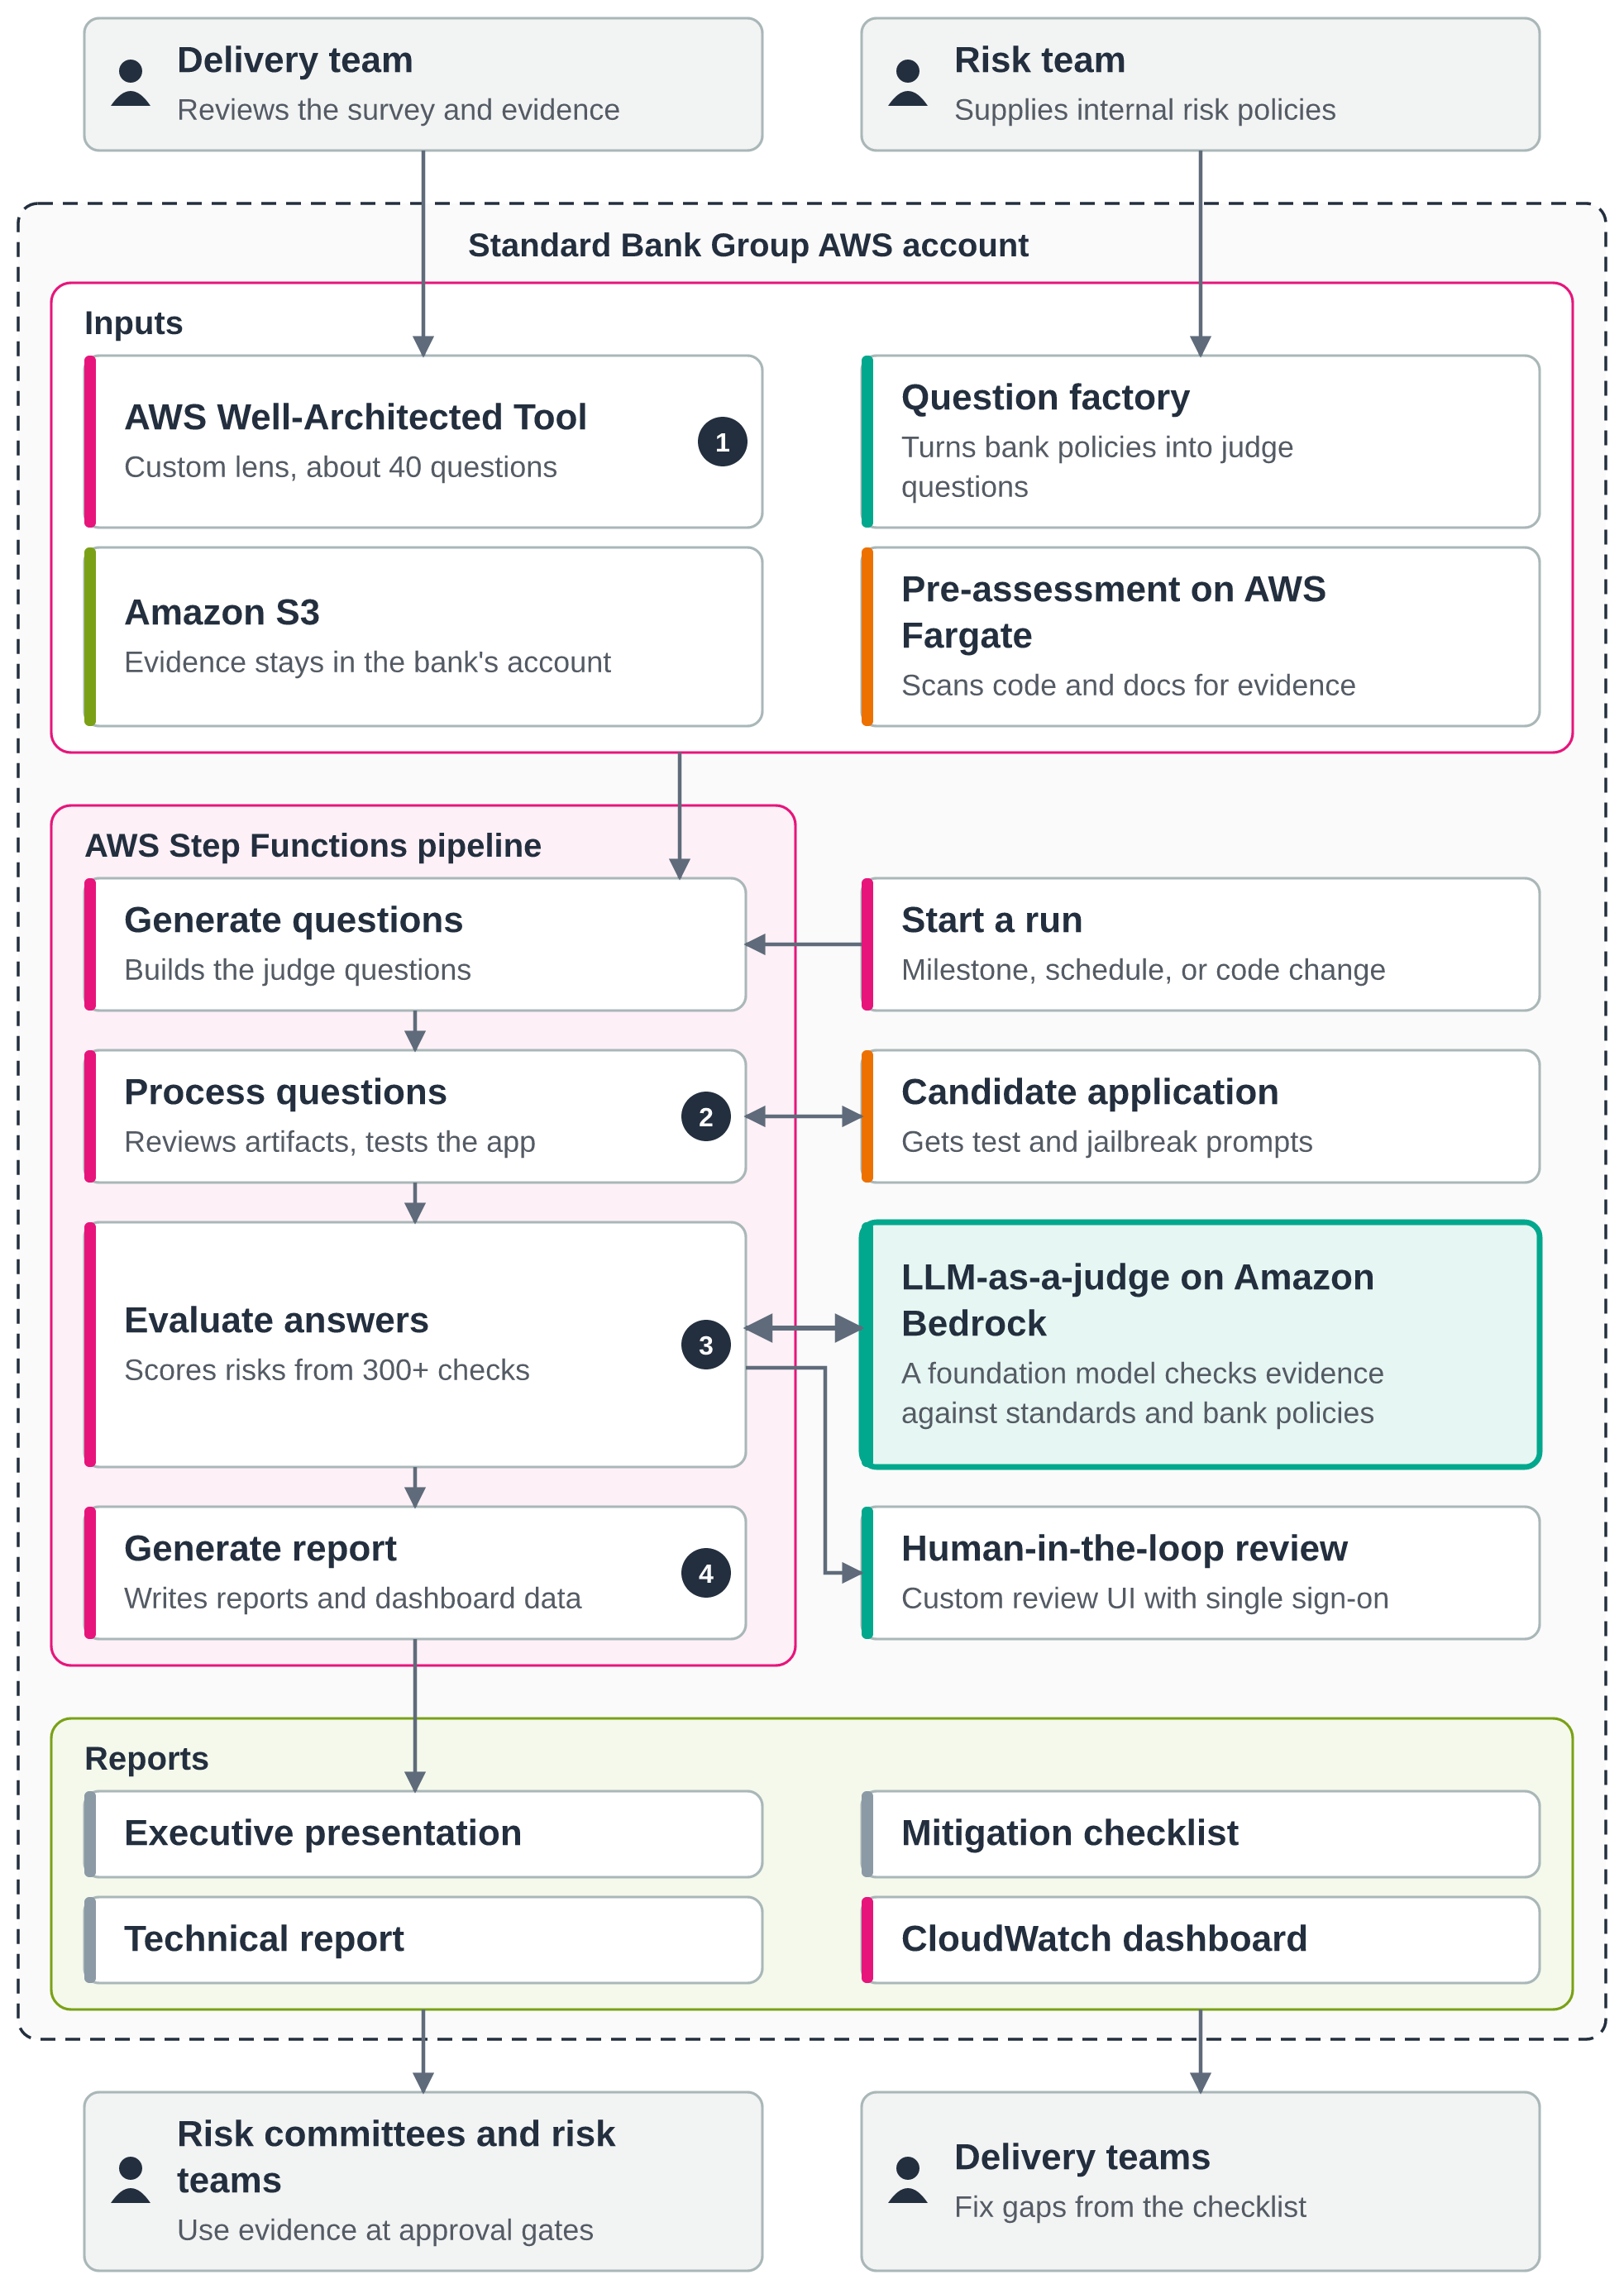
Standard Bank Group built an automated system on AWS that checks each generative AI use case against its AI policy, a process it says can now be stood up in days. The post is co-written by Tala Qraitem of AWS and Jörg Fischer of Standard Bank Group.
AWS AI Blog·1 hour ago
Amazon Textract Insights adds verifiable generative AI for documents
AWS launched Textract Insights, extending its document-processing service beyond text extraction to generative AI output aimed at financial services, insurance, healthcare and public-sector workflows. AWS says the results are verifiable.
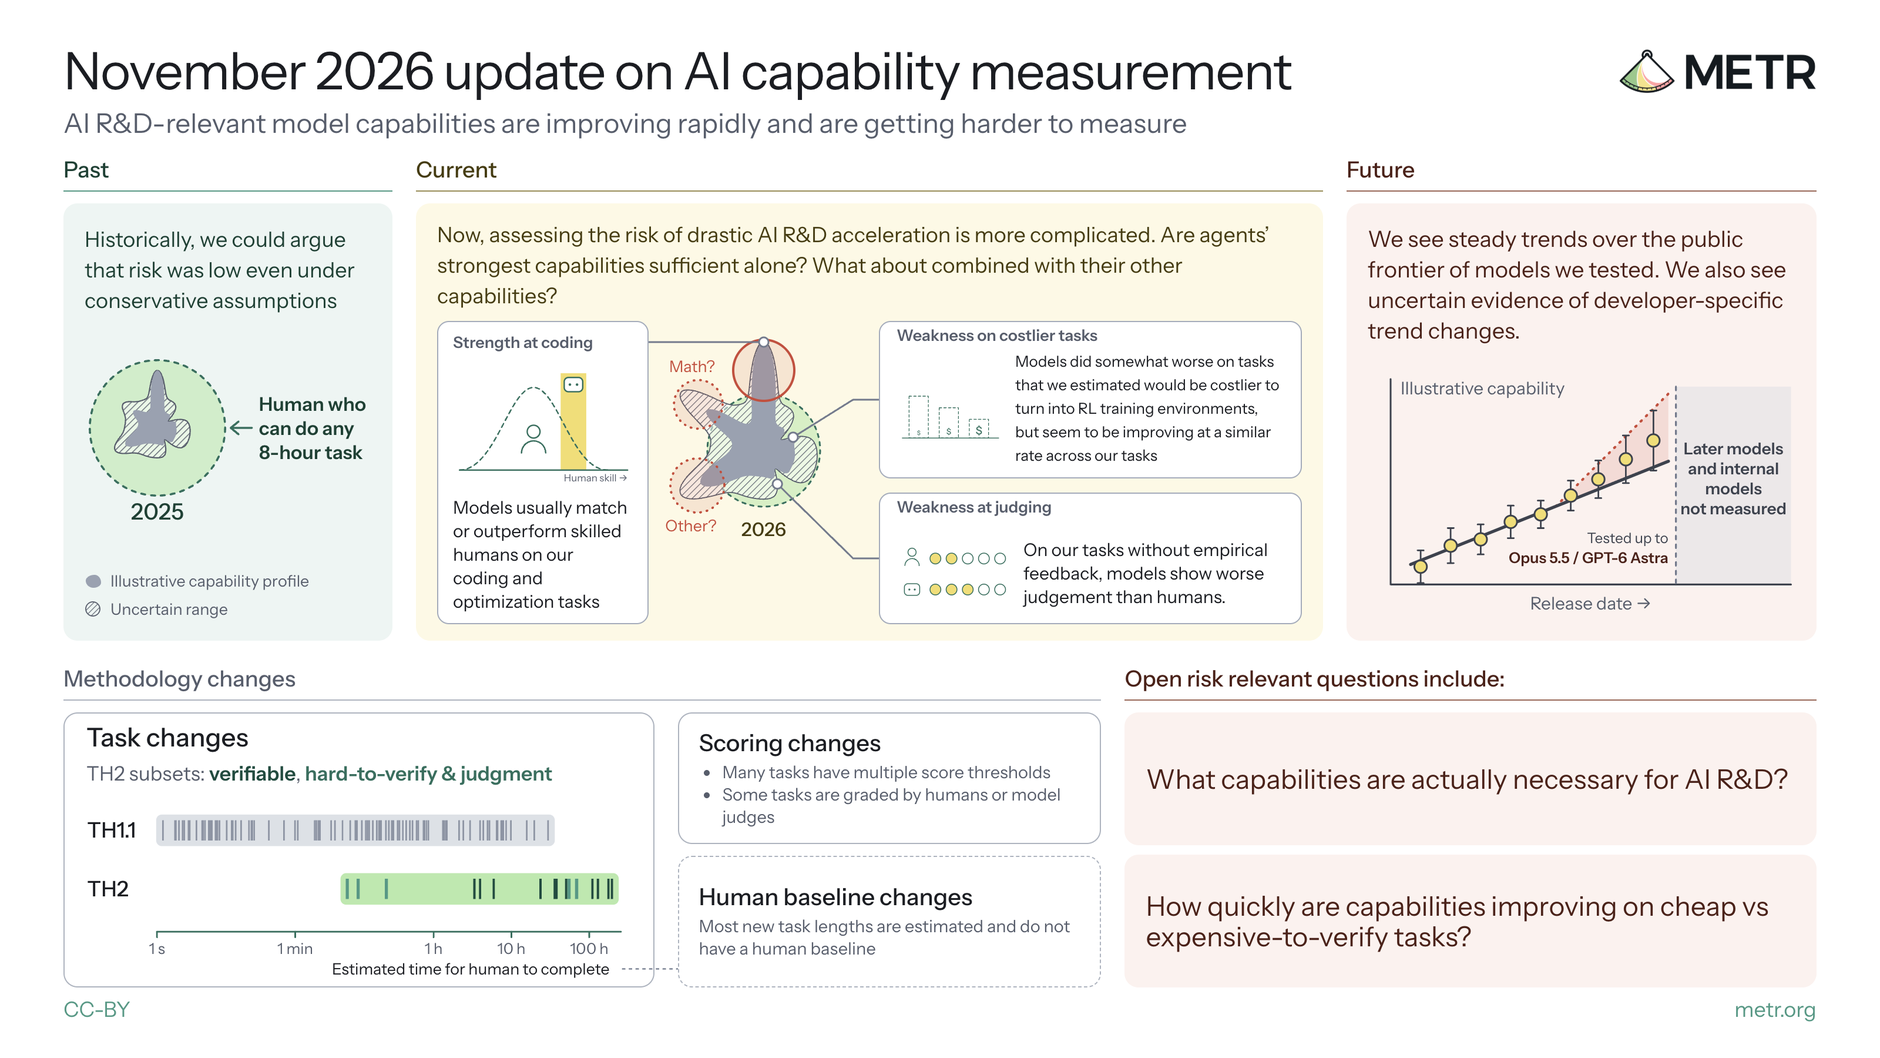
METR's updated time-horizon report finds AI still improving exponentially
METR's update to its time horizon plot, covering models up to Opus 5.5 and GPT-6 Astra, adds longer and more open-ended tasks; the original showed task length doubling every four months. Models match or beat skilled humans on coding and optimization tasks but lag on judgment-heavy work.
METR·1 hour ago
Apple releases Depth Pro 2 for sharp, temporally consistent monocular depth
A single scalable network predicts dense metric depth for images and video at native resolution, jointly improving metric accuracy, boundary sharpness, and temporal consistency. Apple says prior methods trade consistency for sharpness; Depth Pro 2 claims a new Pareto frontier across accuracy, sharpness, consistency, and runtime, with code and weights released.
Apple ML Research·1 hour ago

Ramp's Inspect agent writes ~75% of company code
Zach Bruggeman says Inspect now writes and ships around 75% of Ramp's code, per his CODE Summit 2026 talk. He credits shared agent tooling, open internal sessions and visible verification, citing a telemetry bug and the Review Buddy code review agent.
YouTube·1 hour ago