Qwen3.8-Flash-Next 177B runs at 11-15 tok/s on single RTX 5070 12GB
Read original source →github.com
A llama.cpp expert-streaming setup on Windows hits ~11.5 tok/s with the UD-IQ3_XXS quant of Qwen3.8-Flash-Next 177B, up from roughly 7 tok/s on the inherited setup. Hardware is an RTX 5070 with 12GB VRAM plus 32GB DDR4 RAM.
1 source
More stories today
Offrun manages Claude Code, Codex, AGY and Grok Build in one workspace
Offrun runs coding-agent CLIs locally on Apple Silicon Macs, giving each agent its own git worktree so parallel agents never touch the same files. It uses your existing agent logins, moving a chat to another account when one hits its limit.
Hacker News·2 hours ago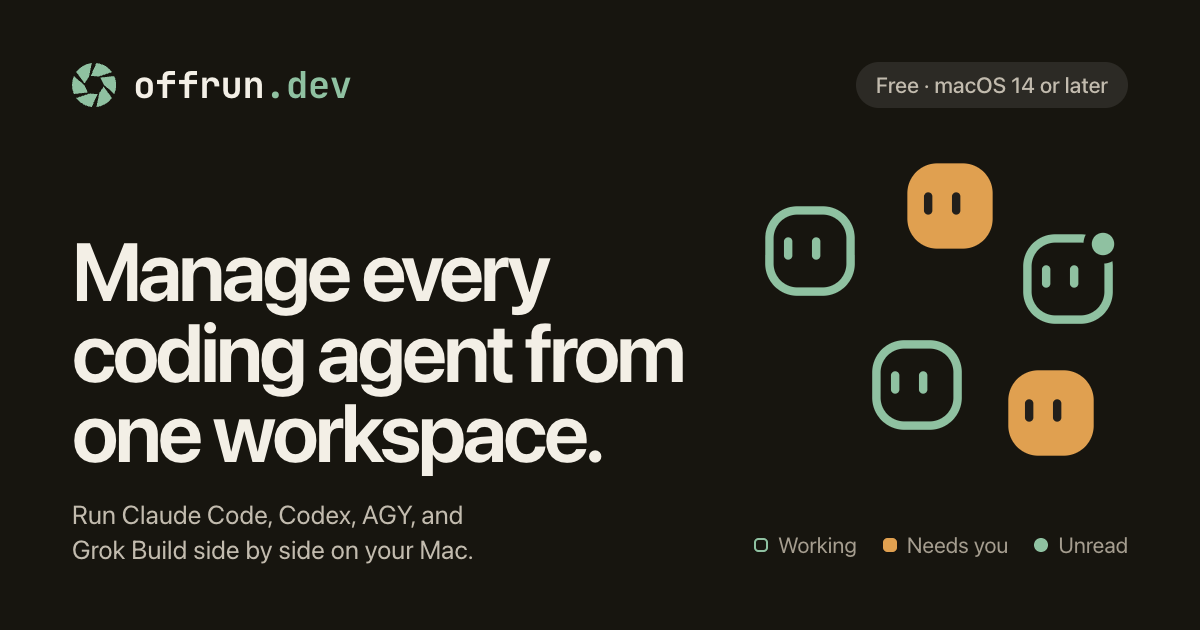
Reddit user builds fantasy airship FTL-like game with Claude
A developer spent the past week building a strategy combat game described as "fantasy airship FTL," with crew dungeon runs, cargo quests, and mage crew members. It is playable for free.
r/ClaudeAI·2 hours ago
Reddit user builds Qwen3.8 27B RAG node on fake AliExpress mini PC
A LocalLLaMA user built a dedicated RAG/search node for Qwen3.8 27B using a cheap AliExpress mini PC that arrived with fraudulent hardware instead of the promised Intel N150 with DDR4/DDR5 support.
r/LocalLLaMA·2 hours ago
Patent attorney: physical AI race will be won in the patent office
A patent attorney with 20 years of experience and 300+ filed industrial-automation patents argues robotics startups lose when they delay IP filings, citing Boston Dynamics' 2022 suit against Ghost Robotics over fall-recovery "core technology." Swarm robotics raises an unresolved question: whether the behavior of a swarm can be patented, or only the machines producing it.
The Robot Report·2 hours ago
Sam Altman: ascribing religious force to AI models is a real safety issue
Sam Altman·2 hours agoTechCrunch rounds up AI agents that live in your text messages
The list covers Caddy, which turns scattered phone info into calendar events and reminders and has been in public beta since April 2026, plus Fambot, an SMS-based family "chief of staff" for school comms, sports, meals and calendars. Instinct is cited as the buzziest of the space after a $1B round at a $10B valuation.
TechCrunch·3 hours ago
Muse model demonstrates improved speed and temporal reasoning
Alexandr Wang·3 hours ago
Vaibhav Sisinty: India's AI edge lies in model engineering, not foundation models
Vaibhav Sisinty·3 hours ago