Training AI to Paint with Code
Read original source →surya.website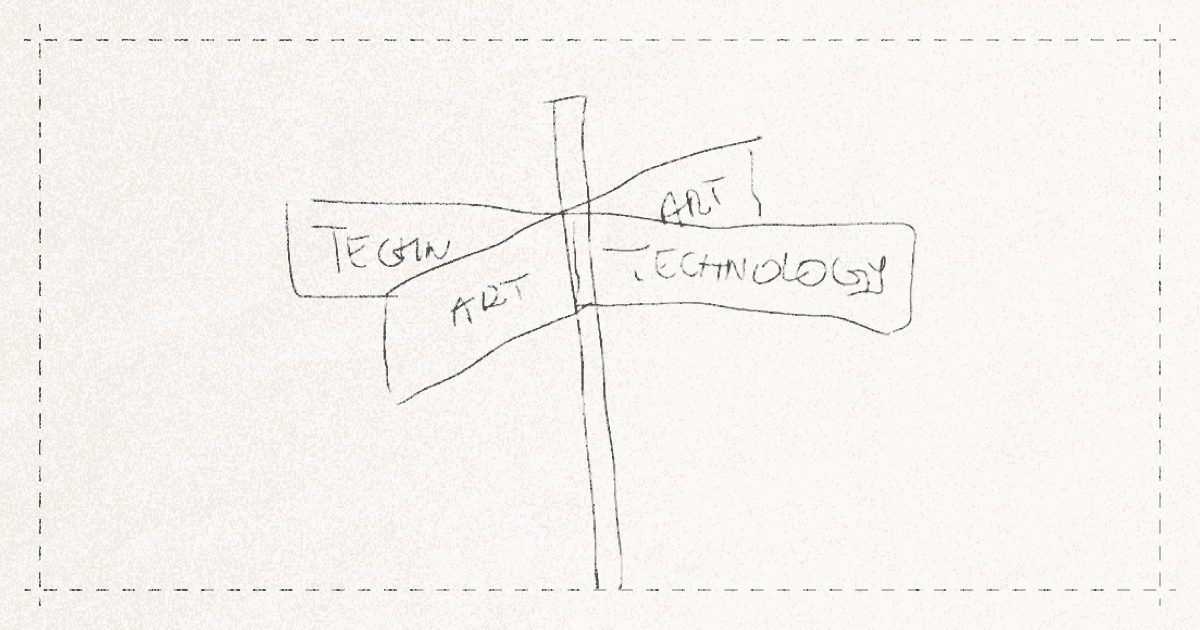
Surya and Cameron Franz trained a language model to generate editable p5.brush JavaScript sketches, using RL with a judge model comparing outputs against 581 hand-rated reference paintings. The project explores RL on creative tasks where aesthetic quality is the reward.
People · Surya, Cameron Franz
1 source
More stories today
Google DeepMind's Pushmeet Kohli on AI tools for mathematicians
Pushmeet Kohli·1 hour agoHarvey LAB-AA v1.1 adds hallucination check to legal agent benchmark
Artificial Analysis·1 hour ago
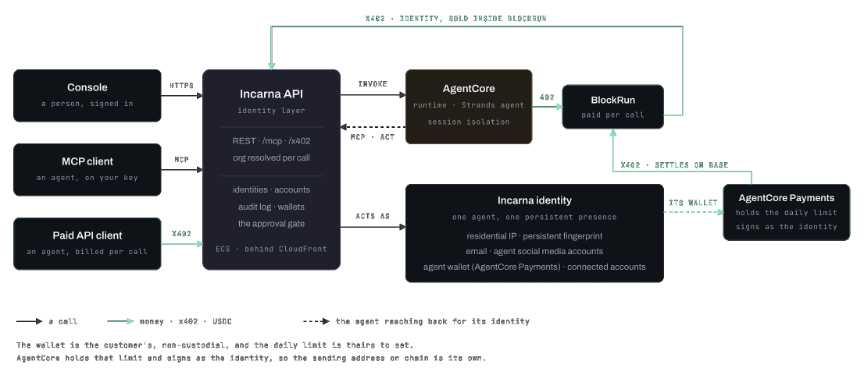
BlockRun and Incarna use Bedrock AgentCore payments for agent inference
AWS details pay-per-inference for AI agents, where purchases are small and frequent — sometimes a fraction of a cent each — and happen inside the agent's loop with no person available.
AWS AI Blog·1 hour ago
NVIDIA KGMON team takes second in KDD Cup 2026 Data Agents
NVIDIA's KGMON team placed second in the KDD Cup 2026 Data Agents competition, building its system around a smaller, more verifiable agent harness rather than a larger model. Teams had to work with a small, fixed LLM, making the harness the main optimization surface.
NVIDIA Developer Blog·1 hour ago

Vibe Data Modeling open-source agent builds and validates data models
Databricks·1 hour ago
OpenAI's annualized revenue nears $50B, $20B below prior $70B figure
OpenAI told investors its annualized revenue is approaching $50 billion, per the FT, roughly $20 billion less than the previously reported $70 billion. The higher figure came from investors' attempts to compare directly with Anthropic's annualized revenue, which counts cloud-partner sales that OpenAI does not.
TechCrunch·1 hour ago

Baikal LoopSR x2 anime upscaler adapts Looped-DiT concept
A community developer built Baikal LoopSR x2, a tiny anime/illustration upscaler that applies the recurrent shared-block concept from Looped-DiT to direct RGB restoration. Released for ComfyUI with weights available.
r/StableDiffusion·1 hour ago
Halogen 0.17.2 hits ~45 tps with Qwen 3.8 Flash Next on Strix Halo
Halogen's 0.17.2 update sustains ~45 tokens/sec decode at high context running Qwen 3.8 Flash Next on a 128GB Strix Halo machine. The model is roughly 177B parameters.
r/LocalLLaMA·1 hour ago