Ai2 benchmark finds LLM novelty judges give inconsistent verdicts
Read original source →huggingface.co
Ai2's "Old Ideas, Novel Problems" tested six judges — GPT-5.1, GPT-5.2, GPT-5.4, Claude Sonnet 4.5, Opus 4.5 and Opus 4.6 — and found small changes to the evaluation setup produce dramatically different novelty verdicts on the same ideas. Changing just a few words in a prompt shifted a model's judgment.
2 sources
More stories today
OpenAI expands Oracle partnership to bring Oracle apps into ChatGPT
Oracle business applications and AI agents will be surfaced inside ChatGPT, while Oracle will also power new offerings with OpenAI technology. The companies framed it as an expansion of their existing partnership.
OpenAI Blog·1 hour ago
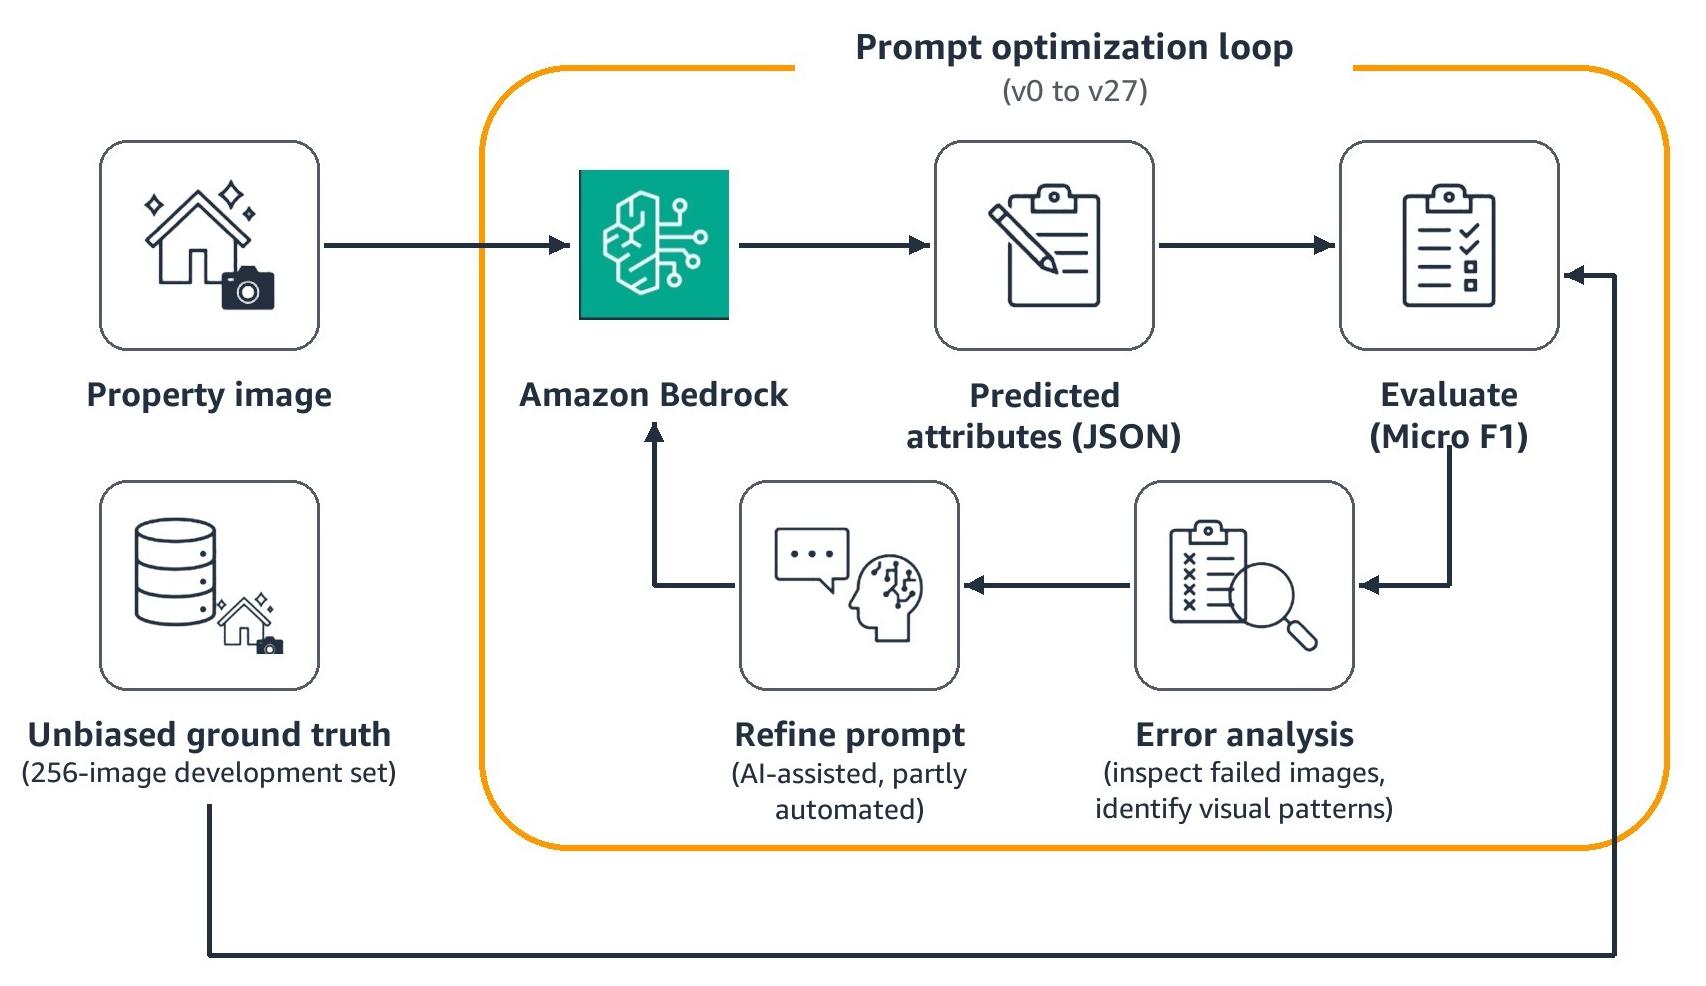
Property Finder fixed evaluation bias on Amazon Bedrock
Property Finder found 96.8% of its evaluation labels were inherited directly from a single model's outputs. The AWS post, co-authored with its engineers, covers how correcting that bias improved model evaluation on Amazon Bedrock.
AWS AI Blog·1 hour ago
LangChain open-sources Content Studio, a Slack design agent
Content Studio generates on-brand videos, graphics and decks from a single Slack prompt, with every asset written in code. LangChain spent four months teaching it design taste; each Slack thread gets its own sandbox that persists the project between turns.
LangChain Blog·1 hour ago

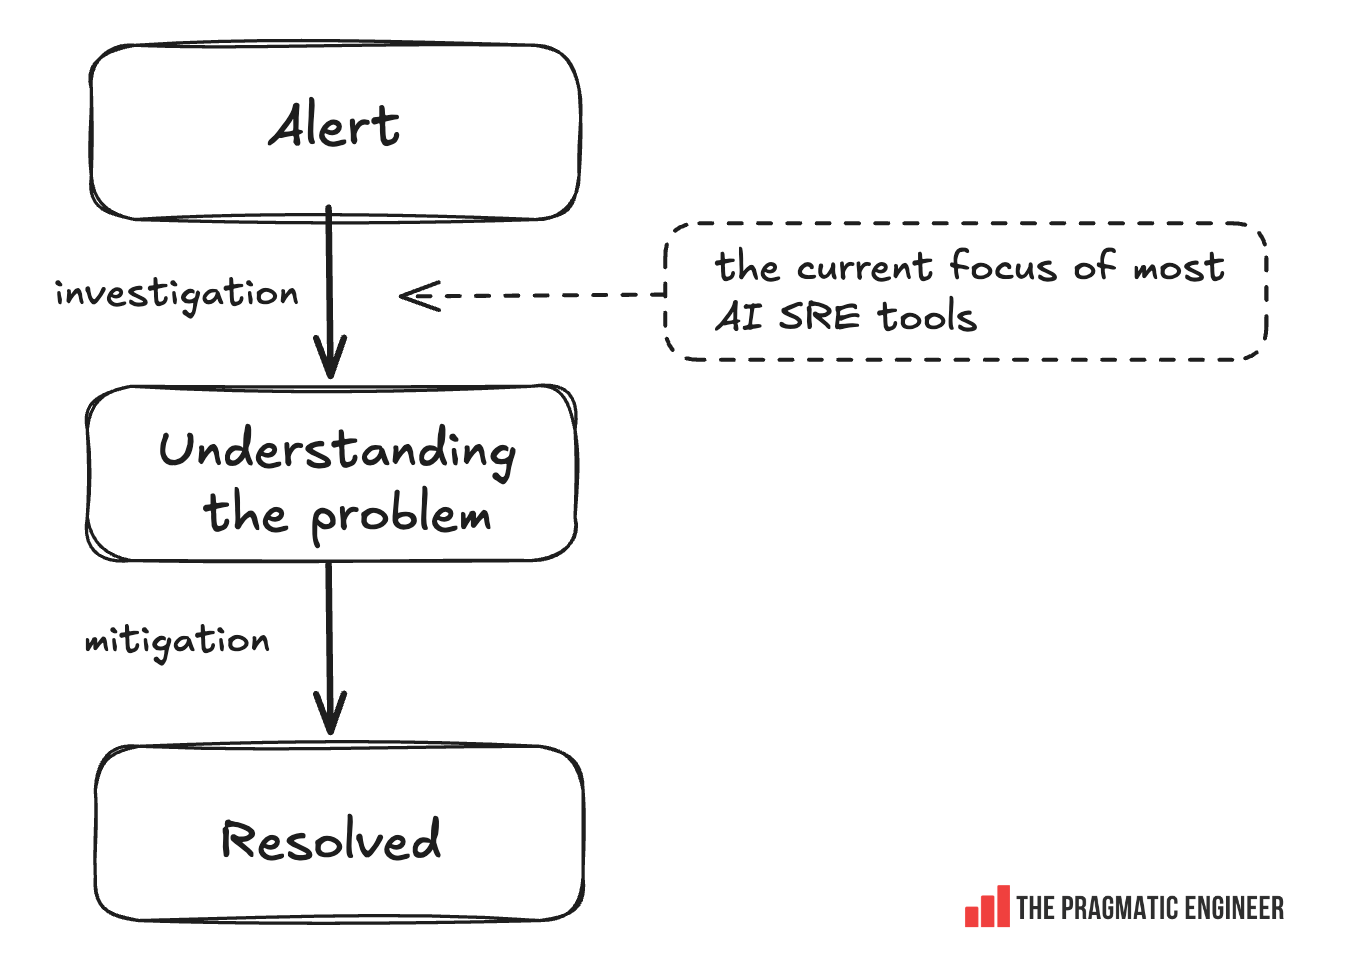
AI SRE tools aim to speed incident investigation, not replace on-call
Microsoft demoed an "Azure SRE Agent" at BUILD 2025 that root-caused and fixed an alert without waking an engineer; OpenAI has built an AI SRE bot called Sevbot, and ING is working on an in-house one. Rootly, incident.io and ResolveAI say AI SRE mostly means faster incident investigation inside Slack, and whether agents should ship code changes is debated.
The Pragmatic Engineer·1 hour ago
Reddit user compares Moss and Krea 2 image model quality
A r/StableDiffusion user testing Moss for several days says they could not approach Krea 2's detail level, citing skin pores and finer detail from a Krea 2 turbo model at 8 steps with 2 passes.
r/StableDiffusion·1 hour agoGoogle's A2UI adds swappable inference formats, cutting latency up to 3x
A2UI Express compiles compact Python-style syntax into standard A2UI JSON via Agent SDKs, using up to 3x fewer tokens than Direct JSON. Google says decision models like TypeSafe's Jev can cut layout-decision latency by up to 80x.
Google Developers Blog (AI)·1 hour ago

Qwen Code ships TypeScript SDK v0.1.24 bundling CLI 0.26.2
The TypeScript SDK release bundles CLI version 0.26.2, built from the same branch/ref as the SDK. Release notes also reference prior bundled CLI versions 0.26.1 and earlier.
Qwen Code Releases·2 hours agoLangChain's Harrison Chase to speak at Interrupt London on self-improving agents
LangChain·2 hours ago