Cohere session examines why self-repairing training converges without gradient updates
Read original source →youtube.com
Cohere's session argues standard gradient-descent convergence proofs assume every update is a gradient, an assumption self-repairing training breaks by design yet still converges. It demonstrates the case by zeroing out a converged convolutional layer at epoch 100 and pinpoints exactly where the proof stops holding.
1 source
More stories today
AMD's hrx-loom stack builds Strix Halo kernels for top-51 LLMs
AMD AI Group's experimental hrx-loom bundles a compiler, runtime, and serving tools to build, optimize, serve, and share kernels. An AMD engineer (jfowers_amd) reports using it to produce speedy Strix Halo kernels for the top-51 LLMs.
r/LocalLLaMA·2 hours ago
Mystery AI Hype Theater 3000 tackles doomer narratives and data center lobbying
Emily M. Bender·2 hours agoGS Caltex runs production MLOps on SageMaker Canvas and Pipelines
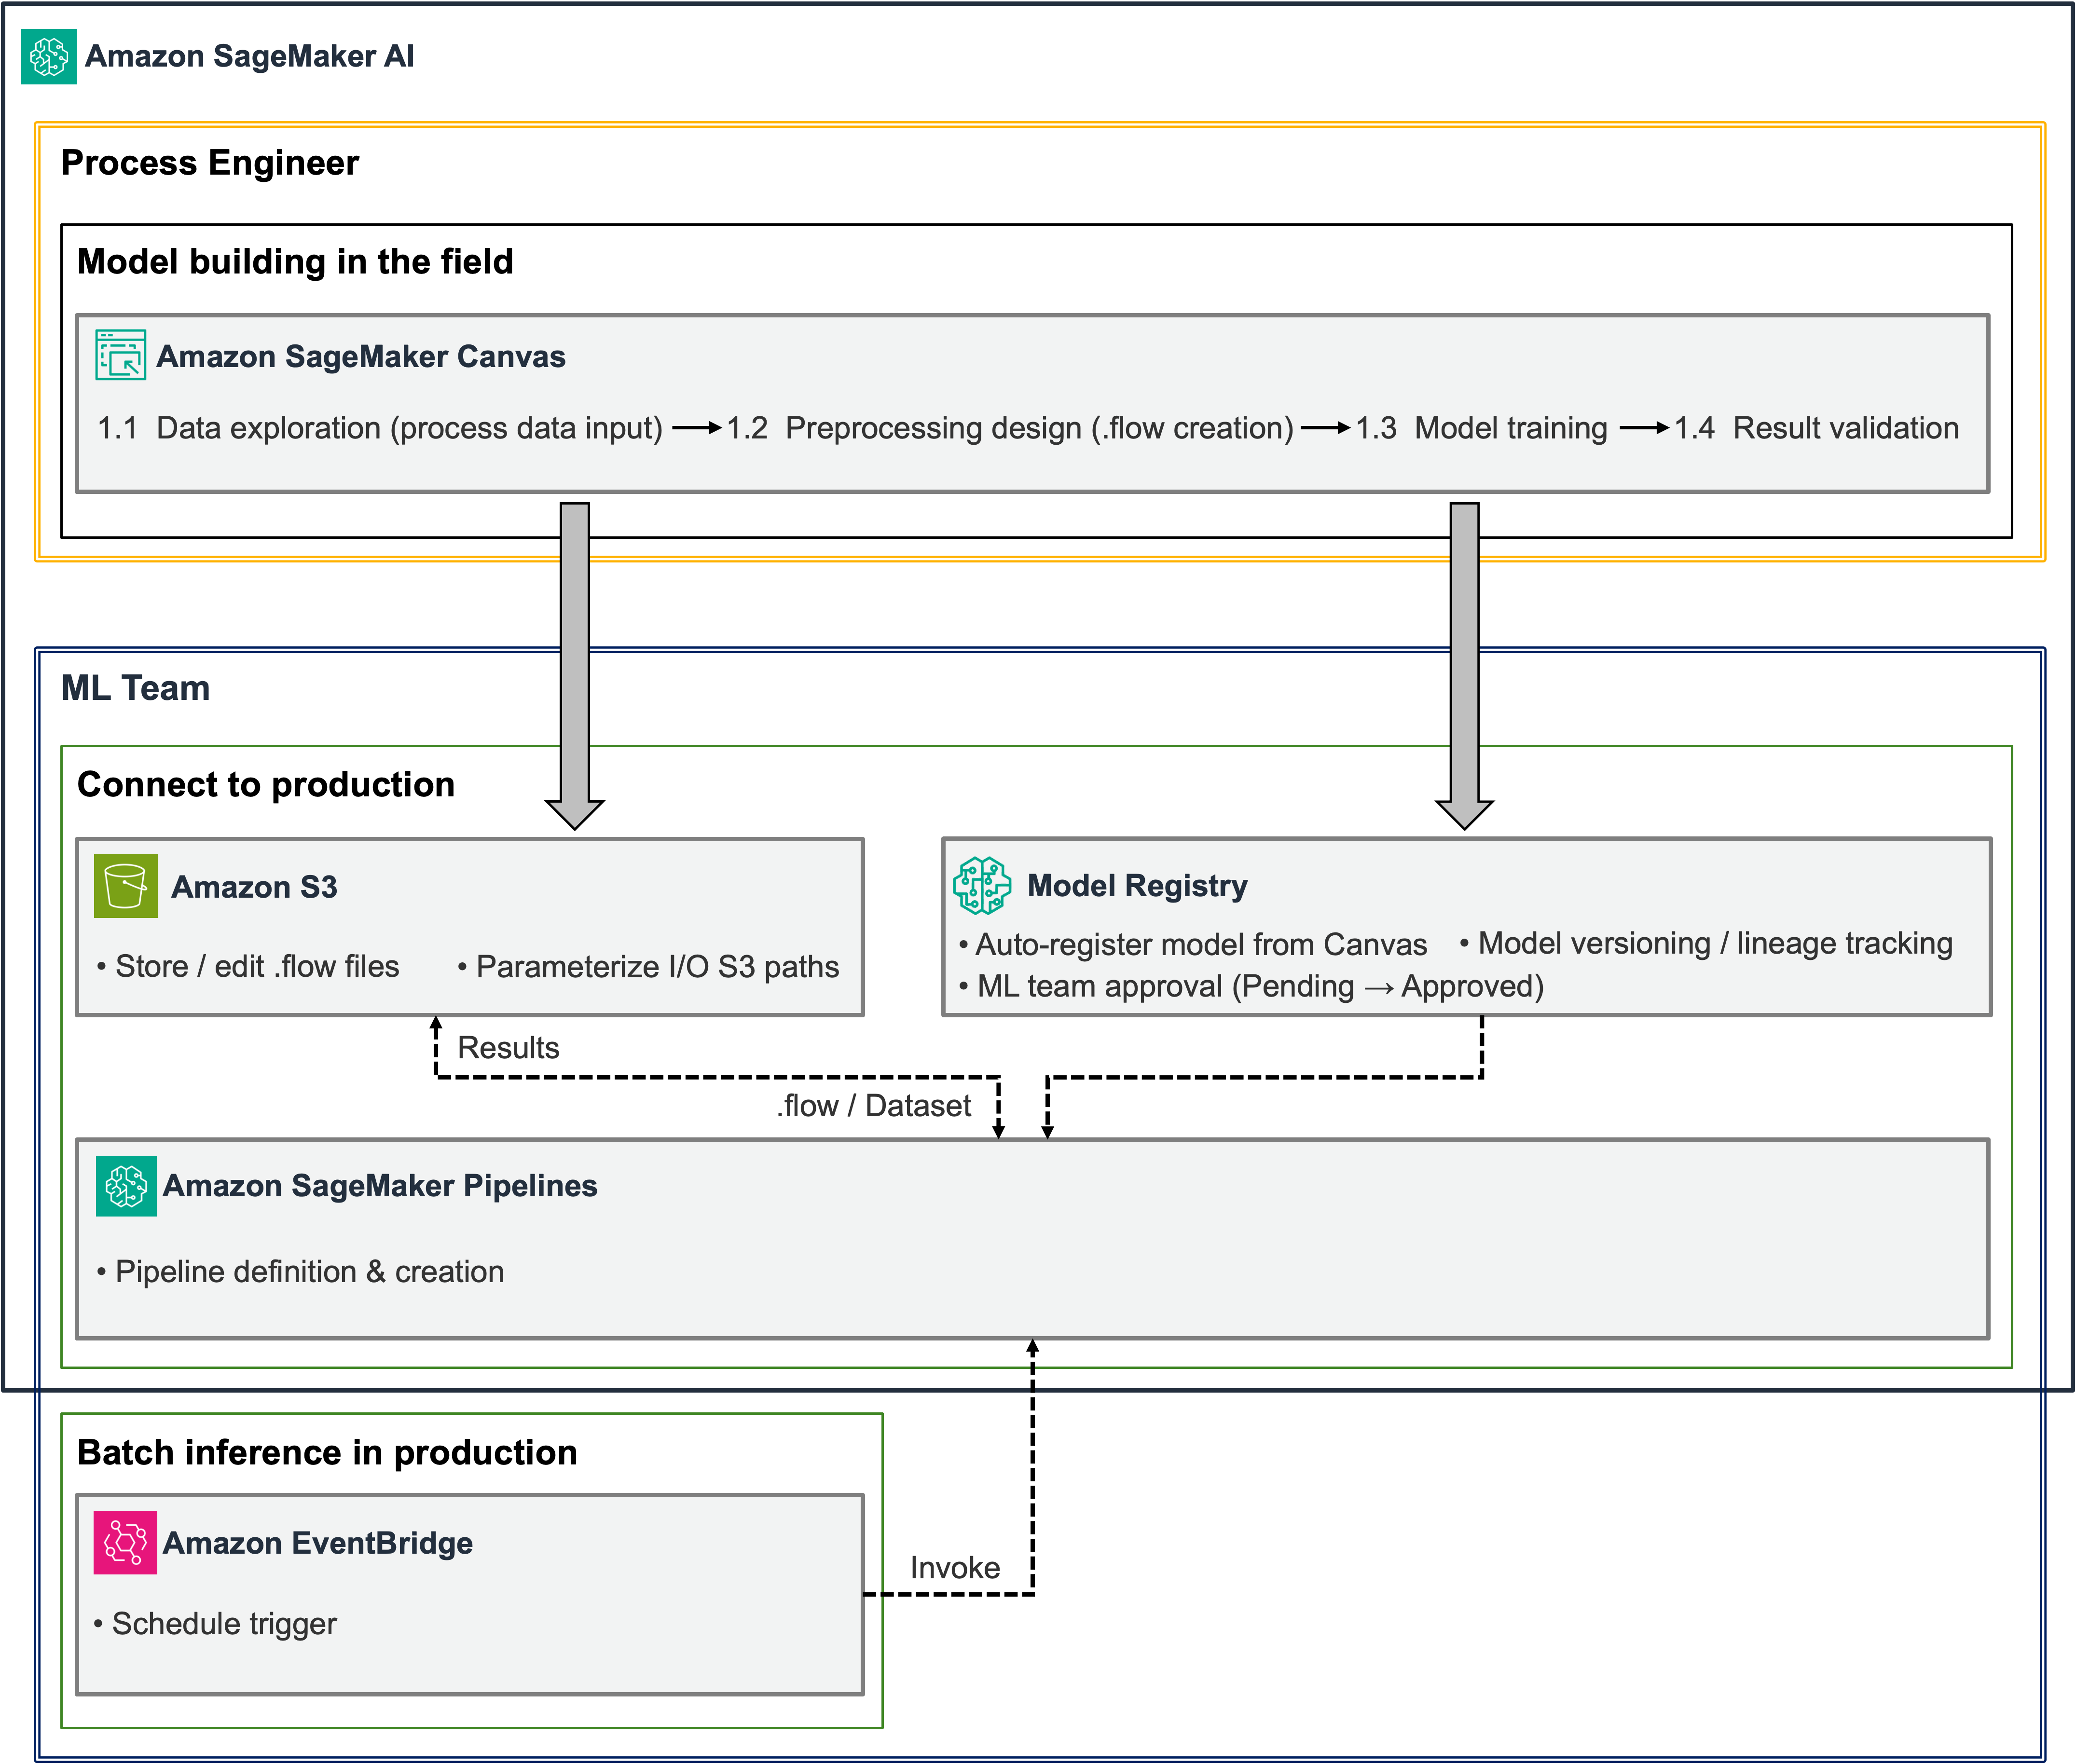
The South Korean energy and chemical company splits model development and operations between process engineers and dedicated ops staff, connecting engineer-built models to production workflows via SageMaker Pipelines.
AWS AI Blog·2 hours ago
Claude Projects adds parallel threads and a proactive coordinator
Projects in Claude Code now let Claude coordinate tasks across parallel threads, with a more proactive coordinator answering questions in project chat and reporting thread status. The redesign is in public beta on Pro and Max, rolling out in stages with a waitlist.
claude.com·2 hours ago
Claude adds read-only shareable links for individual threads
Claude Developers·2 hours ago
LayerShop adds generative AI fill and Minimax H3 Image support
Open-source Photoshop alternative LayerShop now supports generative fill for adding and removing objects using local models. The latest version also adds support for Minimax H3 Image.
r/StableDiffusion·3 hours ago
AWS shows routing coding-agent requests across models on Bedrock via NVIDIA NeMo…
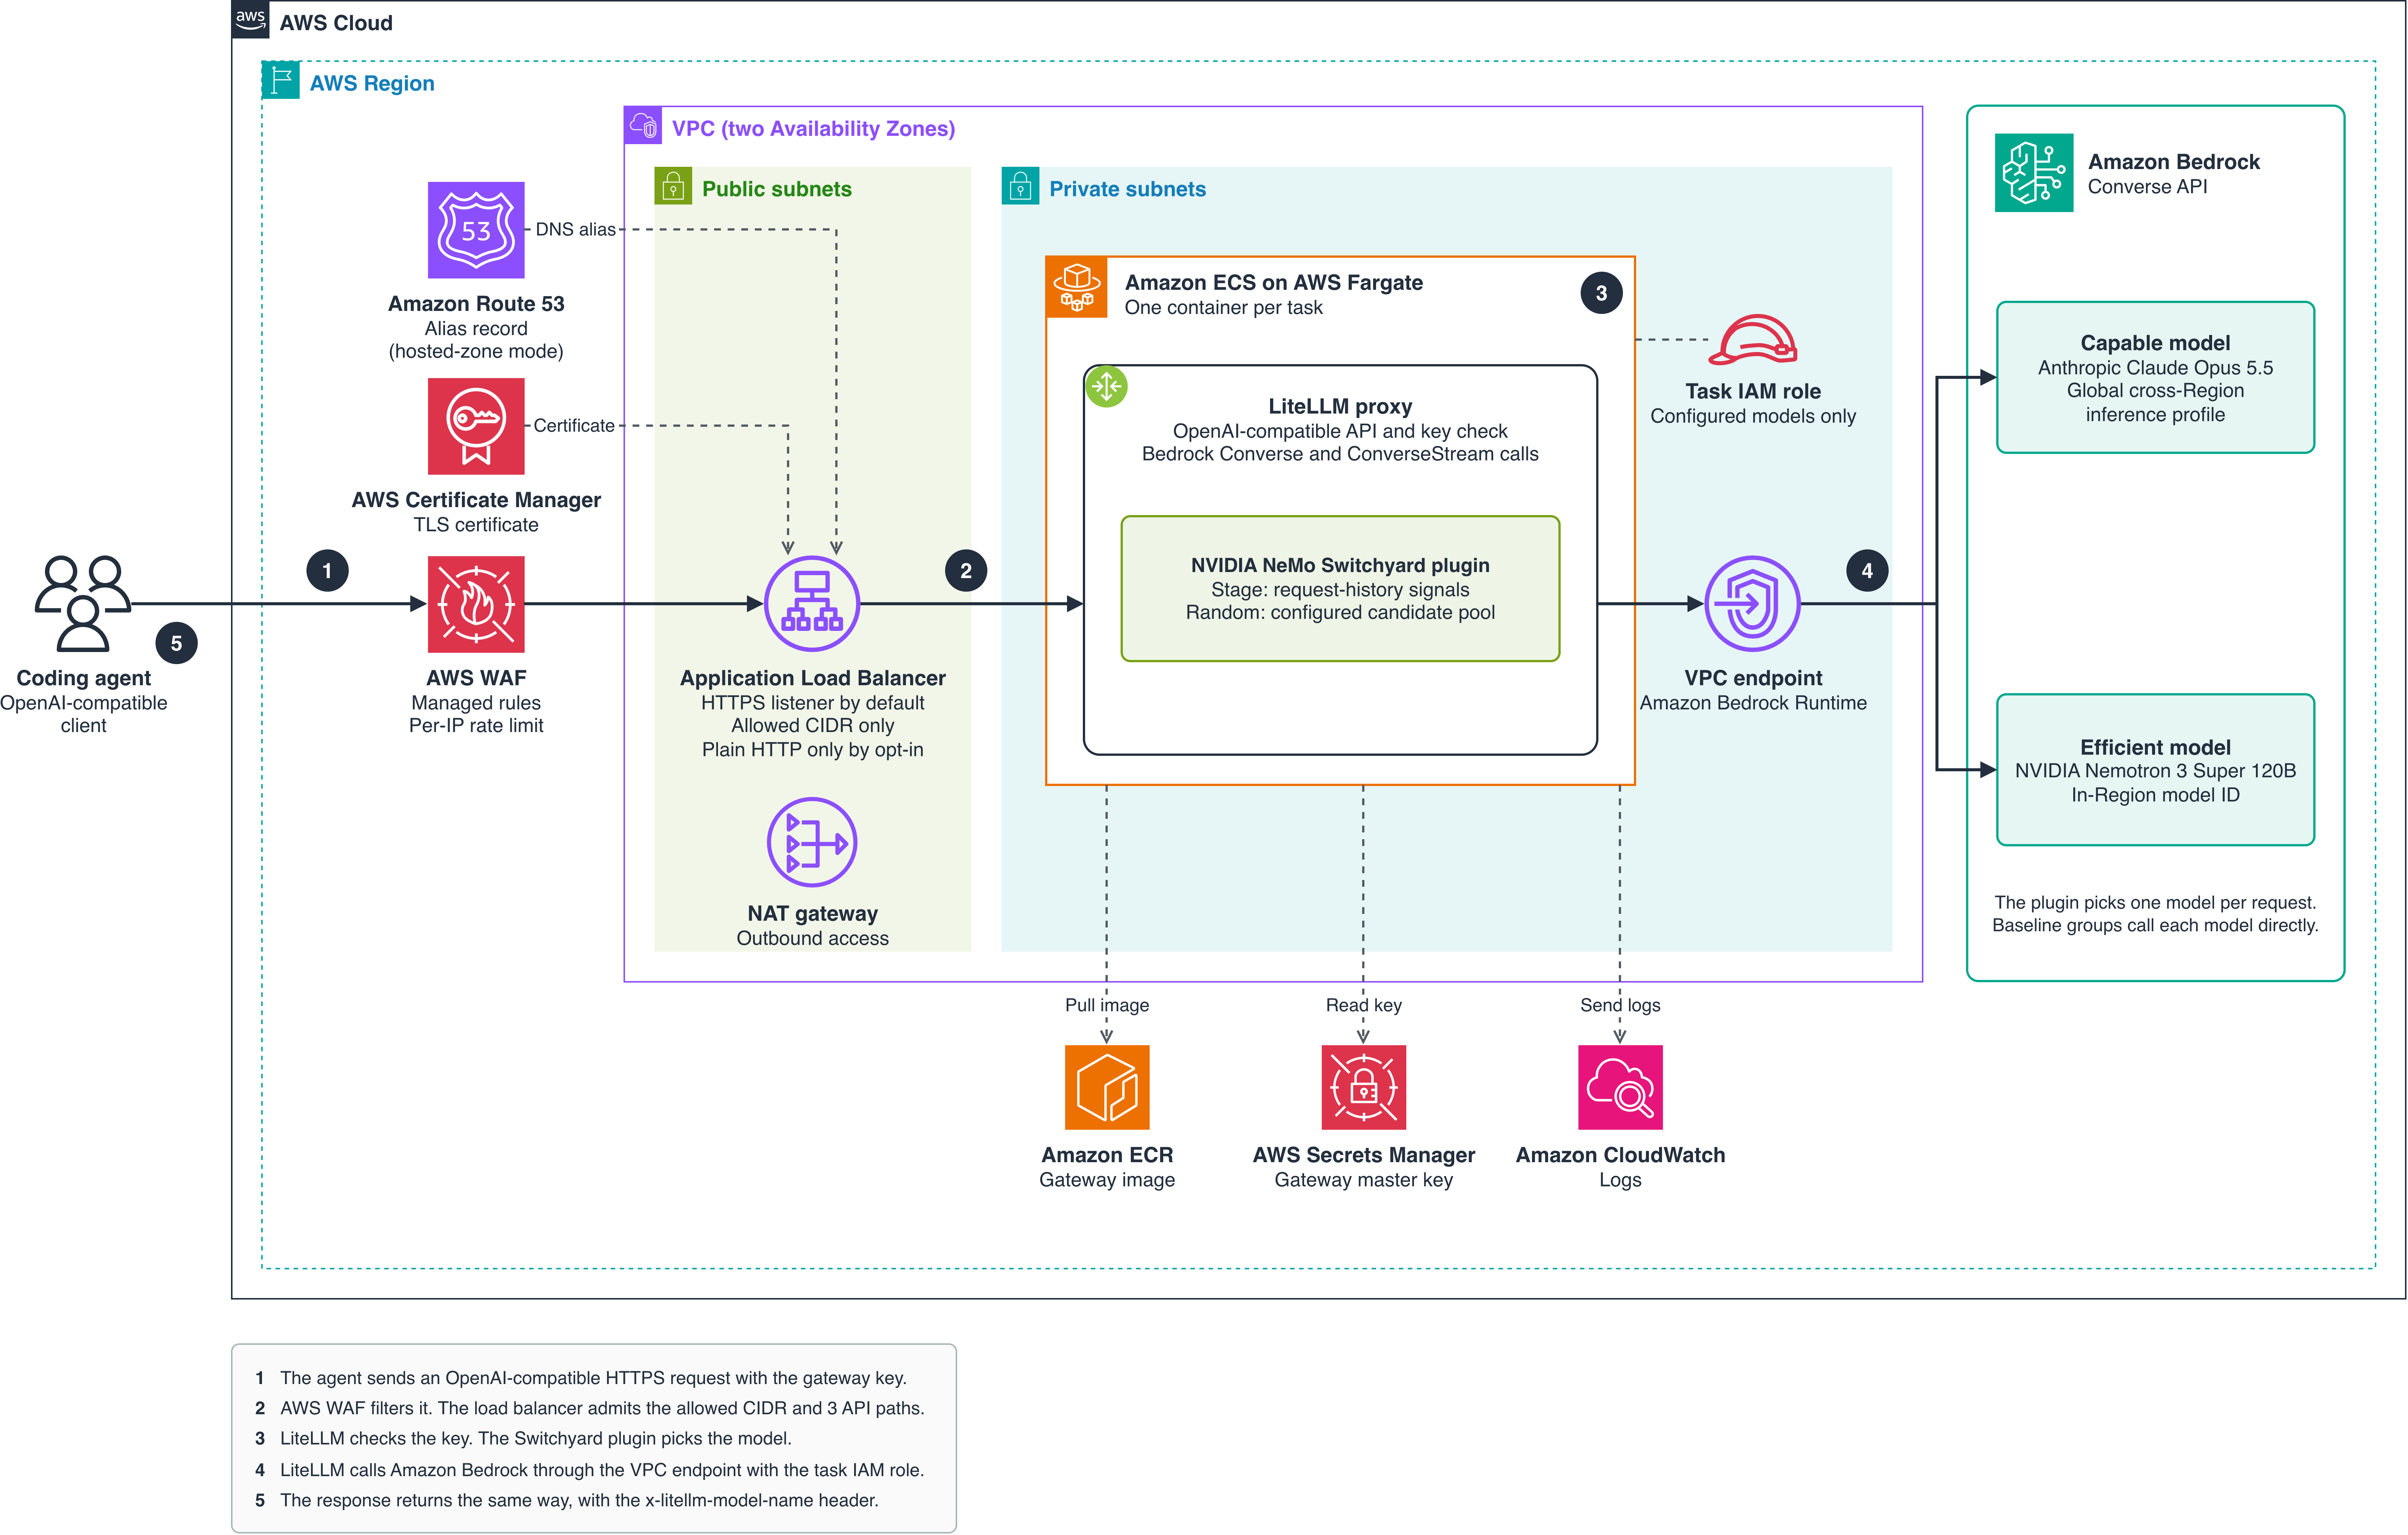
AWS post walks through using NVIDIA NeMo Switchyard on Amazon Bedrock to send each coding-agent request to the right model, noting a single task can take a few model calls or dozens. It frames cost around the task rather than one call.
Morgan Stanley's Shalett stays bullish on AI capex despite turmoil
Morgan Stanley Wealth Management's Lisa Shalett says AI infrastructure capital spending remains the bull market's main driver, even as Nvidia leadership turmoil and Democratic midterm wins stoke AI-boom concerns.
Bloomberg Technology·3 hours ago