Dust pretrains transformers without backpropagation
Read original source →qlabs.sh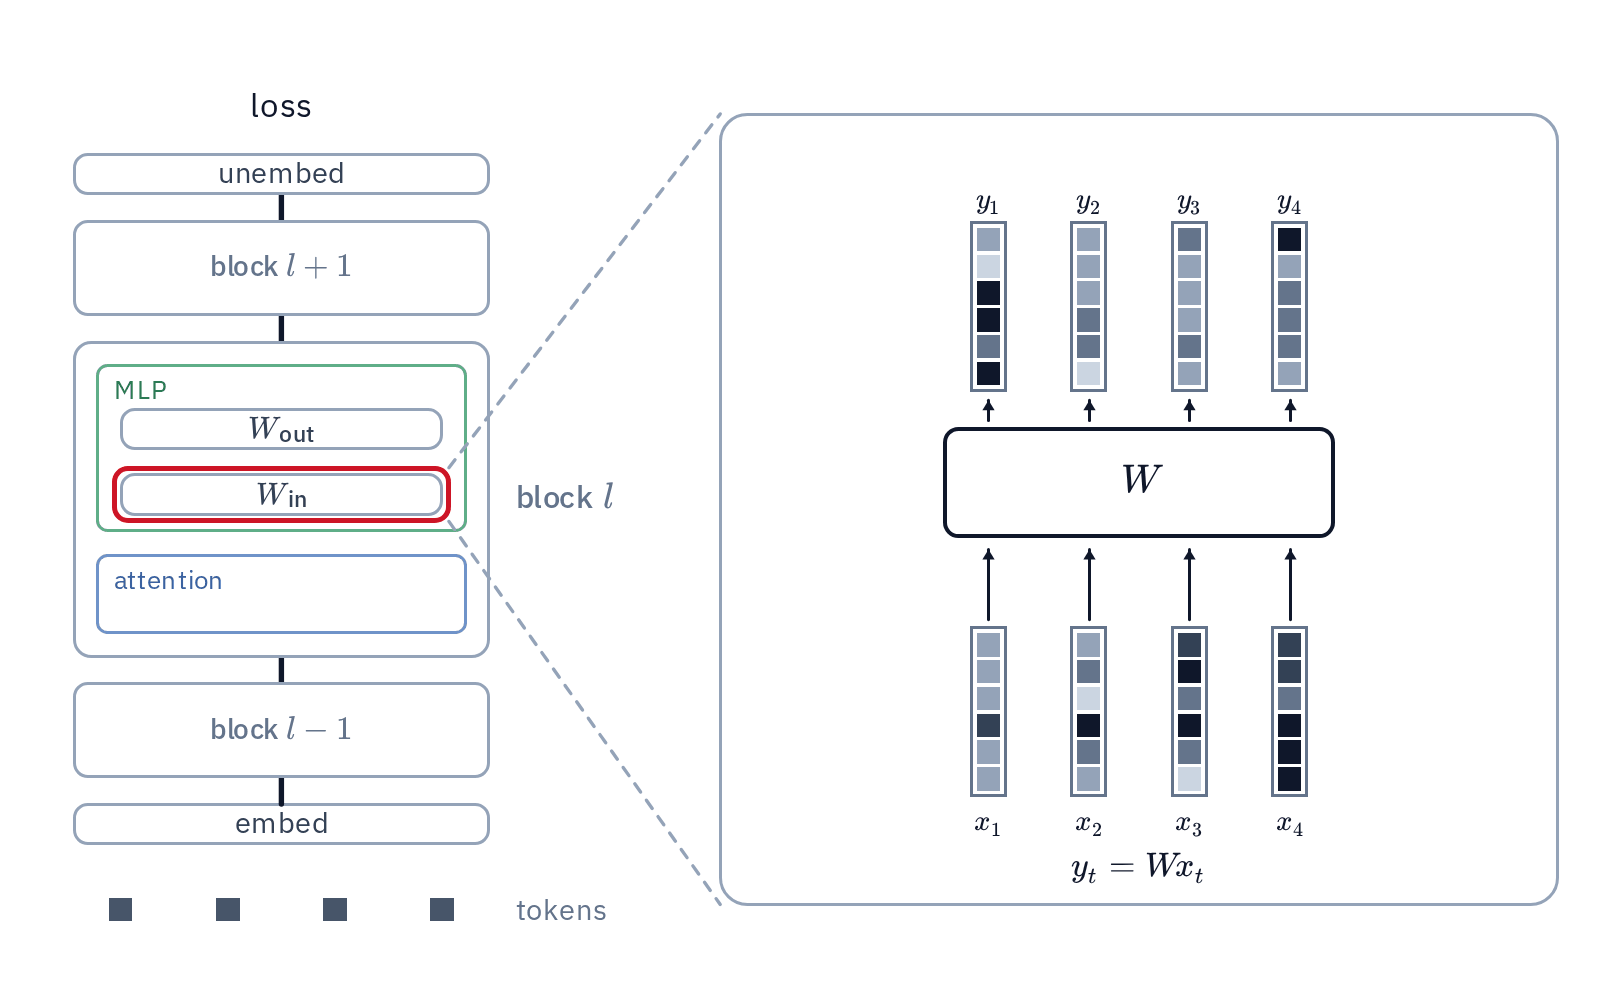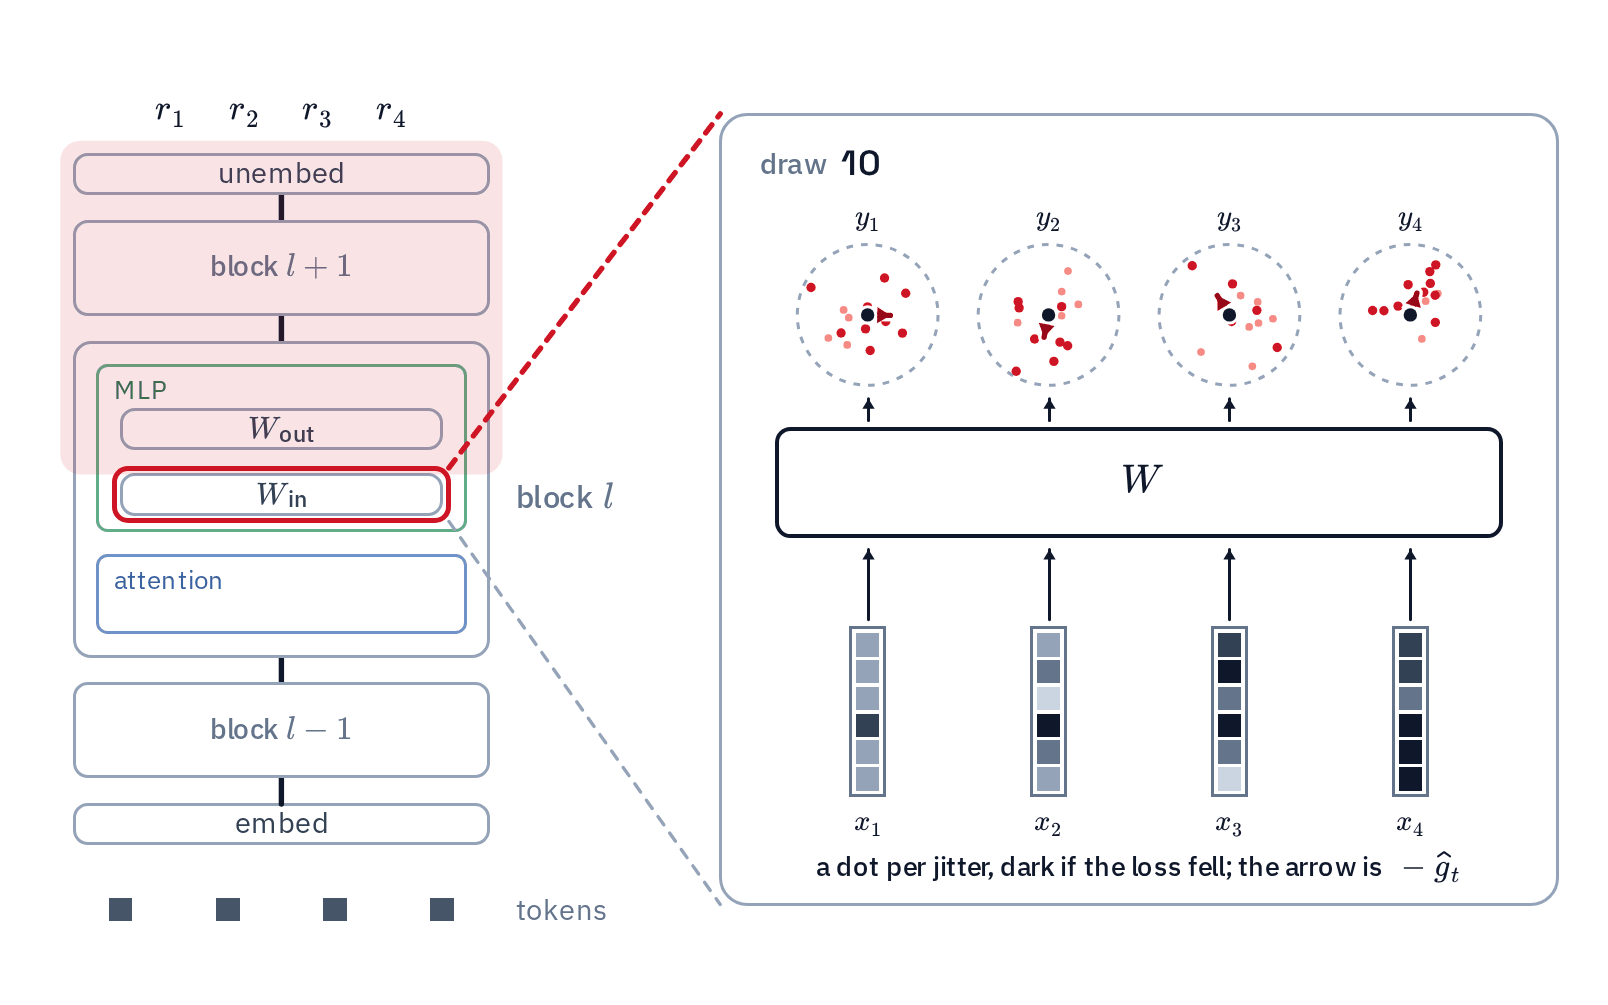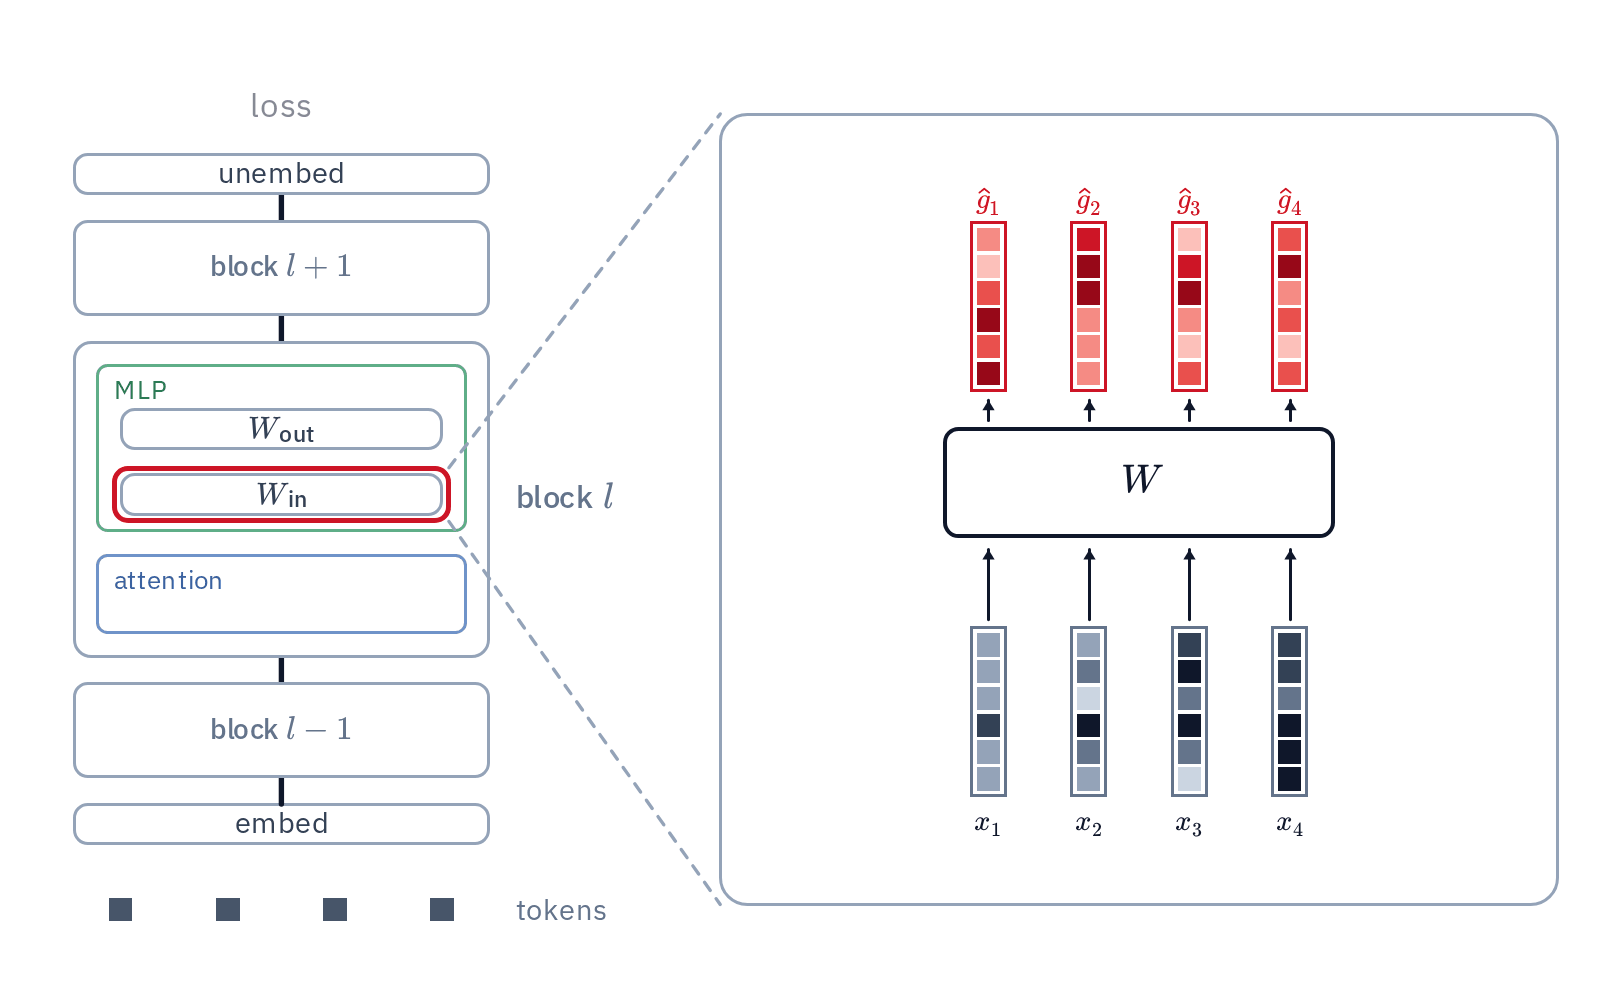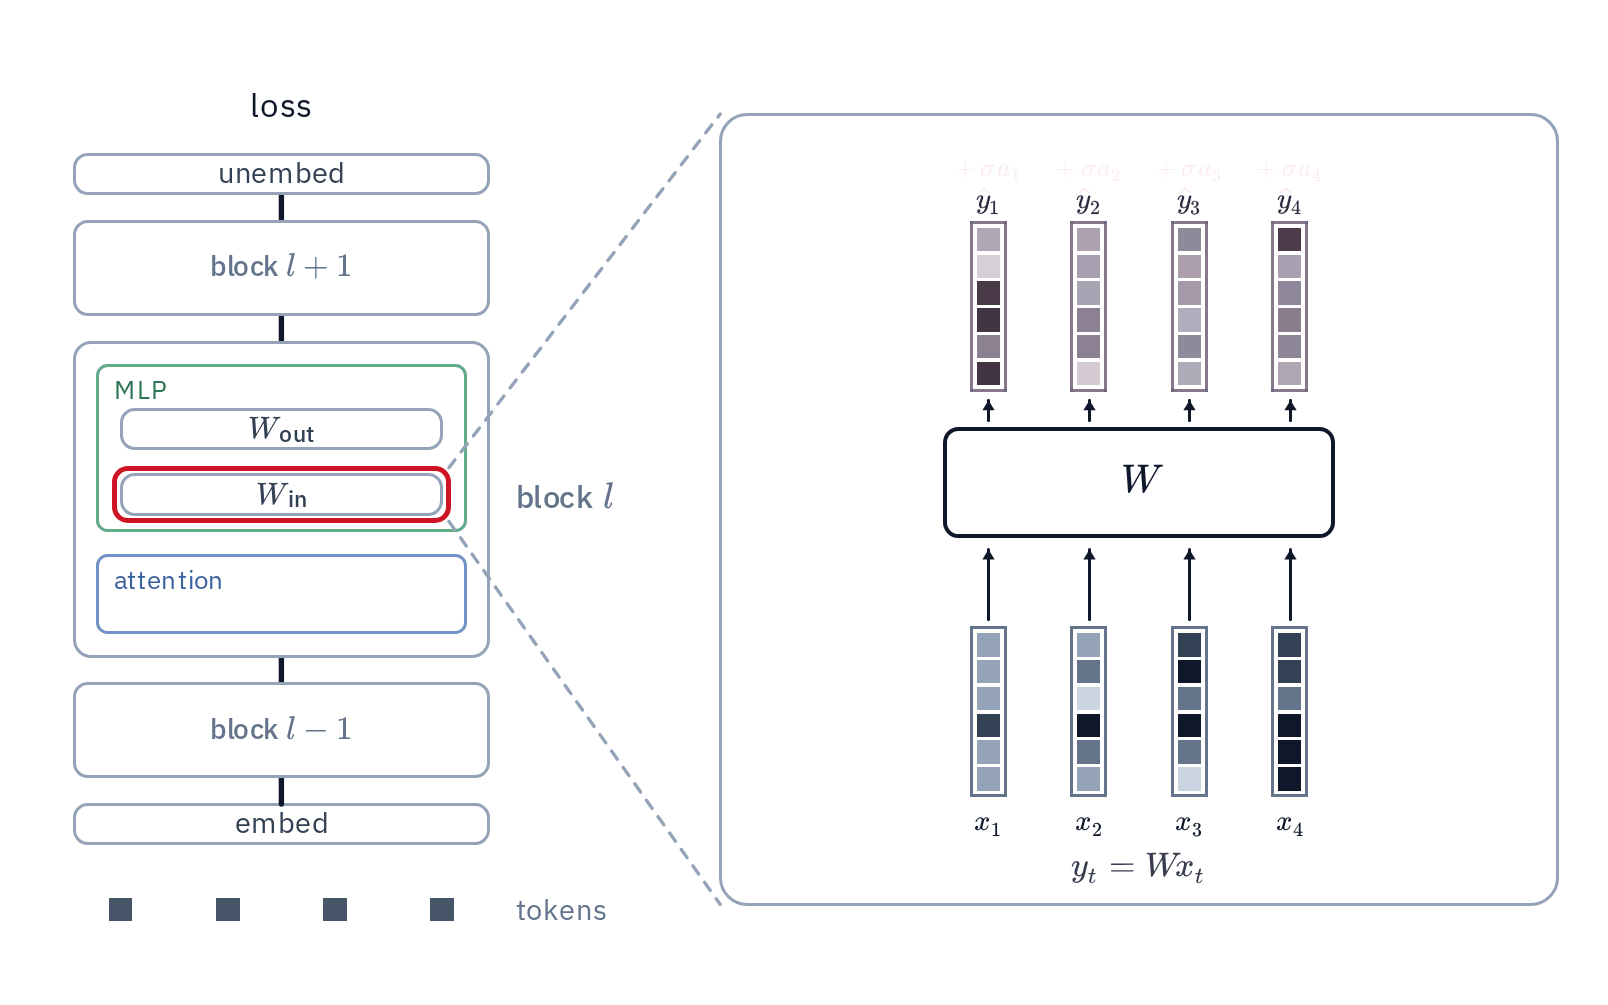
Dust perturbs activations per token, making each token a virtual population member so one forward pass evaluates all in parallel. It is 10^3–10^4x more efficient than EGGROLL, a state-of-the-art ES method, from 1M tokens up, and a 243M-parameter model outperforms a 120x smaller one at most population sizes.
1 source
More stories today
Critic argues "AI" ideology was never benign, not just recently toxic
Emily M. Bender·1 hour agoAI assistants shift from local VMs to dedicated cloud VMs
Ethan Mollick·1 hour agoClaude Code 2.1.290 adds hook telemetry and session-name commands
Claude Code v2.1.290 adds serverToolUses to a mod's turn.step hook result, exposing the API-run tool calls (the advisor) with id, name, input, and start/end times. Plugin hooks gain agentId on tool.check so a hook can distinguish a subagent's permission check from the main session's.
Claude Code Releases·1 hour agoTalk: LLM judges overstate web agent success, 74% vs 38%
Browserbase's Miguel González Fernández and Microsoft Research's Corby Rosset present research on verifiers for computer-use and web agents, where an official judge scored agent success at 74% while a better verifier put it at 38%.
YouTube·1 hour ago
GLM 5.3 now available on Amazon Bedrock
Amazon Bedrock adds GLM 5.3, an open-weight model aimed at coding and agentic workloads such as refactoring repositories spanning hundreds of files and sustaining multi-hour agentic workflows with tool use.
AWS AI Blog·1 hour ago

Gemini "Call for Me" may expand to personal calls
An APK teardown found a "Gemini Calling" intro screen with examples like "Call Mom and tell her I will be 15 minutes late" and "Call John and ask if he is coming for dinner." The teardown also surfaced granular per-app permissions, including phone call settings, though Google may never ship the expansion.
The Verge·1 hour ago

Talk shows observability loop for fixing failing AI agents
Laurie Voss of Arize AI demos a toy-store agent that fails a request for toys under $6 because its search tool lacks a price filter, then adds observability to trace the failure and has a coding agent patch it.
YouTube·2 hours ago
Tencent releases open-weight video model Prism
Tencent published open weights for a new video generation model, hosted on Hugging Face under the FrancisRing/Prism repository. The release surfaced via r/StableDiffusion, where the poster asked whether anyone had tried it yet.
r/StableDiffusion·2 hours ago