Tencent releases Hy4 flash weights: 224B MoE, 1M context
Read original source →huggingface.co
Tencent published open weights for Hy4 flash — standard, FP8, and Base variants — two days after launching it via its apps and cloud API. The natively multimodal model has ~224B parameters with ~12B active per token and a 1M-token context window.
How this story unfolded
1 day · 3 reports · 2 community posts · 5 of 9 shown
More stories today
UK MPs propose AI Safety and Security Bill to criminalise AI misuse
The Business, Innovation, Science and Trade Committee wants a new AI Safety and Security Bill criminalising "misuse of AI for harm", plus a liability regime and duties on AI service operators. MPs also urge a new regulator, separate from the AI Security Institute, with power to pull the plug on AI services and pause high-risk training.
r/artificial·1 hour ago
Cova demonstrates AI agent-based video editing for Twitch streams
cova·2 hours ago
Reddit user seeks tiny model for Raspberry Pi 4B skeleton-Santa gag
A r/LocalLLaMA poster wants a model that runs on a Raspberry Pi 4B with 4GB RAM to voice a skeleton dressed as Santa that gives deliberately wrong answers in conversations.
r/LocalLLaMA·2 hours agoICLR authors report reviewers ignoring rebuttals
One author's paper scored 3,3,2 received zero reviewer responses after the rebuttal; another reports no rebuttals or reviewer replies across a batch of 10-12 papers.
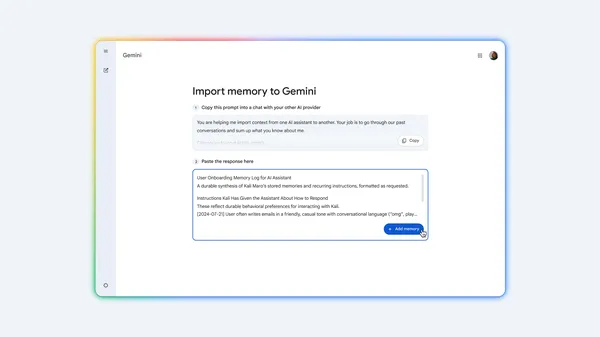
r/MachineLearning·2 hours agoGemini adds import tool to transfer chat history from other AI apps
Google's new Gemini import flow has users copy a prompt into their old assistant to summarize preferences, then upload a ZIP export of chat history in Gemini settings to resume prior conversations.
Google Blog·2 hours ago
Scott Alexander surveys AI forecasting's open problems
AI forecasters now match or beat top humans on traditional questions like ForecastBench and the Metaculus Cup, per Scott Alexander, who says ChatGPT and Claude trail specialized forecasting startups by about six months. He flags conditional forecasts as the key untested challenge.
Astral Codex Ten·2 hours ago
NVIDIA Dynamo targets rollout bottlenecks in RL training
NVIDIA's developer blog details how Dynamo's serving layer cuts wasted GPU capacity in RL training via routing, ModelExpress weight updates, and worker-failure recovery. It targets three constraints: slowest-rollout completion time, recomputed shared context prefixes, and weight freshness for sampling.
NVIDIA Developer Blog·2 hours ago

Meta's Muse Charm AI gadget may cost $300
The Information reports the screen-equipped device that lets users talk to Meta's Muse AI agent will be priced at $300, with a free 12-month Verizon 5G data plan. Zuckerberg said it would ship "in time for the holidays in December."
The Verge·2 hours ago
