Essay argues no posttraining data commons exists for LLMs
Read original source →openathena.ai
Open Athena's post credits pretraining to a 50-year digital commons — Wikipedia, ArXiv, Stack Exchange, Project Gutenberg and Common Crawl's ~10 petabytes — noting GPT-3 was ~60% Common Crawl-derived and the original Llama mix almost entirely web-sourced. It argues no equivalent shared corpus exists for posttraining.
1 source
More stories today
Developer demos GPT-6.1 Sol Ultrafast building live 3D models via API
Diego | AI 🚀 - e/acc·2 hours ago
Balestriero to present latest JEPA research at INFORMS
Randall Balestriero·2 hours ago
Qwen Code ships v0.26.7 with managed-agent backend refactor
Release v0.26.7 makes runtime backends optional Maven modules in the managed-agent refactor and repairs desktop RPM dependency and teardown checks in CI. It also re-runs a timed-out autofix-pr job.
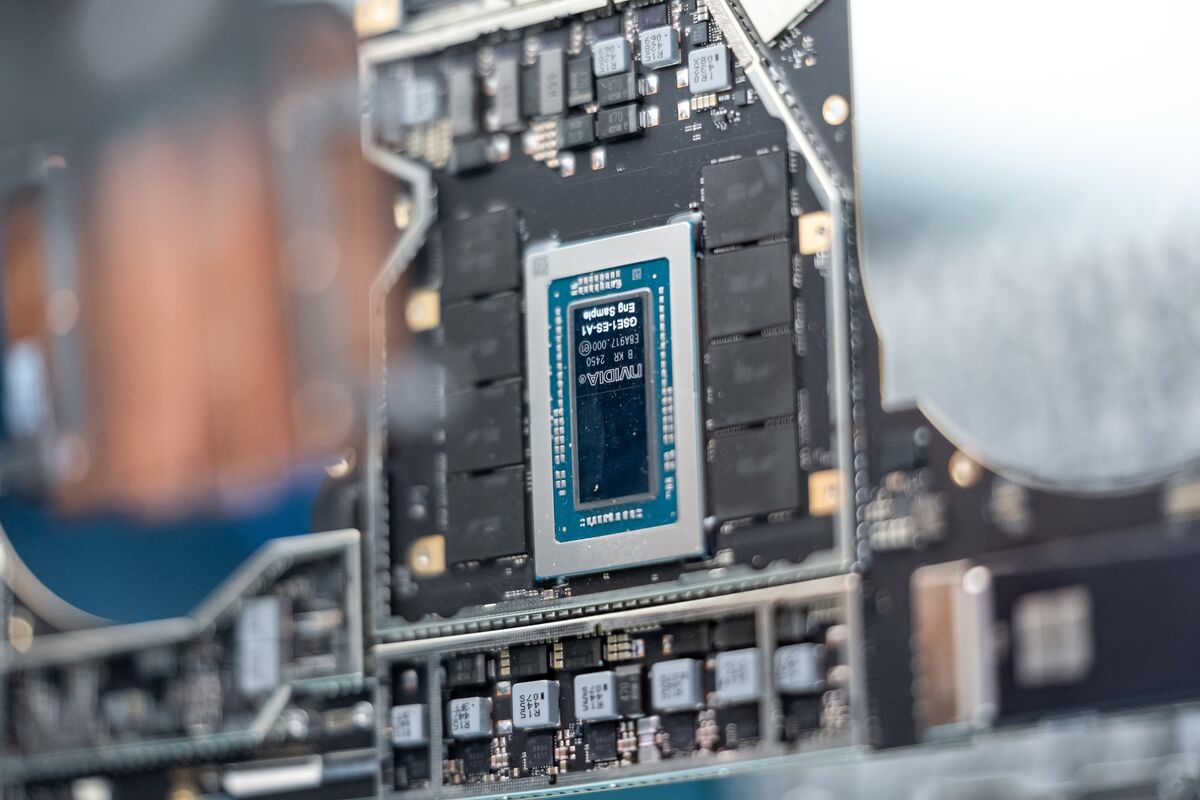
Qwen Code Releases·2 hours agoNvidia China clients to get 1% of $70B RTX chips ordered
Chinese AI developers expect only a small fraction of the advanced Nvidia chips they ordered over the next several months, as Nvidia struggles to raise production to meet soaring demand.
Bloomberg Technology·3 hours ago
BluePixel-Turbo edits images at native 4K in 4 steps
openvivo's BluePixel-Turbo is an instruction-based image editing model that produces native 4K output in four sampling steps, per its Hugging Face model page. No benchmark scores, parameter counts, or license terms are given in the available snippet.
r/StableDiffusion·4 hours ago
Civitai ends paywalls on Flux 2 Klein checkpoints
Civitai emailed users that Flux 2 Klein checkpoints will no longer sit behind paywalls, per a r/StableDiffusion post. The poster asks whether Black Forest Labs began enforcing license terms and whether other hosting sites will follow.
r/StableDiffusion·4 hours ago
Report: enterprise AI spend grew 5.4x to $177B, 69% to top 3 labs
Deedy Das·4 hours ago
Chollet co-signs call for AI to remain a tool in human hands
François Chollet·4 hours ago