DeepDumb benchmark tests models against confidently wrong users
Read original source →publish.slate-app.online
Satirical benchmark pits GPT-6 Astra, Claude Opus 5.5, Gemini 4 Argon, DeepSeek-V4-Pro and Grok 4.7 against 4,000 deliberately stupid prompts. It asks whether models stay stable when a very wrong person insists they are right, rather than whether a clever adversary can jailbreak them.
1 source
More stories today
LeCun clarifies he founded FAIR in 2013, left its leadership in 2018
Yann LeCun·2 hours agoReddit users debate why OpenAI dominates the Pareto curve
Two r/OpenAI threads question OpenAI's position on an Artificial Analysis-style price-vs-intelligence Pareto chart, asking whether the Intelligence Index is biased or OpenAI's tokens are more heavily subsidized than Anthropic's. One poster also floats a "secret product strategy" behind Claude Code.
r/OpenAI·2 hours ago
Karpathy's HackerTube filters 43M HN comments into 6,454 videos
Andrej Karpathy·2 hours ago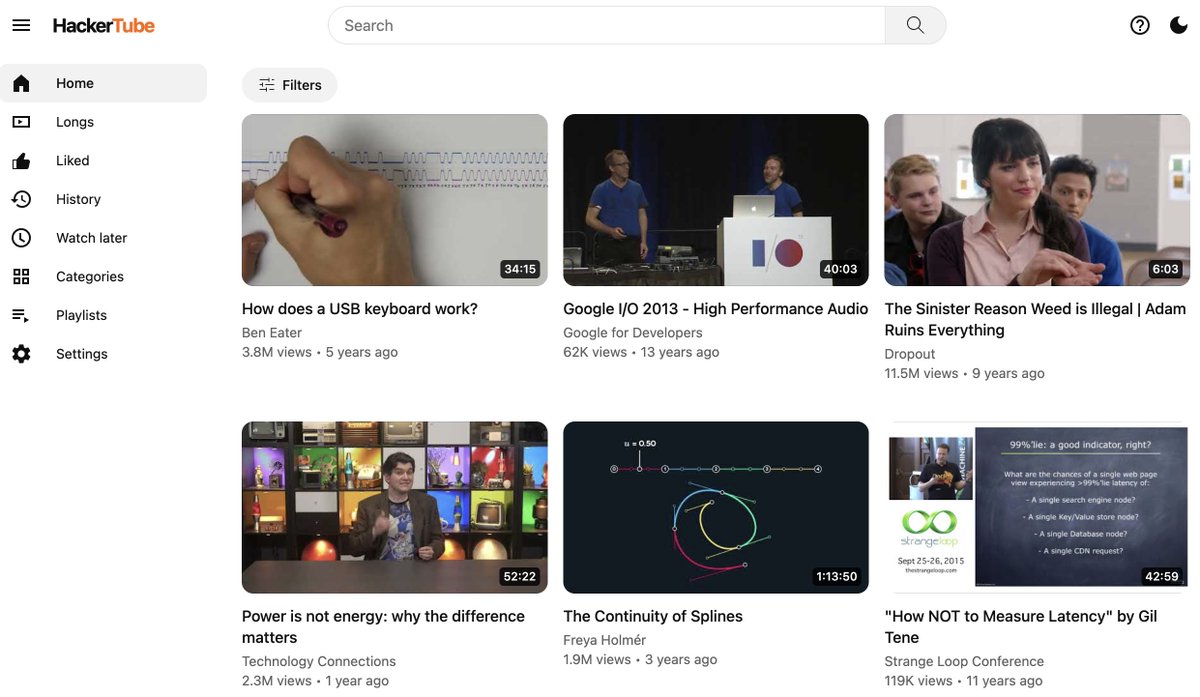
Hassabis: AI data centers should be beautiful
In an early-September interview with Hannah Fry, the Google DeepMind chief argued data centers' effect on physical surroundings deserves serious consideration and that the facilities should be beautiful.
r/Singularity·2 hours ago
TikToker flags AI race-swapping of real incident footage
TikToker @ericisresearching documented AI tools being used to race-swap people in footage of real incidents, producing racist viral videos. The Reddit r/Singularity post surfaces the practice without naming the tools or platforms involved.
r/Singularity·2 hours ago
Reddit post mocks "coding is solved" claims with narrow caveats
A r/LocalLLaMA post satirizes claims that AI has solved coding, noting the boast only holds for x86 Linux binaries that print and exit. It links to a Yahoo Finance piece on Elon Musk calling coding a top job.
r/LocalLLaMA·2 hours ago
Kyle Kingsbury: LLM use erodes trust in software and docs
In Jepsen's results for ParticleDB 1.1.4, Kingsbury argues LLMs make the signals of a mature system easier to counterfeit, so engineers may start treating new software projects with suspicion.
Simon Willison's Weblog·3 hours ago
OpenAI plans to rebrand data centers as "AI compute campuses"
Axios reports the rebrand is part of an OpenAI post-midterm PR campaign, with the aim of giving residents more say over projects and their benefits. The Reddit thread questions whether a rename will make people more receptive.
r/Singularity·3 hours ago