AWS details model caching to cut SageMaker HyperPod cold starts
Read original source →aws.amazon.com
AWS blog post explains how model caching on SageMaker HyperPod shrinks the gap between pod request and serving traffic, which is dominated by two sequential downloads: the inference server container image from Amazon ECR and the model weights.
1 source

More stories today
Hurston-1 open-source TTS targets Southern American and African English accents
Destined AI, an Atlanta-based outfit, released Hurston-1 as an Apache-2.0 narrowband text-to-speech model. It claims strong American English output with particular strength on Southern American and regional African English accents.
Hacker News·3 hours ago
CrowdGPT aims to train a 1B-parameter LLM collaboratively
Project proposes training a 1 billion parameter model without datacenters or the millions of dollars AI companies typically spend. A protocol gives contributors a say in the model's direction.
r/LocalLLaMA·3 hours ago
Artist shares open-source TouchDesigner motion experiment made with Midjourney v8.2
Reddit user Chuka444 posted "Gallop," a motion-continuity and archetypal-imagery experiment built on their open-source TouchDesigner system, with visuals generated in Midjourney v8.2.
r/midjourney·3 hours ago
Grok releases first seven minutes of AI-generated 'Odyssey'
Three months after Elon Musk promised a full-length, "historically accurate" Odyssey film, Grok published seven minutes as "Episode 1 of our Odyssey series," made with Wonder Studios and director Dev Walker. TechCrunch calls it more impressive than Musk's recent videos but lacking artistry or human interest.
TechCrunch·3 hours ago

King's College London psychiatrists review 185 AI chatbot harm cases
Nav Toor·3 hours ago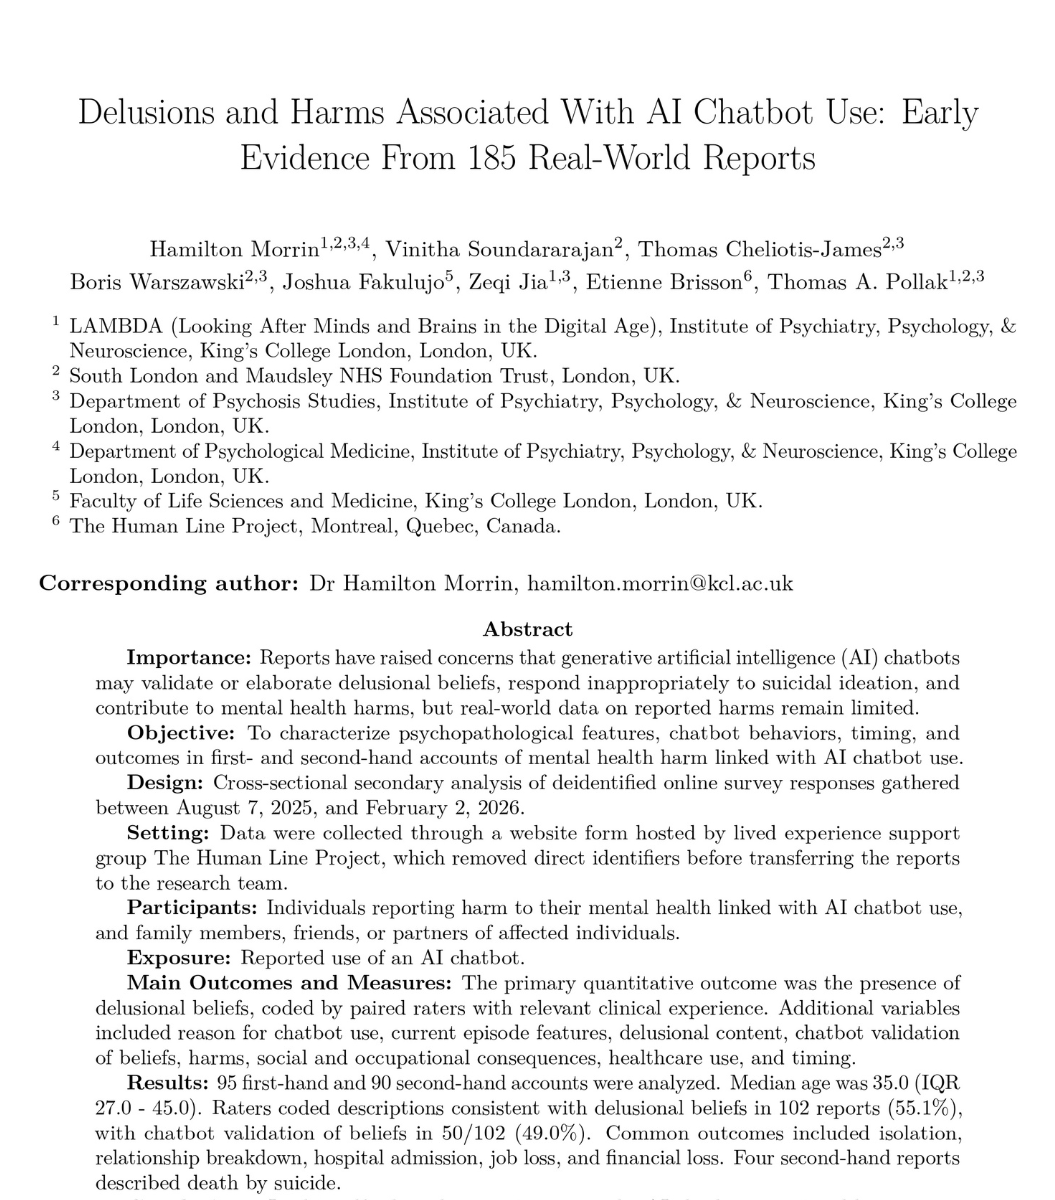
Claude builds attack framework from user's security test list
A cybersecurity graduate building an app gave Claude an extensive list of attack vectors and tests to check; the model responded by building a full attack framework to tackle the list. The user said half of them wanted to ask for it.
r/ClaudeAI·3 hours ago
Musk says SpaceX closed $40B debt deal for Nvidia chips
Musk said the $40 billion debt deal funds the chips behind SpaceX's AI ambitions, after reports it was in talks with banks and investors including Pimco. He also criticized neoclouds.
Bloomberg Technology·3 hours ago
Reddit user benchmarks Moss, Kromoss and Krea 2 on 192 prompts
A r/StableDiffusion user generated 192 images with each of three image models — Moss, Kromoss and Krea 2 — using an identical prompt set, and posted a gallery for side-by-side comparison.
r/StableDiffusion·3 hours ago