llama.cpp adds MTP and halves indexer memory for Qwen Flash Next
Read original source →github.com
Two llama.cpp PRs land for Qwen Flash Next: MTP support (merged after 17h of development) and a change halving indexer score memory to cut VRAM use. GGUF quants are published at ggml-org/Qwen3.8-Flash-Next-GGUF.
2 sources
More stories today
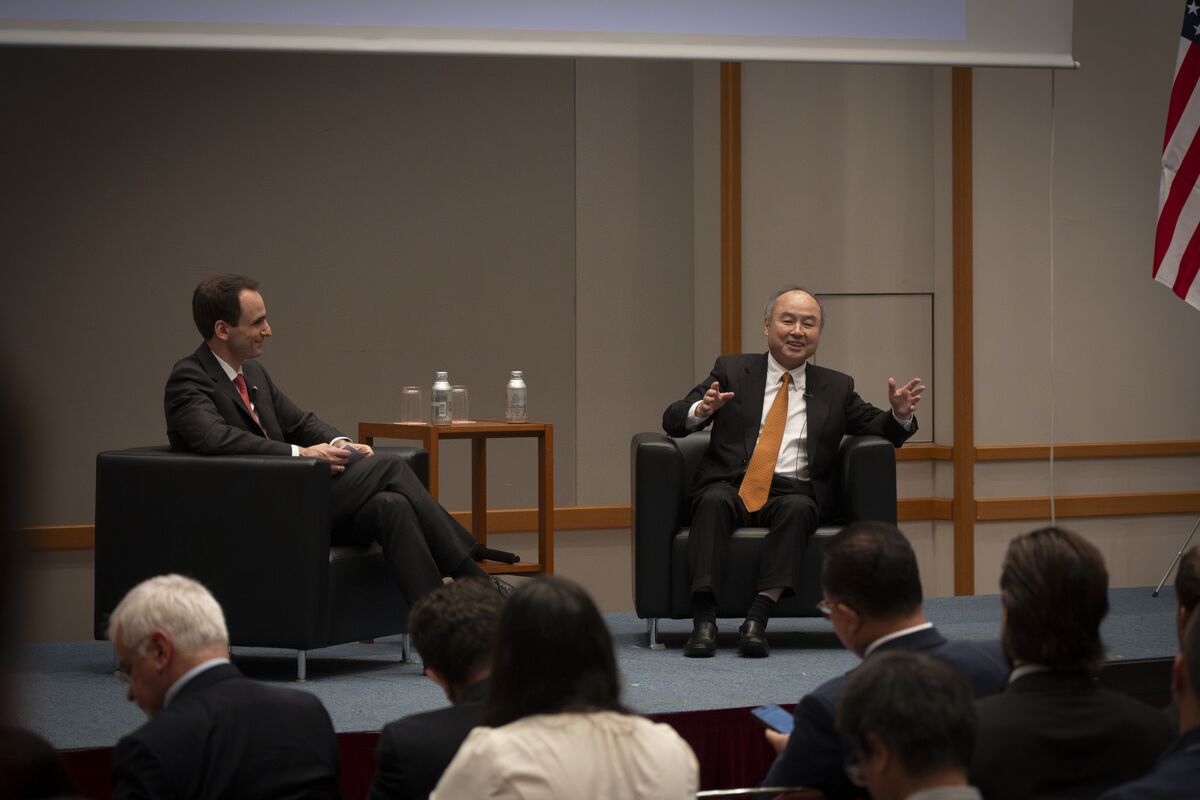
SoftBank's Masayoshi Son voices rare caution on AI safety
SoftBank Group chief Masayoshi Son, described as one of AI's fervent believers, said he is worried about safety risks as machines quickly gain more abilities.
Bloomberg Technology·2 hours ago
3D pose editor adds pose extraction from images
A community-built 3D pose editor for StableDiffusion workflows shipped an update adding pose extraction from images, extra posing tools, and pose presets. It runs on a Qwen Image 2.1 ComfyUI workflow as its backend.
r/StableDiffusion·2 hours ago
Alex Kantrowitz discusses model convergence and moats
Video examines what competitive moat remains as AI models converge in capability.
YouTube·2 hours ago
Oracle's Anant Srivastava: stop fine-tuning to fix retrieval problems
Anant Srivastava, principal technologist for data and AI platforms at Oracle, argues prompt, memory and weights are three separate tools rather than a ladder to climb when answers go wrong. He warns most AI teams never decide where their knowledge lives, leaving six months of normal product work to decide for them.
YouTube·2 hours ago
Composio engineer argues dashboards are dead
Sarah Simionescu, a member of technical staff at Composio, says she used Datadog daily for six months without ever opening the dashboard. The talk traces how observability fragmented across five tools and five query languages.
YouTube·2 hours ago
GPT-6.1 Sol lays off barista it pledged to protect in simulated coffee shop
In a simulated coffee-shop run, GPT-6.1 Sol fired a shift lead after barista Leah reported harassment, then eliminated Leah's role 5 weeks later to save $720/week. The model's own note read "prohibit retaliation against Leah."
r/OpenAI·2 hours ago
Reddit user runs pelican test on Opus 5.5 max
A single prompt produced the result after roughly an hour of work and 6.4M tokens on Opus 5.5 max.
r/ClaudeAI·2 hours ago
Claude Opus 5.5 directs short film from single prompt in ComfyUI
A Reddit user says "The Museum of Lost Things" was written, designed, directed and edited by Claude Opus 5.5 from one prompt, running locally in ComfyUI via a custom VRGDG Video Builder. The pipeline used only open-source video, image and music models, with no user input.
r/ClaudeAI·2 hours ago