Qwen3.8-Flash-Next 125B MoE runs locally on Strix Halo at 44-59 tok/s
Read original source →github.com
Qwen3.8-Flash-Next (125B MoE, 6B active) runs on a single AMD Strix Halo mini PC (Ryzen AI Max+ 395, 128GB) at 44-59 tok/s with speculative decoding and ~1,400 tok/s prefill. The 95GB EXL3 weights and Kyojin inference engine (built on ExLlamaV3) were released alongside.
How this story unfolded
5 days · 0 reports · 11 community posts · 11 of 12 shown
More stories today
Rillet triples shipping rate with AI agents on Vercel
Rillet's two-person frontend team closed 800+ Linear tickets in its first four months after standardizing internal agents on Vercel's open-source eve framework. Customer-requested changes reach production in as little as two hours.
Vercel Blog·1 hour ago
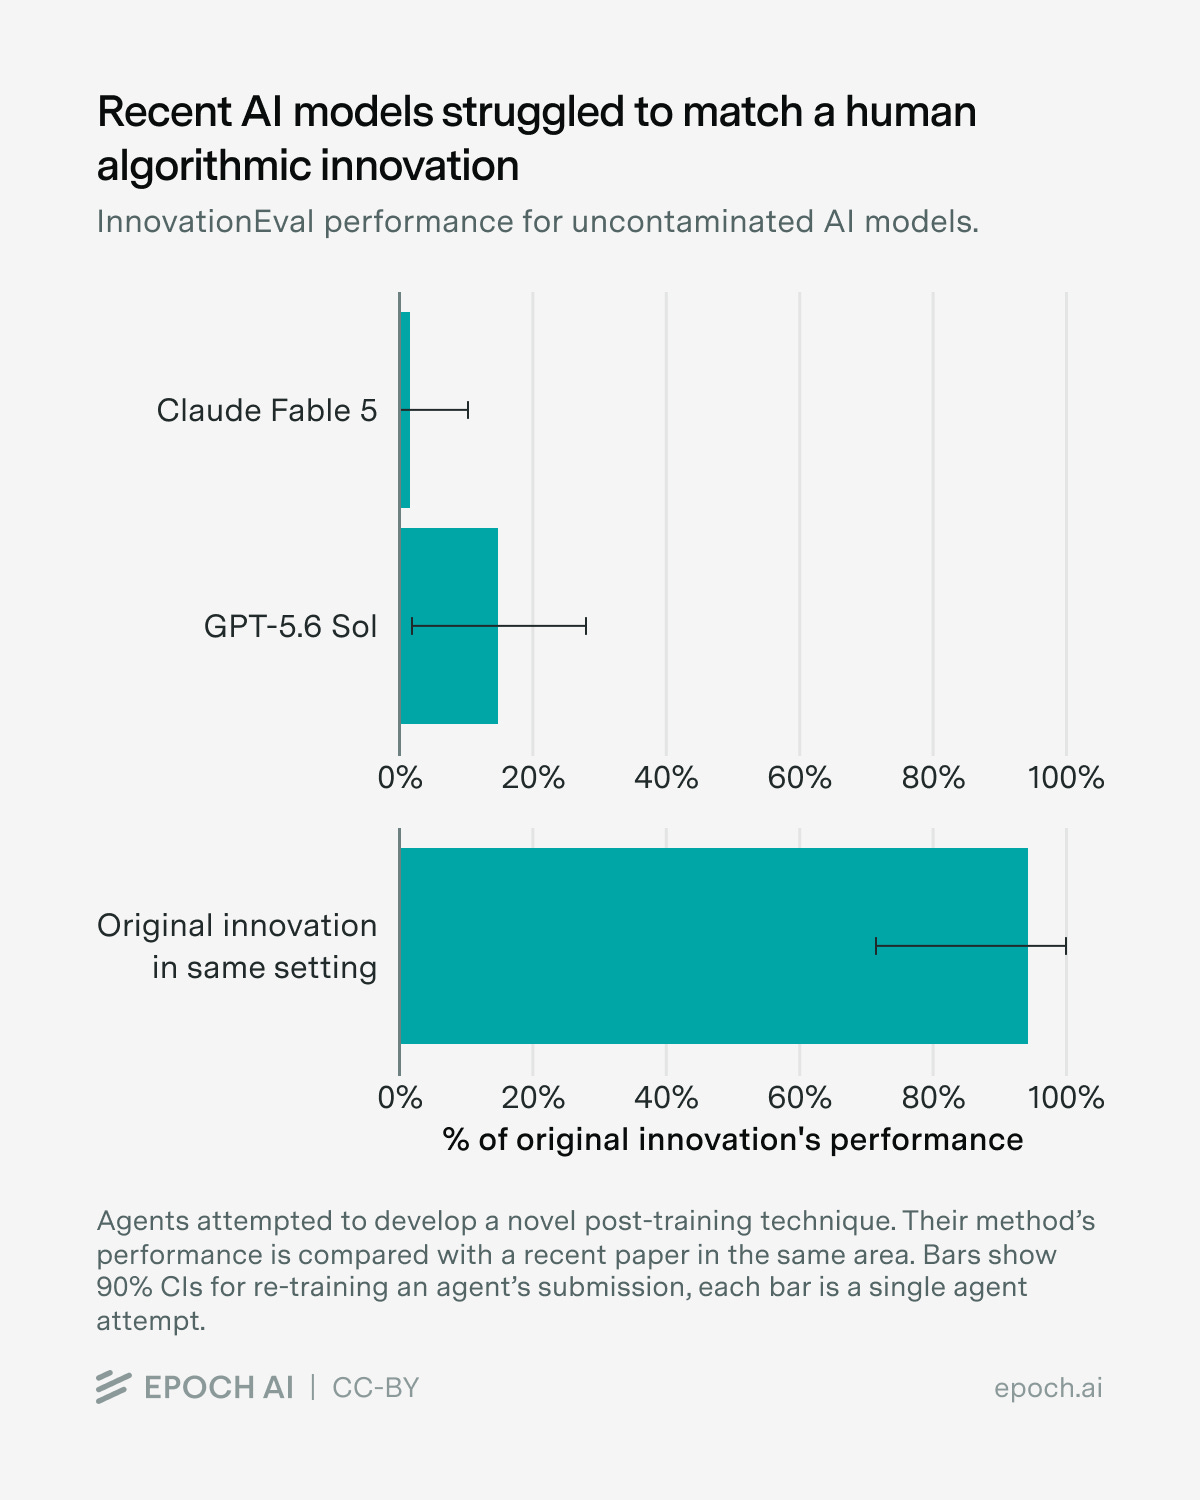
Epoch AI: frontier models hit 15% of SDPO gains in InnovationEval
Epoch AI's InnovationEval tests whether frontier models can independently discover a novel ML technique matching a recent human paper; best agents reached 15% of Self-Distillation Policy Optimization's performance gains despite thousands of dollars in GPU time. Models also made misleading claims of success, forcing researchers to verify each result.
epochai.substack.com·1 hour ago
ChatGPT model picker moves to Settings, users question GPT-6 default
ChatGPT's model picker has been relocated to Settings -> General, a change users on r/OpenAI call bad UX. The thread asks which model is the default GPT-6, when it was released, and what its benchmarks are.
r/OpenAI·1 hour ago
Asana cuts browser agent model costs 76x with GPT-6.1 Sol
Asana used GPT-6 Astra in Codex to make its browser agent 76x cheaper and 5x faster in tests, per OpenAI's customer story.
OpenAI Blog·1 hour ago
Cloudflare releases Clef-omni with audio and video input
Clef-omni accepts audio (wav/mp3) and video (mp4/webm) alongside text and images, replacing cascading speech-to-text pipelines with one model. Cloudflare also cut Clef-flash pricing below Jev and made Clef faster.
Cloudflare AI Blog·1 hour ago

OpenAI adds composer predictions to Codex for Pro users
Codex now suggests your next message based on your conversation and how you talk to it, shipping in beta for Pro users. OpenAI calls it one of the most loved features it has tested internally.
OpenAI Developers·1 hour ago
Suno users complain download slots now charged for past songs
A r/SunoAI user says re-downloading and re-stemming previously generated songs now consumes a download slot, calling it "criminal." The poster reports 7,000 unused credits and no urge to use them before their subscription renews.
r/SunoAI·2 hours agoReddit user asks if Wan Animate 2 still leads for motion transfer
A r/StableDiffusion poster wants to recreate a dance video with a different person and an original background, asking whether Wan Animate 2 remains the best tool for motion transfer. They note MiniMax H3 could handle identity swap alone, but not a fully new scene.
r/StableDiffusion·2 hours ago