Paper proposes Q-Learning with Scalar Adjoint Matching for flow policies
Read original source →arxiv.orgThe method targets off-policy RL fine-tuning of flow policies, which is difficult because the policy generates actions over many steps against a learned value function. Author listed as Yonghoon Dong.
1 source
More stories today
LegalOn cuts Codex costs 65% with task-based model routing
LegalOn cut estimated daily Codex costs by 65% while maintaining development speed, matching Astra, Sol, and Luna to tasks and managing budgets strategically.
OpenAI Blog·3 hours ago
MiniMax H3 open-source video world model claims physics lead
MiniMax says H3 is "almost on par with closed-source sota" for physics in open-source video world models, two months after release. H3 generates video with native stereo audio and multimodal reference control under open weights.
MiniMax·3 hours ago
Block uses Claude Fable 5 to orchestrate code migrations across thousands of PRs
Bradley Axen, Block's Head of AI Capabilities, describes applying agent orchestration patterns with Claude Fable 5 for company-wide code migrations. Block also builds Buzz, an open-source workspace for human-agent teams, and evaluates frontier models including Claude Opus 5.
Claude Blog·4 hours ago
ConwayResearch releases Underdog-Saluki-27B-1.0 on Hugging Face
The 27B model drew 101 likes and 142 downloads on Hugging Face, trending at rank 99. No benchmark results or license details were published with the release.
Hugging Face Models·4 hours ago

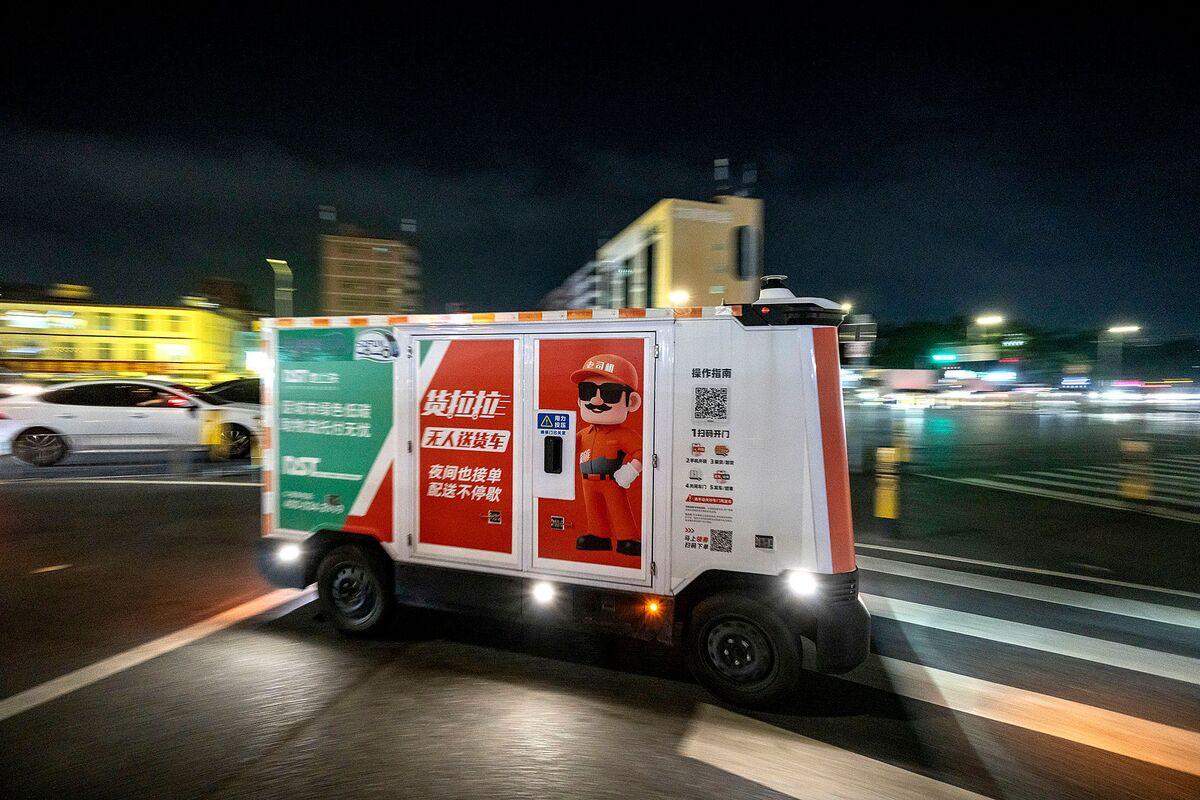
China's delivery robots take on the night shift
Chinese autonomous vehicle companies are targeting overnight deliveries, betting on a large market opportunity if technical hurdles can be overcome. Bloomberg reports the push centers on after-dark logistics.
Bloomberg Technology·4 hours ago
LeAVJEPA: Self-Supervised Learning From Sound and Vision
Arno Solin·4 hours ago
Strata rewrote GitHub history to strip Claude co-author credits
A Reddit user reports every historical commit in Strata's repo was rewritten to remove "Co-Authored by Claude" text, breaking the built-in UPDATE script with a git "no common ancestor" error.
r/LocalLLaMA·4 hours agoAtomic Agent Desktop app runs Qwen and Gemma locally
TestingCatalog News·4 hours ago