Qwen 3.8 Flash Next runs 130k context on 16GB VRAM
Read original source →reddit.com
A Q4_K_M quant of Qwen 3.8 Flash Next with Q8 cache hits 15-20 t/s on a 4080 with 16GB VRAM and 64GB RAM. The setup requires a specific quant, model branch, and cache flags, documented in a GitHub repo.
1 source
More stories today
Cagliostro V3.5 135M tops Open SLM Leaderboard
BenchLabs' Cagliostro V3.5 135M takes first place on Hugging Face's Open SLM Leaderboard with an Intelligence Index of 27.49, displacing SmolLM2-135M.
r/LocalLLaMA·2 hours ago
Developer builds Rust open-source replacements for 7 Adobe apps
A developer says agents helped recreate Photoshop, Illustrator, Premiere, Lightroom, After Effects, InDesign and Acrobat Pro in 100% native Rust, free and open source. The builds are early versions — PhotoCraft is not yet ready to replace Photoshop.
Kimmonismus·2 hours ago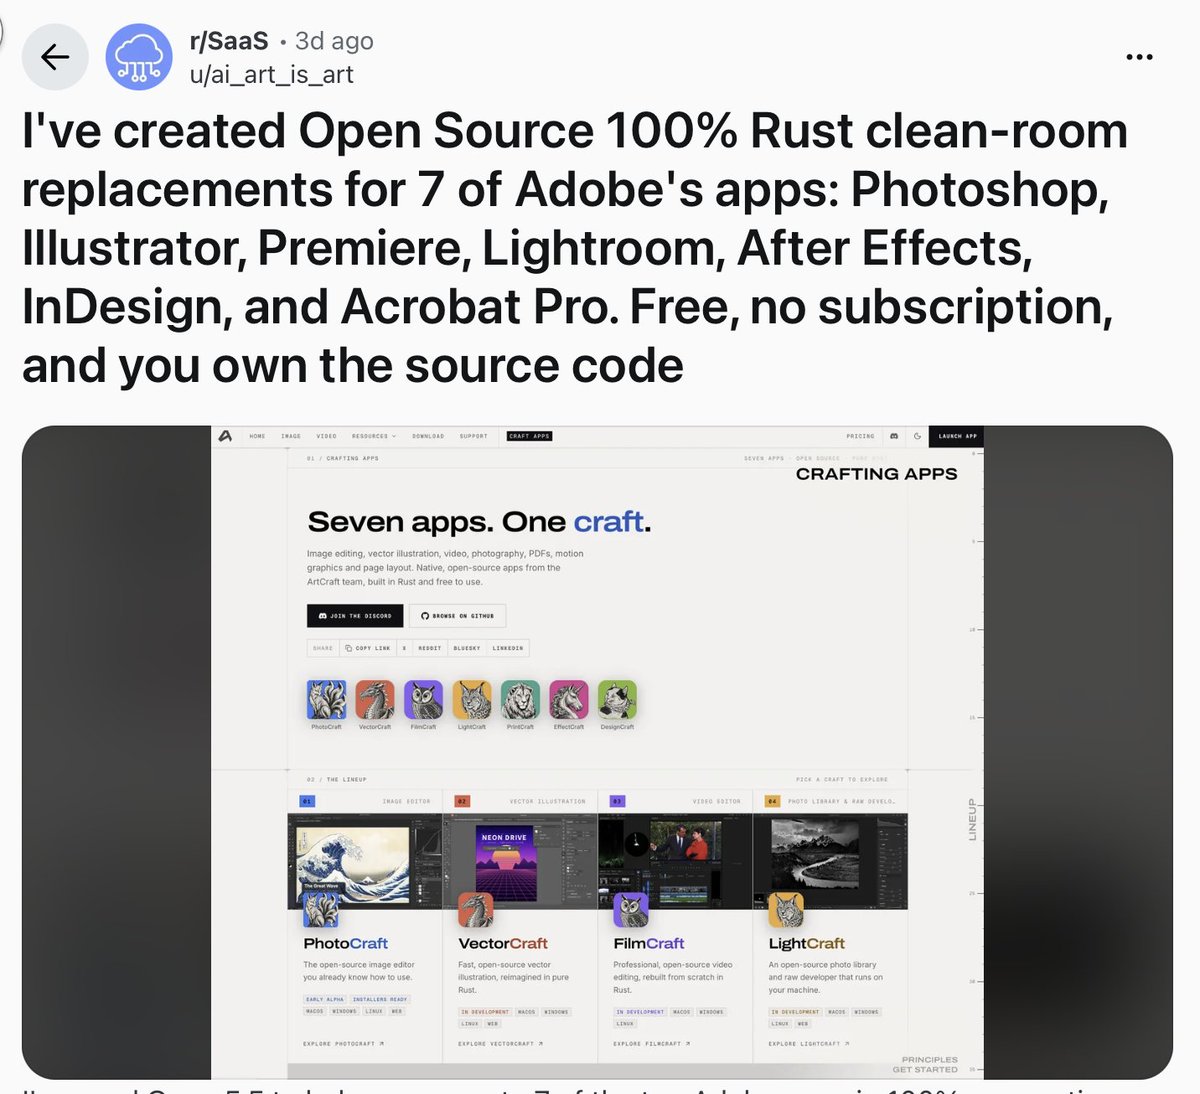
Qdrant-backed course teaches on-device memory for AI assistants
DeepLearning.AI·2 hours ago
Chollet: jagged frontier may be math and code, rest plateauing
François Chollet·2 hours agoAmjad Masad: AI reverse engineering will make all software de facto open-source
Amjad Masad·2 hours agoChatGPT adds Meetings plugin for note-taking
TestingCatalog News·2 hours ago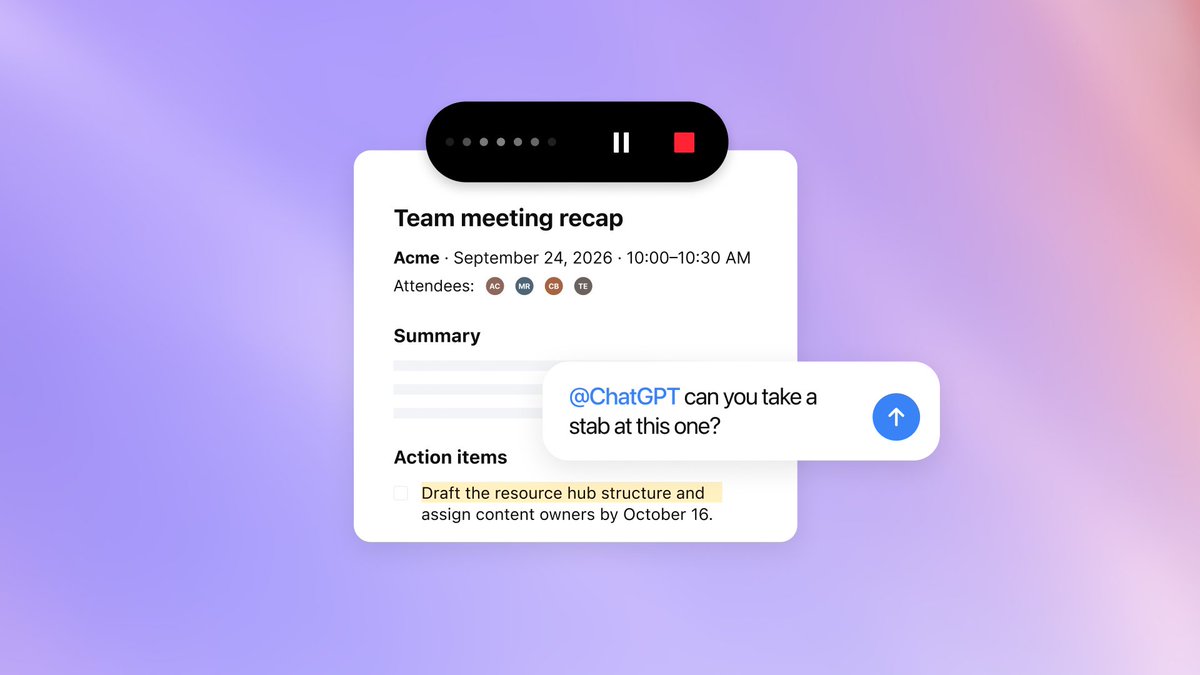
Computer in Email schedules meetings using your calendar
Daniel Wang·2 hours ago
Creator makes 3-minute AI comedy short with Claude, Minimax H3, ComfyUI
A Reddit creator built a 3-minute therapist-office comedy from a one-message brief using Claude for scripting, Minimax H3, and a custom ComfyUI video builder. The workflow generated characters including a crying woman and a screaming woman alongside one male doctor.
r/StableDiffusion·2 hours ago