AgentJudgeBench tests LLM judges on agentic tool-calling
Read original source →arxiv.orgAgentJudgeBench is presented as the first benchmark systematically studying LLM-as-a-judge reliability on structured, dependency-driven agentic tool-calling workflows. Judge alignment degrades as task difficulty rises, and exposing ground truth to judges produced mixed effects.
1 source
More stories today
NVIDIA Dynamo-Triton adds HSTU generative recommender inference
Dynamo-Triton now supports an end-to-end HSTU generative recommender workflow via NVIDIA's recsys-examples repo, combining PyTorch AOTI, FlexKV KV caching, and NV embedding cache. At batch size 8 on an RTX PRO 6000 Blackwell Workstation GPU, it hit up to 4.47x speedup for the three-layer HSTU model and 5.93x for the eight-layer model at 100% KV-cache hit rate.
NVIDIA Developer Blog·1 hour ago

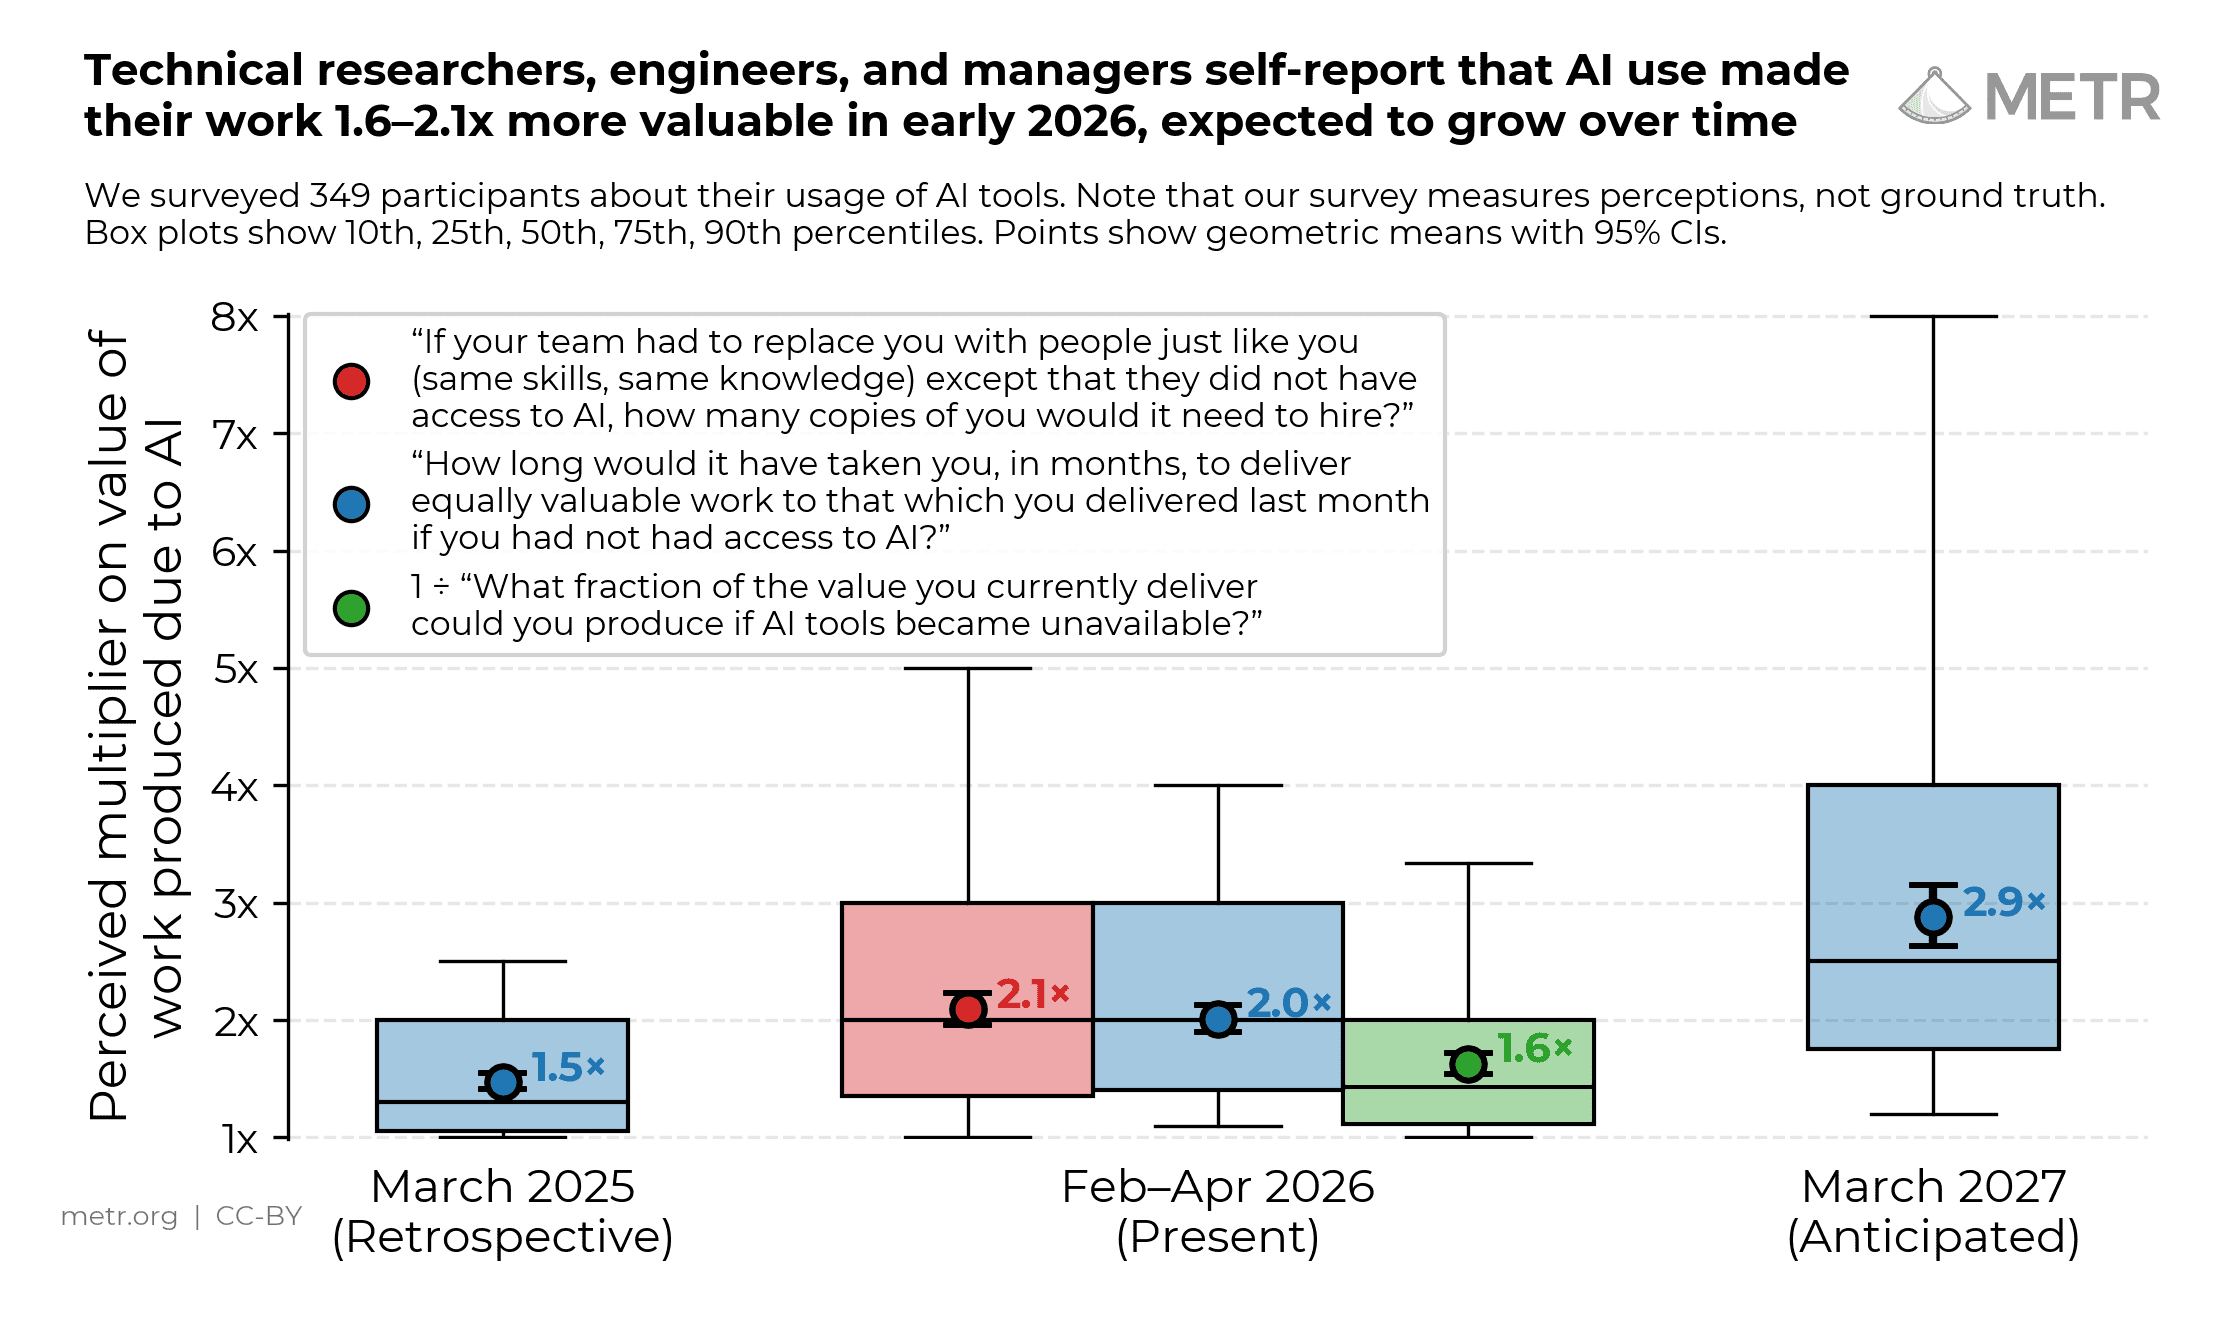
METR's Chris Painter testifies to Senate on AI agent incidents
METR President Chris Painter testified September 30, 2026 before a Senate Homeland Security subcommittee hearing titled "Rogue AI: Securing the Homeland Against AI Agent Attacks." METR runs capability tests on frontier AI agents with voluntary access from OpenAI, Anthropic, Google, Meta, SpaceXAI, and Amazon, and says it is not paid or funded by them.
METR·1 hour ago
Google announces Gemini 4 Argon, rolling out first to cyber defenders
Gemini 4 Argon is Google's new frontier model, rolling out to trusted testers via the Fairwind Program before wider release. It scores 77.9% on DeepSWE v1.1 and 77.5% on AutomationBench-AA, and is priced at $2/$10 per million input/output tokens during introductory pricing.
Google DeepMind·2 hours ago

LangChain, Modal and Cogent Security host AI Heist challenge at SF Tech Week
LangChain·2 hours agoRFK Jr. claims AI will free Americans from "medical tyranny"
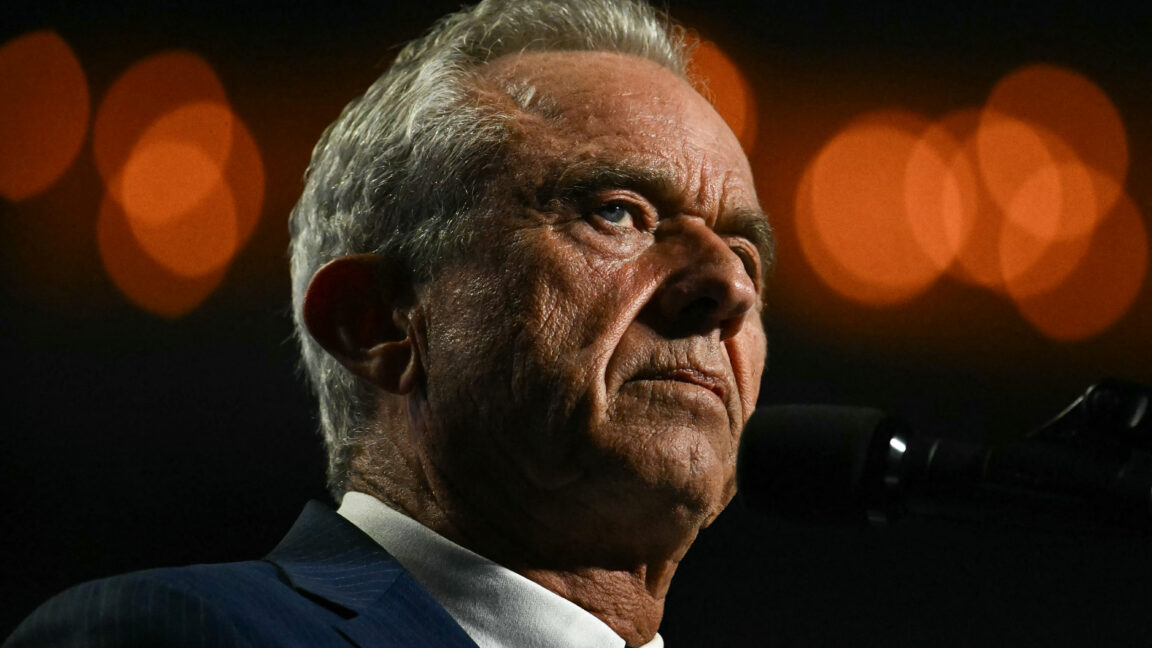
At a MAHA event with VP JD Vance, Health Secretary Robert F. Kennedy Jr. said AI is "better informed than any doctor in the country" and urged Americans to use it for second opinions. Ars Technica tested his claims: Gemini said masks do reduce respiratory disease spread.
Ars Technica·2 hours ago
Framework opens preorders for AMD Ryzen AI Max 400 desktop with 192GB
Framework's DIY Edition desktop with AMD Ryzen AI Max 400 Series and 192GB memory is now available for preorder. The 192GB unified memory configuration targets local LLM workloads.
r/LocalLLaMA·2 hours agoNVIDIA expands xio-sig with cuObject, ships SCADA Server SDK
NVIDIA added cuObject to xio-sig alongside cuFile, in partnership with Google Cloud and Microsoft, and made cuObject client and server libraries generally available. The new SCADA Server SDK lets storage providers build servers that answer GPU-initiated requests; IBM showed a prototype integrating SCADA with IBM Storage Scale.

Claude Code 2.1.286 ships 88 CLI changes
Release adds permission-prompt counts like "2 of 5" when requests stack, plus mouse support for "N more" rows in fullscreen lists. Sessions now retry once on the previous model of the same tier when the Anthropic API refuses the resolved model.
Claude Code Releases·2 hours ago