Reddit user scales local LLM rig from one RTX 3090 to 20 DGX Sparks
Read original source →reddit.com
A r/LocalLLaMA poster describes upgrading from a single RTX 3090 to 20 DGX Sparks for local inference, saying the house electrical fuses were the first bottleneck. The build began with LLaMA 33B and 65B models run locally.
1 source
More stories today
Reddit user asks how to improve Qwen creative writing
A r/LocalLLaMA poster asks for ways to boost creative writing in local Qwen models, saying Qwen beats Gemma and Muse at research and writing HTML files but trails them on creative writing.
r/LocalLLaMA·48 minutes agoQwen Code ships v0.24.7 nightly with Code Mode and permission fixes
Nightly build v0.24.7-nightly.20261004.9915c7ff8f aligns Code Mode text with lazy tool discovery and honors approved cross-directory tool calls. It also stops the CLI from swallowing Enter while completion suggestions load.
Qwen Code Releases·1 hour agoMustafa Suleyman interview flagged as must-watch on AI safety
Bill Gurley·1 hour ago
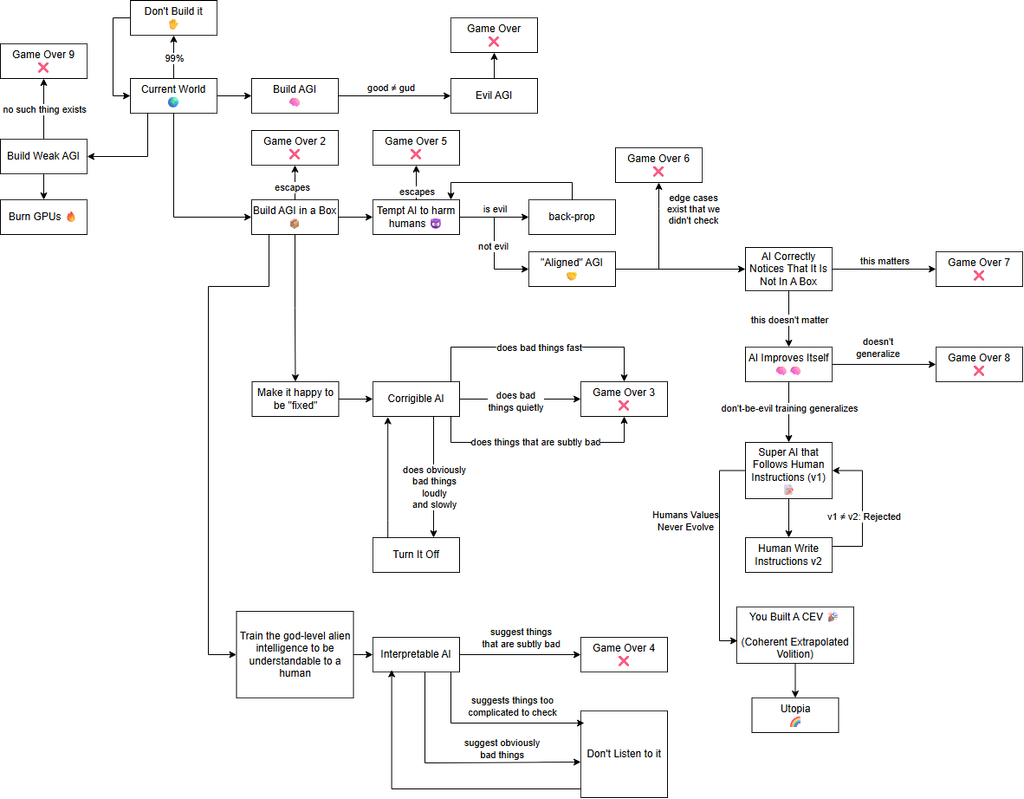
Scott Aaronson teaches new UT Austin course on AI alignment theory
CS395T AI Alignment Theory focuses on theoretical and mathematical foundations rather than empirical work, with student presentations, reports, and projects central to the course. Aaronson notes the field's theoretical foundations have not gelled into a canonical body of results.
Shtetl-Optimized·1 hour ago
Commentary: agent differentiation comes from company context, not models
Vaibhav Sisinty·1 hour ago
Bloomberg Intelligence: US AI lead over China narrows to record low
Bloomberg Intelligence says American AI companies' performance lead over China shrank sharply in recent months to a record low, with labs such as DeepSeek gaining ground. BI frames the narrowing as a threat to US tech supremacy.
Bloomberg Technology·2 hours ago
AWS's Strands SDK demo shows agents writing their own tools at runtime
Sandhya Subramani, AWS senior developer advocate for GenAI, demos meta-tooling with the open-source Strands Agents SDK: an agent starts with zero tools, and when asked for something it can't do, writes the tool and uses it without restarting.
YouTube·2 hours ago
Google DeepMind highlights AI impact on scientific and medical research
Demis Hassabis·2 hours ago