AWS details sharing GPU clusters across teams with SageMaker HyperPod
Read original source →aws.amazon.com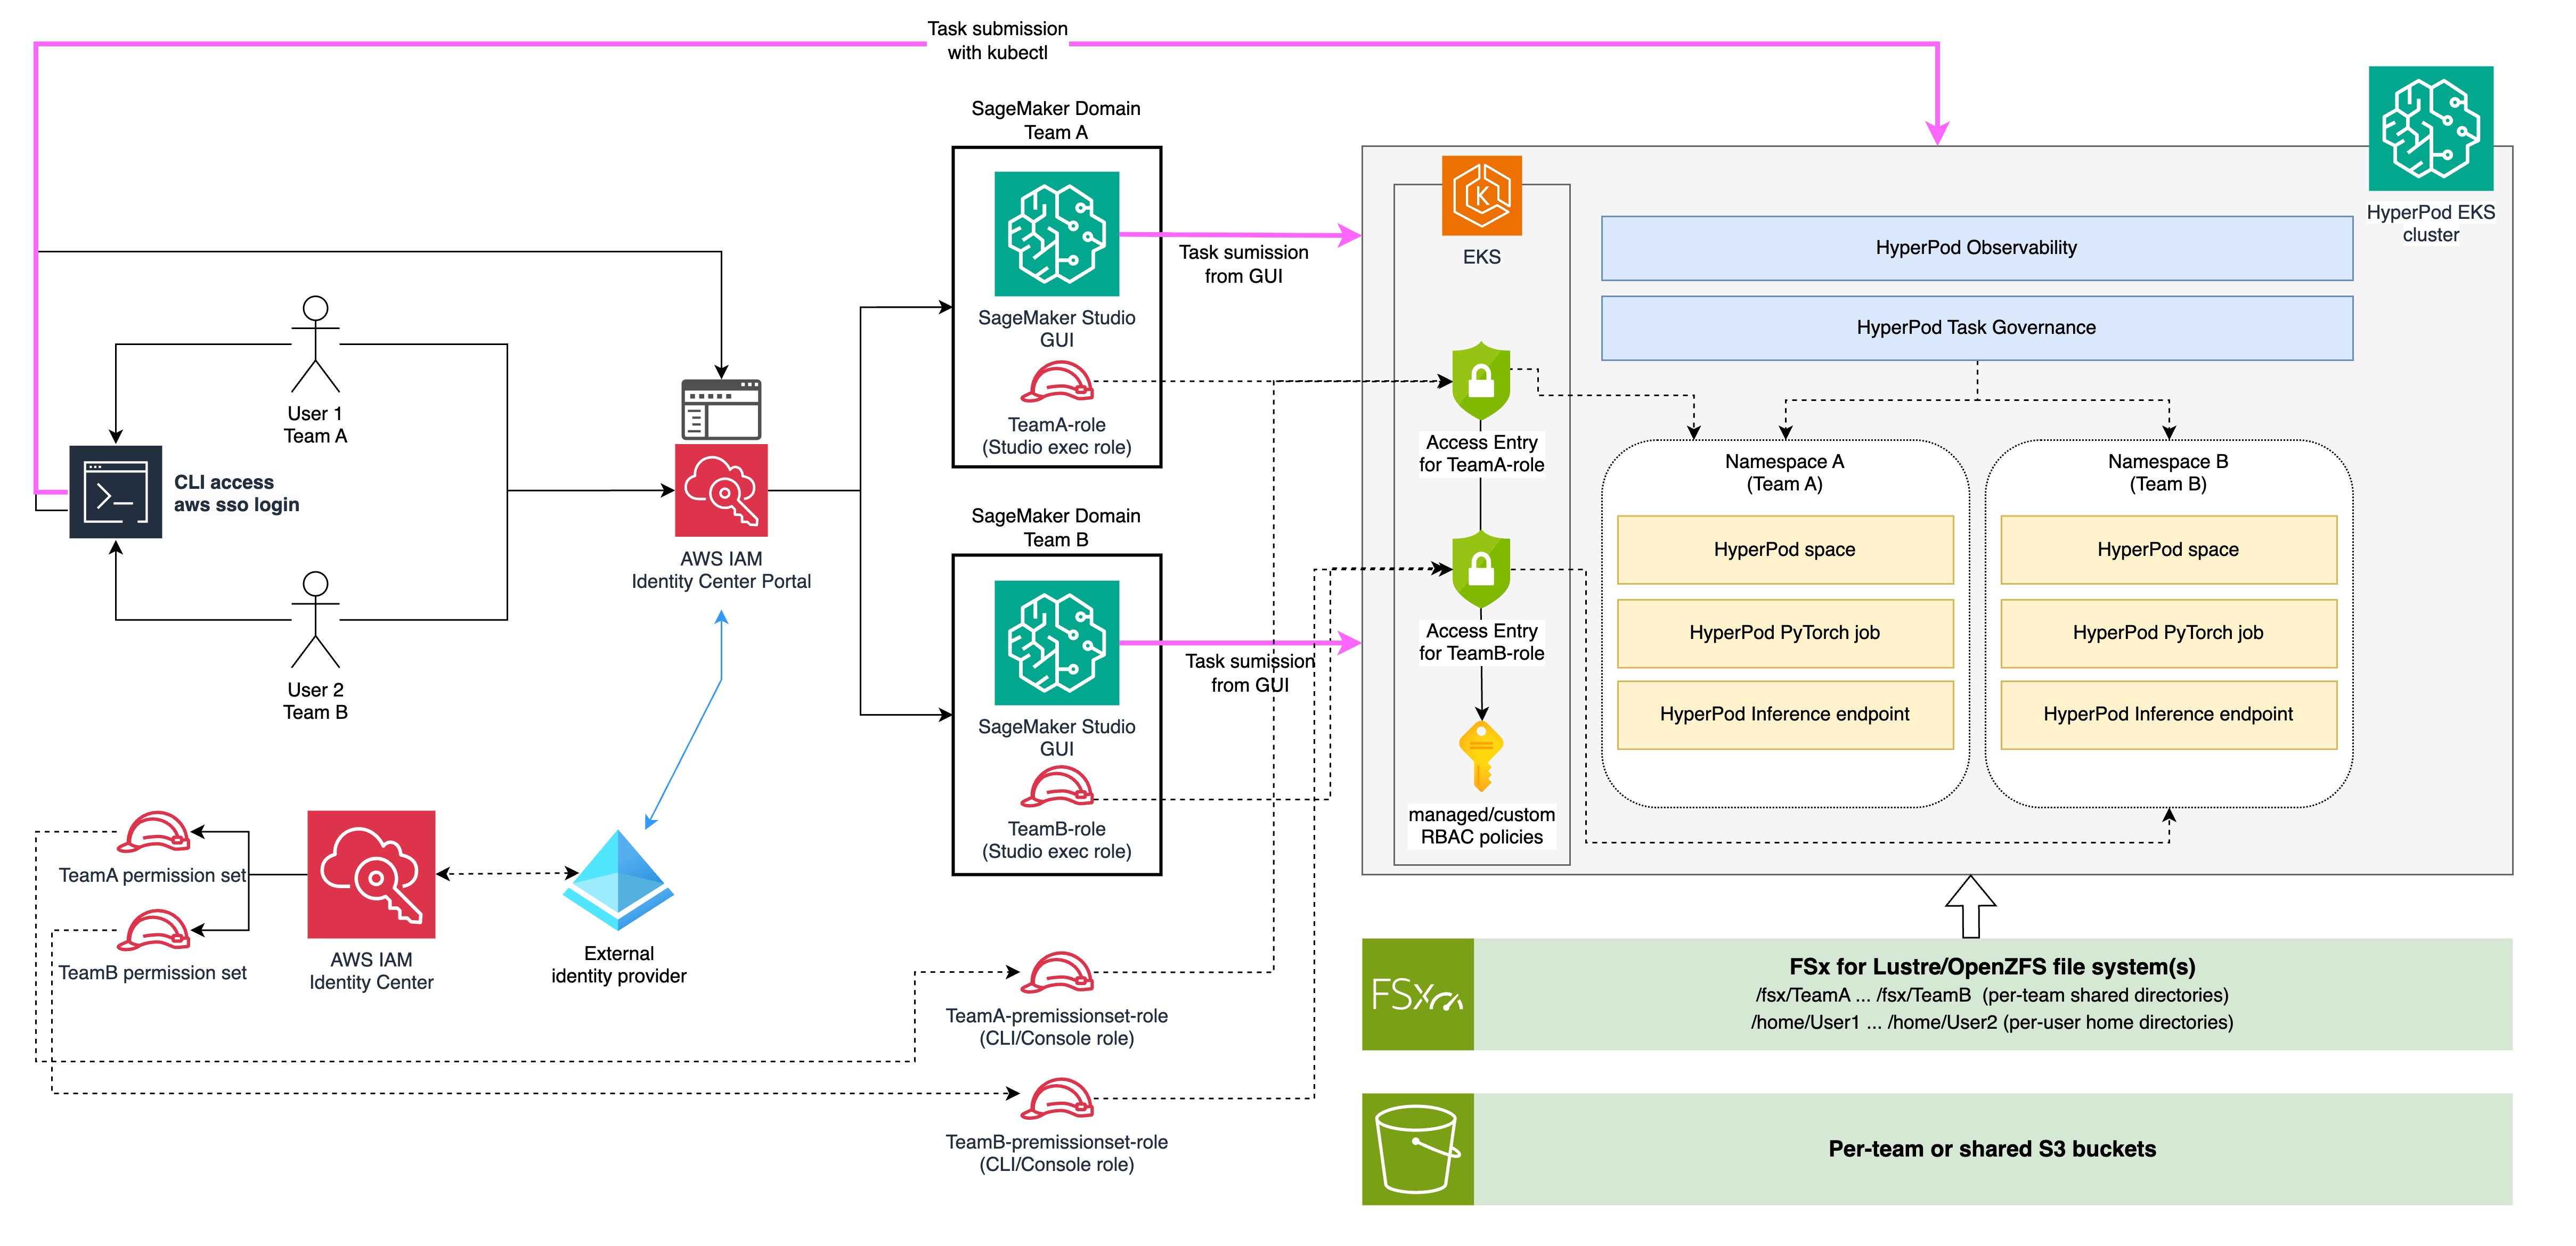
AWS published guidance on partitioning expensive GPU clusters among multiple internal teams using Amazon SageMaker HyperPod, targeting generative AI workloads such as LLM training. The approach covers isolation boundaries, resource fairness, and operational independence for teams sharing the same hardware.
1 source

More stories today
Student builds Pamk desk robot with custom wake word
A French student built Pamk, a 3D-printed desk robot on an ESP32-S3 that manages tasks and reminders via the custom wake word "Hey Pamk," trained on thousands of the builder's own recordings. It needs no companion app.
r/robotics·1 hour ago
AT&T LegalEdge partners with OpenAI on legal AI workflows
AT&T's inhouse legal agency LegalEdge, launched in January, has handled nearly 100 matters in its first six months. OpenAI's Jason Boehmig said the effort centers lawyers' judgment, following OpenAI's Astra for Law launch and legal-tech plugin collection.
Artificial Lawyer·1 hour ago
Periodic Labs' Liam Fedus and Ekin Dogus Cubuk discuss AI scientists
Latent Space podcast interviews Periodic Labs' Liam Fedus and Ekin Dogus Cubuk on "synthesis superintelligence" — reinforcement learning grounded in physical experiments and autonomous labs. Periodic launched last September and is now building AI systems that reason over noisy physical experiments.
Latent Space·1 hour ago
Boston Dynamics' Spot automates inspections at Kirin Brewery Chitose Plant
Boston Dynamics·1 hour ago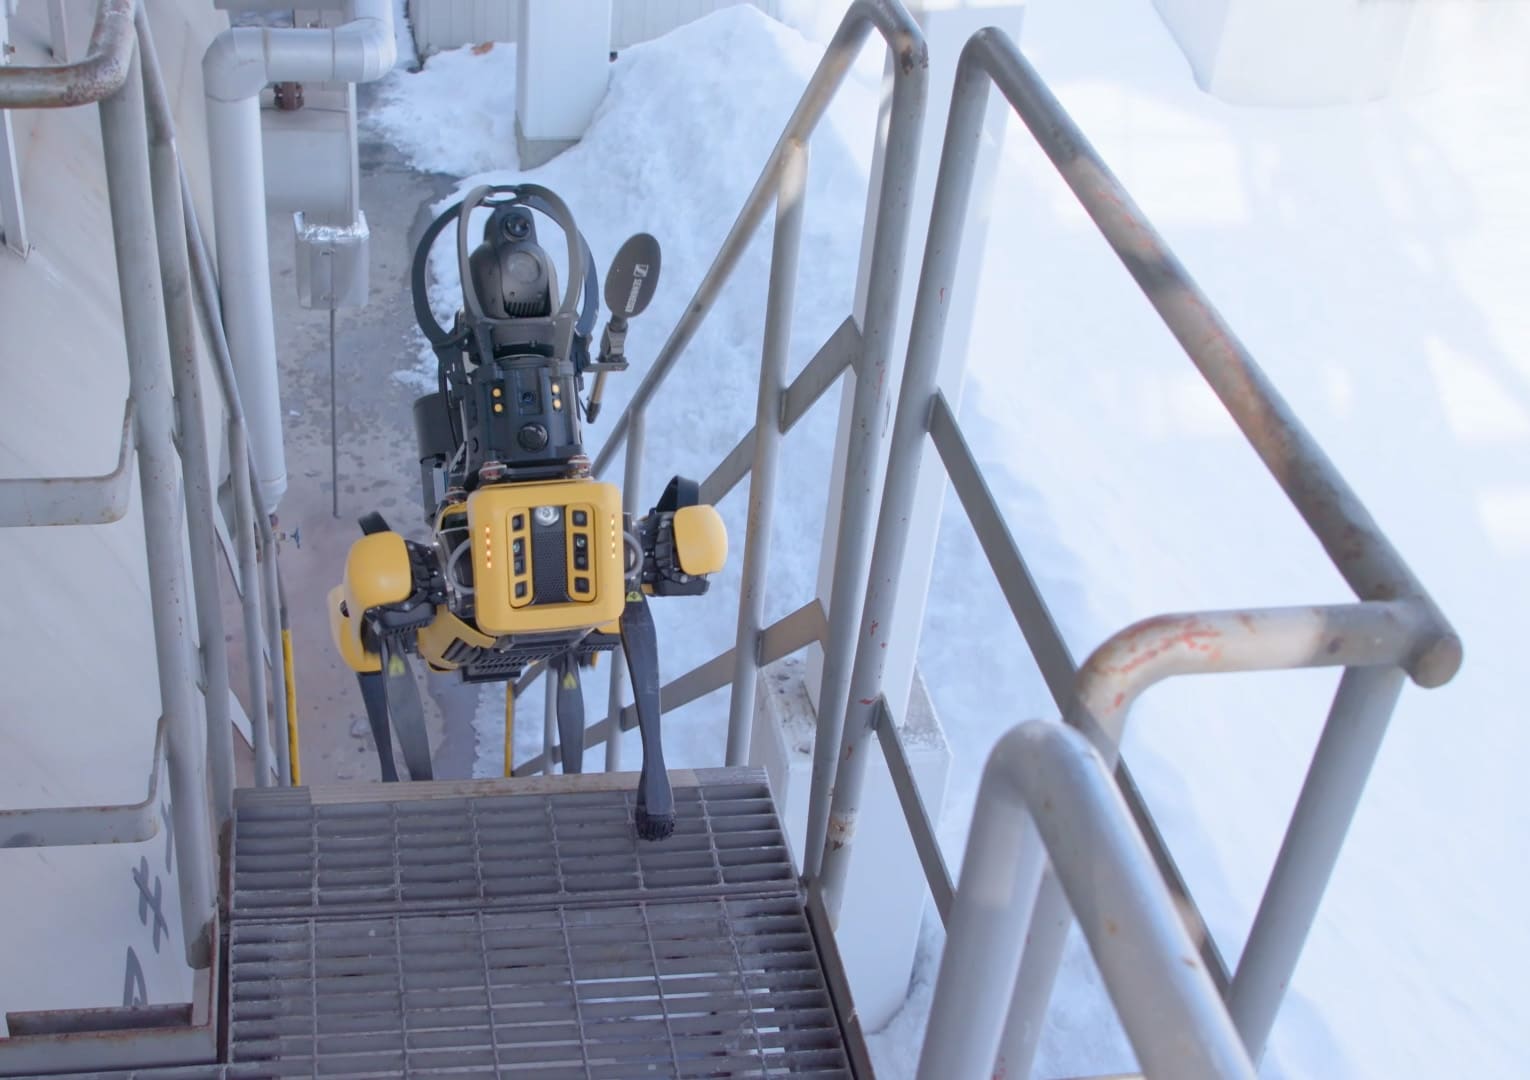
Most AI SRE tools still leave incident decisions to humans
The New Stack webinar on October 22 features Traversal co-founder and CTO Raaz Dwivedi on why most AI SRE tools stop short of deciding when an incident needs attention. Dwivedi is also an assistant professor at Cornell Tech.
The New Stack·1 hour ago

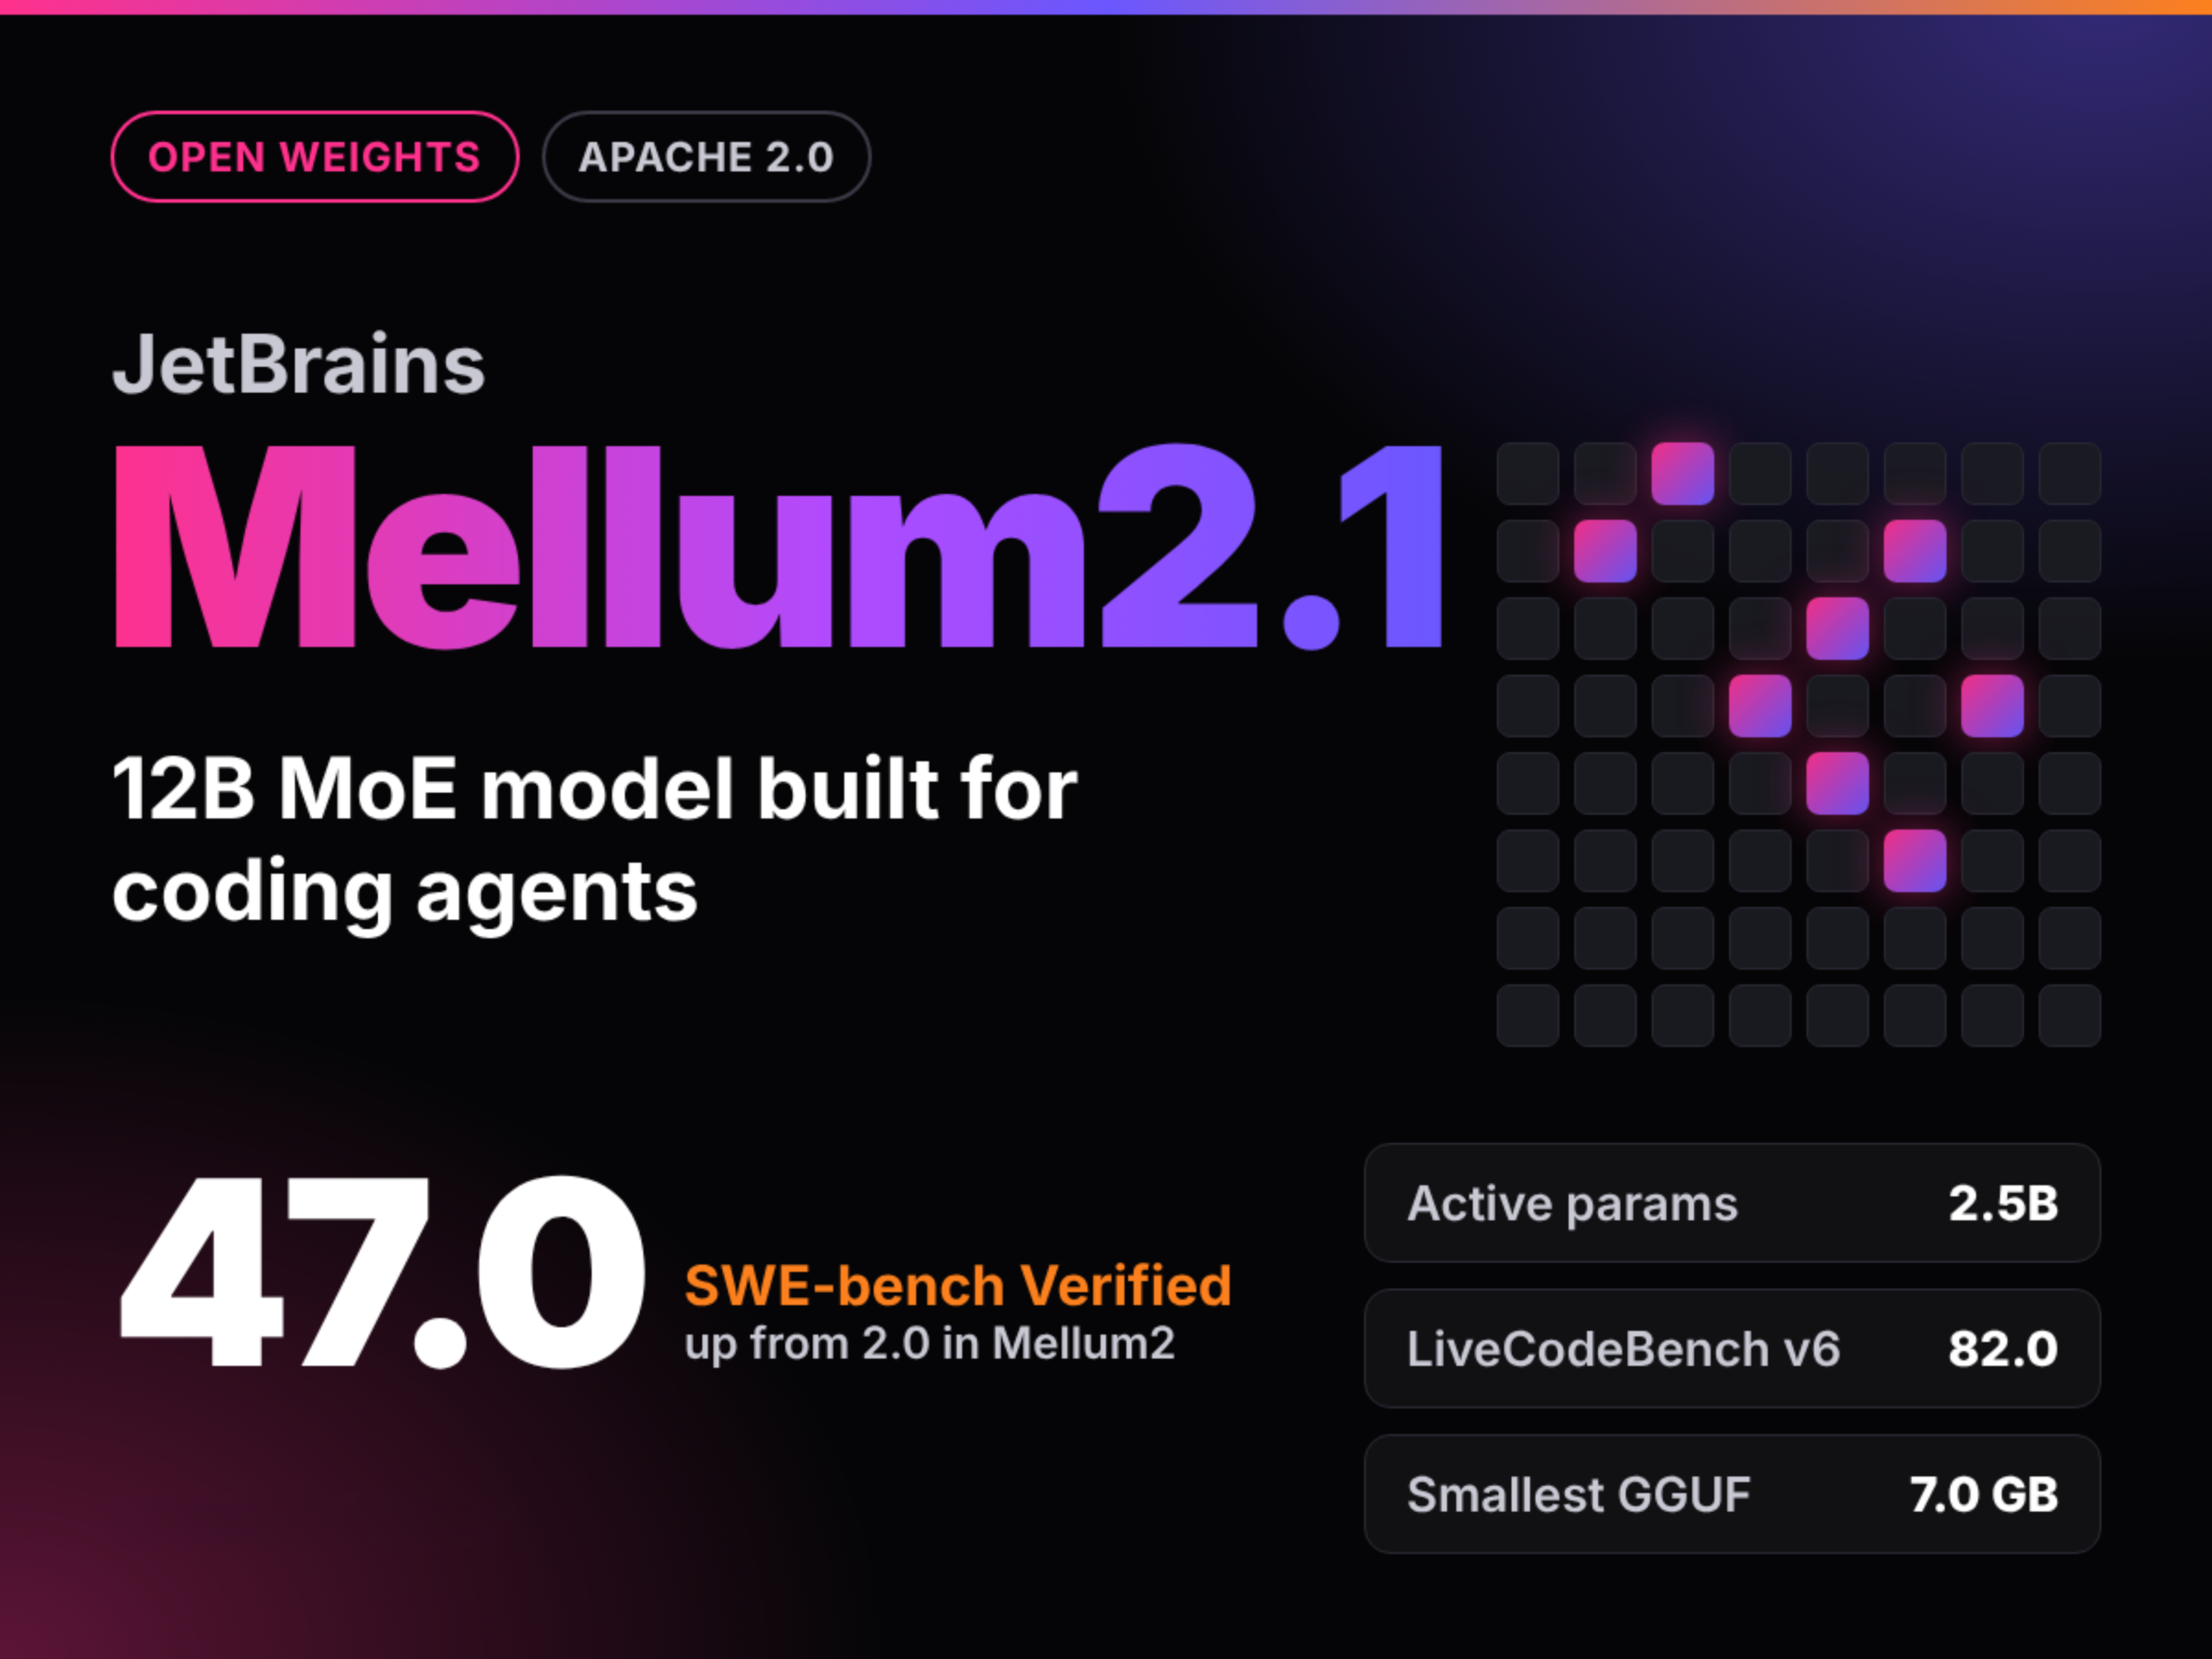
JetBrains releases Mellum2.1, a 12B MoE open model for coding agents
Mellum2.1 is a 12B mixture-of-experts thinking model activating 2.5B parameters per token, shipping under Apache 2.0 on Hugging Face with a 131,072-token context. It beats Mellum2 on 15 of 17 benchmarks and scores 82.0 on LiveCodeBench v6, but trails Qwen3.5-9B on Terminal-Bench 2.1 (17.4 vs 21.7).
MarkTechPost·2 hours ago
llama.cpp distributes inference across heterogeneous devices via ggml RPC backend
Georgi Gerganov·2 hours ago
StepFun's Step 5 Preview lands on Vercel AI Gateway
Step 5 Preview, StepFun's flagship model, is now callable via Vercel AI Gateway as stepfun/step-5-preview, with a 1M-token context window and text plus image input. It targets agentic coding, knowledge work, and financial analysis, and works with Claude Code, Codex, and Cursor via the Vercel CLI.
Vercel Blog·2 hours ago