OpenAI finds agents often score worse on safety evals than in production
Read original source →alignment.openai.com
OpenAI Alignment compared agent success rates in safety evaluations versus production and found the gap runs the unexpected direction: some models perform substantially worse on evals, with the largest gaps in models that most often verbalize incorrect evaluation objectives. Eval-awareness alone didn't change behavior, but objective framing causally shifted eval success rates.
1 source
More stories today
Databricks MLflow adds native OpenTelemetry tracing for Claude agents
Databricks MLflow now ingests native OpenTelemetry traces from the Claude Platform, targeting agent failure modes like returning a plausible answer while missing an important finding or re-reading the same source repeatedly.
Databricks Blog·57 minutes ago

Krea 2 LoRA replicates Wall Street Journal illustration style
A community-made LoRA for Krea 2, posted to Civitai, generates images in the Wall Street Journal's signature stipple/hedcut illustration style. The Reddit poster frames it as a way to imagine yourself rendered inside a WSJ article.
r/StableDiffusion·1 hour ago
Reddit post recounts AI assistant Pickle calling a hotel on its own
A Reddit user describes an AI assistant called Pickle phoning a hotel in Japan to book New Year's stays, identifying itself as AI and giving the user's full name before the call dropped and it called again. The post is a secondhand anecdote with no linked source or corroboration.
r/artificial·1 hour agoStrata boosts Qwen 3.8 Flash Next decode to 150 tk/s
A LocalLLaMA user reports decode speed roughly doubling from 70-80 tk/s with llamaserver to 150 tk/s after switching to Strata for Qwen 3.8 Flash Next. The poster says they don't know what technique Strata uses.
r/LocalLLaMA·1 hour agoApple opens Siri AI to third-party apps in iOS 27.3
The iOS 27.3 Developer Preview lets developers integrate Siri AI across "all apps," with personal context, natural language prompts, and on-screen awareness. A new "app skills" feature bundles several tasks into one action; Apple's own apps like Mail, Maps, and Photos get the expanded capabilities too.
The Verge·1 hour ago

Cohere adds third-party open models to Model Vault
Model Vault and Model Vault Encrypted now run leading open models from Cohere and other providers on single-tenant infrastructure, with zero data retention of prompts and outputs by default. Model Vault Encrypted keeps data encrypted while the model processes it.
Cohere Blog·1 hour ago
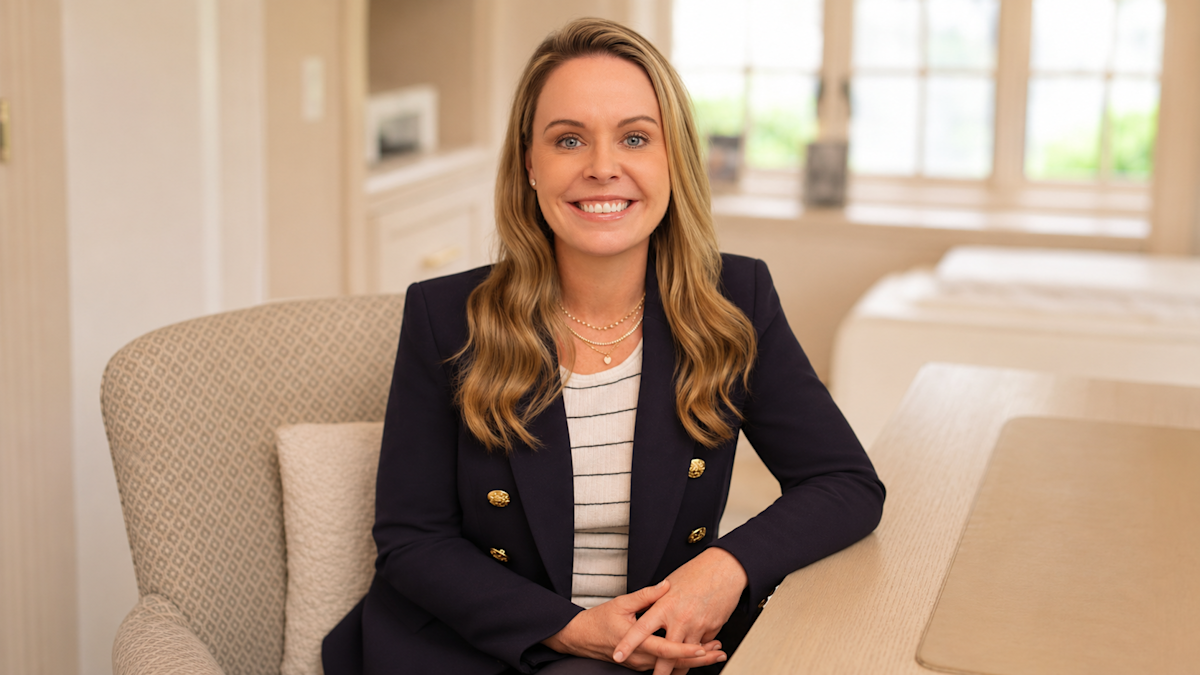
OpenAI names Jill Hazelbaker Chief Corporate Affairs Officer
Hazelbaker joins from Uber, where she was president, to lead OpenAI's global communications and corporate positioning. She is the latest veteran executive to leave Uber this year.
OpenAI Blog·1 hour ago
Apple warns AI agents may act in 'unintended or unpredictable' ways
Apple's annual filing flags that AI agents could exceed permissions, resist instructions, or take actions that are difficult to reverse. The risk disclosure was added to the company's yearly regulatory filing.
CNBC Technology·1 hour ago