OpenBMB runs 35B MoE at 20.5 tok/s on iPhone without skipping experts
Read original source →reddit.com
OpenBMB's engineering write-up targets the real bottleneck — moving expert weights from flash storage to compute fast enough — rather than shrinking the model or dropping experts. The result is a 35B MoE model running at 20.5 tokens/sec on an iPhone.
1 source
More stories today
Reddit post revisits Microsoft's faked 2009 Project Milo demo
The r/Singularity post recalls Microsoft's Project Milo, a Kinect-era virtual character demo that was never released and was exposed as mostly faked. The poster argues the conversational, drawing-aware interaction it staged is now mundane.
r/Singularity·1 hour ago
Physicist Christopher Stubbs joins Anthropic's Long-Term Benefit Trust
Stubbs, Harvard's Samuel C. Moncher Professor of Physics and Astronomy and Dean of Science from 2018 to 2024, helped discover the universe's accelerating expansion with the High-Z Supernova Search Team in 1998. He was also inaugural project scientist for what is now the Vera C. Rubin Observatory and is a member of JASON.
Anthropic News·1 hour ago

Deel launches Pangaea AI models for HR and payroll
Deel released a family of domain-specific models aimed at HR and payroll work, betting specialists can cut the cost of answers versus general-purpose models. No pricing or benchmark figures were disclosed in the announcement coverage.
VentureBeat·1 hour ago
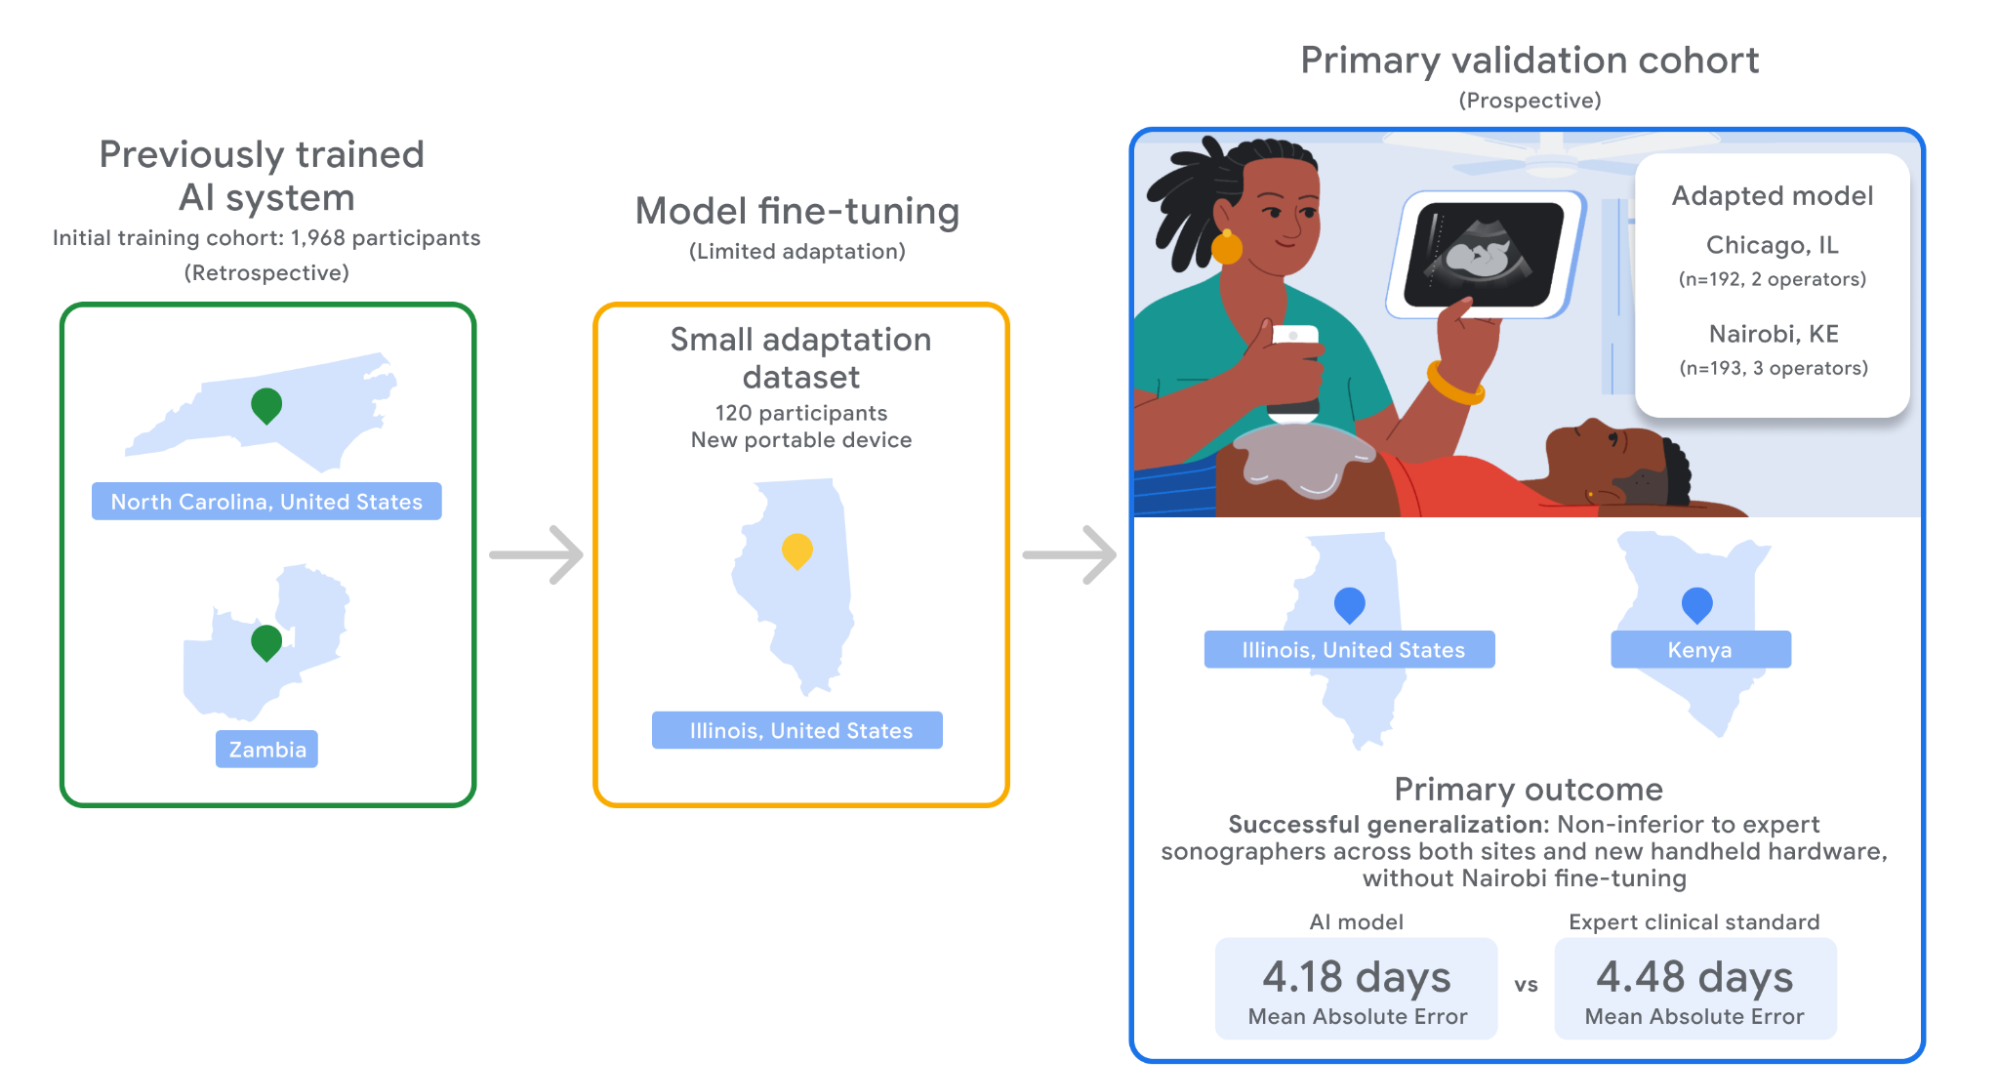
Google AI reads blind-sweep ultrasounds to estimate gestational age
A prospective multi-center study found non-sonographer operators using low-cost probes plus AI blind-sweep interpretation matched trained sonographers on gestational age and fetal presentation. WHO estimates 250,000+ preventable pregnancy-related deaths yearly, and two-thirds of people lack access to diagnostic imaging.
Google Research Blog·2 hours ago
Sydney man arrested after telling Claude of mass shooting plans
David Lan Thackray, 29, was remanded in custody after his Claude conversation was flagged to Interpol and his account suspended. He allegedly said he would "shoot up the local daycare"; his lawyer said the tirade followed a failed attempt to get help for an ear infection.
r/ClaudeAI·2 hours ago
Cohere releases Rerank 5 with passage-level Context Focus
Rerank 5 ships in Pro and Fast tiers, priced at $0.05 and $0.02 per 1M tokens on the Cohere API. Rerank 5 Pro ranked first on 39 of 46 composite datasets and scored 82.2 on BRIGHT, beating Voyage AI Rerank 3 by 5.8 points.
Cohere Blog·2 hours ago

AWS releases TorchNeuron to run PyTorch models on Trainium
TorchNeuron lets PyTorch apps run on Amazon's Trainium chips by changing one line of configuration, no code rewrite required. AWS says ~85% of AI apps are written with PyTorch, the toolkit Nvidia's CUDA has long been embedded in by default.
Hugging Face Blog·2 hours ago
Hugging Face and Pollen Robotics unveil Microduck robot at Nvidia's GTC Berlin
Clem Delangue·2 hours ago