Qwen3.8-Flash-Next runs on 64GB Macs via SSD expert offload
Read original source →reddit.com
A 95.5 GiB Qwen3.8-Flash-Next checkpoint runs on a 64GB Mac at ~27 tok/s by keeping routed experts on SSD and reading them only when a token routes there. A separate user manually quantized the model to OQ4E with oMLX, landing at roughly 4.72 bits per weight on an M3 Max.
2 sources
More stories today
Quanta traces the 2014 attention breakthrough behind modern AI
Quanta profiles Dzmitry Bahdanau, the then-23-year-old intern in Yoshua Bengio's University of Montreal lab who in 2014 helped solve neural machine translation's fixed-memory bottleneck. His attention mechanism, developed with Bengio and postdoc Kyunghyun Cho, underpins everything since ChatGPT's 2022 release.
Quanta Magazine·1 hour ago
Developer builds GTA Toronto game with Codex for Modretro Chromatic
Hai The Dude·1 hour ago
Suno users report copyright flags on original uploads
A Suno user says a track written the same day, backed by FL Studio stems, live guitars and Superior Drummer 3 MIDI, was flagged as copyrighted; stripping drums and second guitar did not clear it.
r/SunoAI·1 hour ago
Atticus: hold-to-talk macOS voice assistant built on Claude
A 9th-grade developer released Atticus, a Mac assistant triggered by holding Control-Option-Space to speak or type a task. It runs on Claude and is described as fast and cheap.
Hacker News·1 hour agoReddit user shares sketch-to-image results with H3 Minimax
A r/StableDiffusion user posted sketch-to-image outputs generated with H3 Minimax, noting composition and head angles matter most. The user observed the model sometimes forces sketch shapes onto subjects with short or thin hair, suggesting looser strokes over clear lines.
r/StableDiffusion·2 hours ago
Reddit user says Claude charged them, then demanded ID
A Reddit user in r/OpenAI reports their credit card was charged for a Claude Pro upgrade, after which Claude requested a photo of their government ID to complete the upgrade. They say their account was blocked after they refused.
r/OpenAI·2 hours ago
ColGrep-Agent-2B runs code search locally, cuts API tokens 34%
Amélie Chatelain·2 hours ago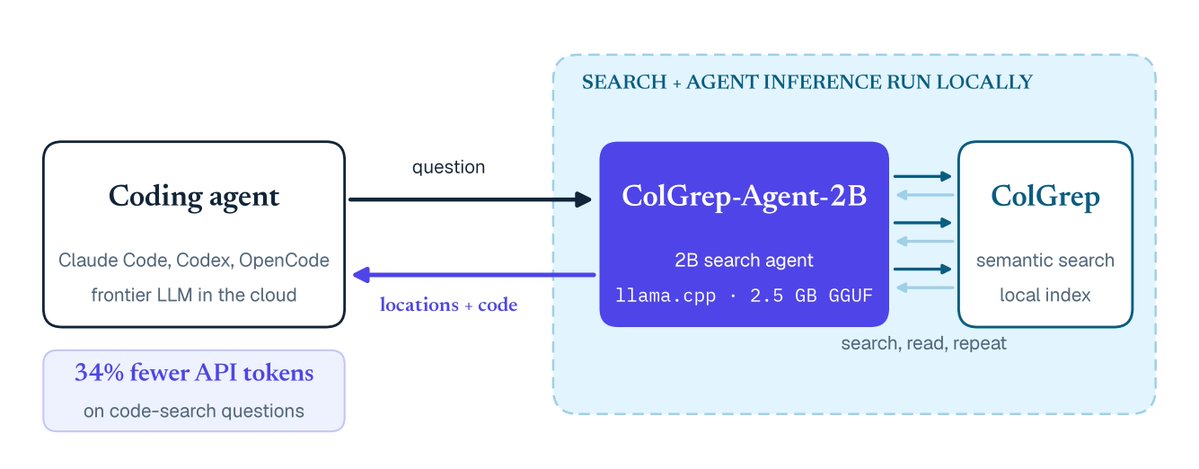
H100 timing side channel leaks neighbor GPU activity
Branislav Brzak of Stealthium demonstrated an H100 timing side channel where three microseconds of extra latency reveals activity on another tenant's GPU slice. The probe reads only the attacker's own memory, requiring no software bug and no access to victim memory.
YouTube·2 hours ago