LangChain's Harrison Chase outlines context engineering challenges for proactive agents
Read original source →langchain.com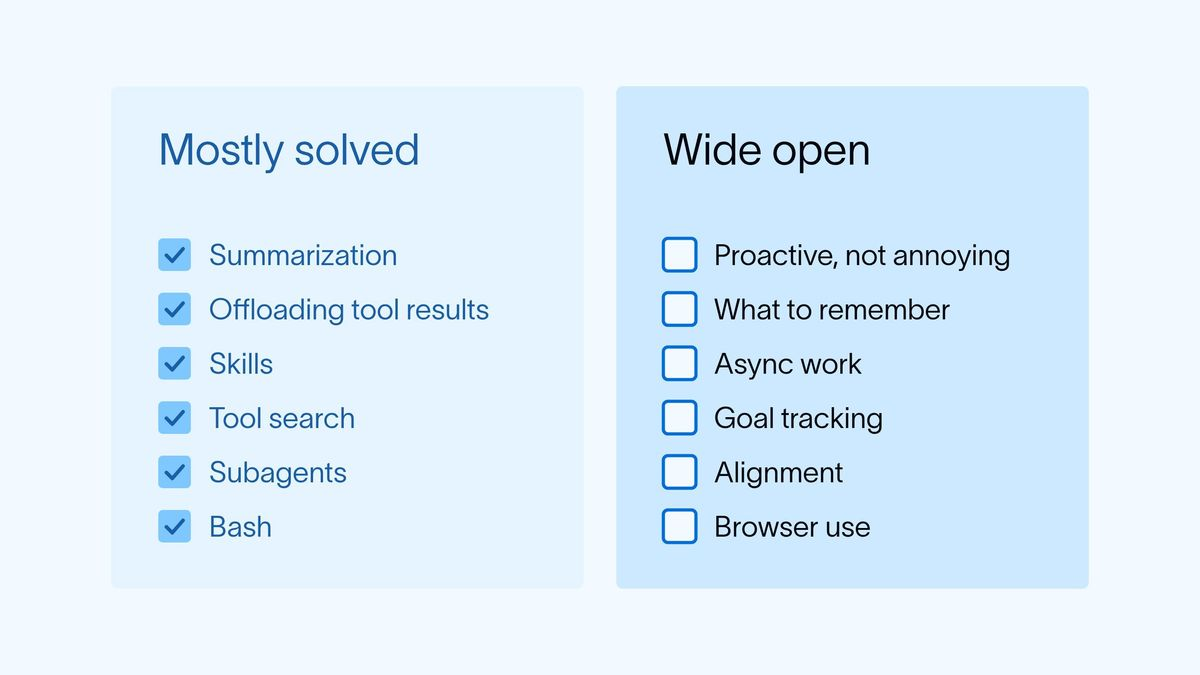
LangChain CEO Harrison Chase argues the convergence on LLM-in-a-loop agent harnesses has bred a false sense that hard problems are solved, and that proactive, always-on agents bring new ones. He lists established fixes — thread summarization, offloading large tool results, skills, tool search, subagents, bash — and says no general solutions exist yet for the new set.
People · Harrison Chase
1 source
More stories today
Robot lip-sync system tested in English, Korean and more
A Reddit post demos Éloi's lip-sync control, designed to work across multiple languages, with testing so far in English, Korean and at least one more. No benchmark numbers or release details were shared.
r/robotics·1 hour ago
Clown Prophecy ComfyUI nodes chain MiniMax H3 clips without quality loss
Clown Context Suite adds ComfyUI nodes for chaining MiniMax H3 clips, addressing the detail loss that compounds when each clip starts from the previous clip's tail — by clip 10 output looks soft and washed out. The project has moved to a new repo, Clown-Prophecy-Experimental, with a revised technique.
r/StableDiffusion·1 hour ago
Qodo brings company coding standards into Codex code review
Qodo's Codex plugin feeds company knowledge and coding standards into reviews so developers catch P0 issues across repositories before opening a pull request. OpenAI also published a walkthrough of reviewing pull requests, feedback, and private code discussions in one place.
OpenAI Blog·1 hour ago
Anthropic adds message threads to Claude Messages API
Message threads, in public beta, let agents send only new messages plus the previous response ID instead of resending full history. With it on by default for most Claude Code users, 500k–1M token requests saw median time-to-first-token drop about 35%.
Claude Blog·1 hour ago
Prime Intellect's Will Brown argues companies should train their own AI models
In an AI Engineer talk, Prime Intellect's Will Brown argues agents relearn the same things every session because company knowledge never gets written down. He makes the case for training models on a firm's own traces, feedback and workflows so they learn on the job like human coworkers.
YouTube·1 hour ago
Narayanan: recursive self-improvement may mean labs' self-extinction
Arvind Narayanan·1 hour agoReddit user builds Mongol invasion of Vietnam game with Claude
A Reddit user with little prior experience used Claude to turn a hobby project about the Mongol invasions of Vietnam into a playable game, citing the lack of Vietnamese representation in games beyond Age of Empires II.
r/ClaudeAI·1 hour ago
Anthropic Residency research program opens applications
Anthropic·1 hour ago
