Three papers probe on-policy distillation for LLM reasoning
Read original source →arxiv.orgSparse crosscoders are used to inspect what on-policy distillation actually writes into a student's internal representations. Direct-OPD work argues only some tokens deserve supervision; LastOPD targets collapse in latent-state alignment.
How this story unfolded
3 days · 14 reports · from Sep 28
- Sep 28
- Sep 29
- Sep 30
Understanding On-Policy Distillation: A Mechanistic Interpretability Perspective via Sparse Crosscodersarxiv.org
- Oct 1
More stories today
GPT-6 Astra Ultrafast runs on NVIDIA Blackwell GPUs
GPT-6 Astra Ultrafast is available now in the OpenAI API and to eligible ChatGPT Work and Codex users, offering up to 8x faster token generation than Astra Standard mode. OpenAI's Philippe Tillet credits NVIDIA tooling for making the models good at programming Blackwell and Rubin GPUs.
blogs.nvidia.com·2 hours ago
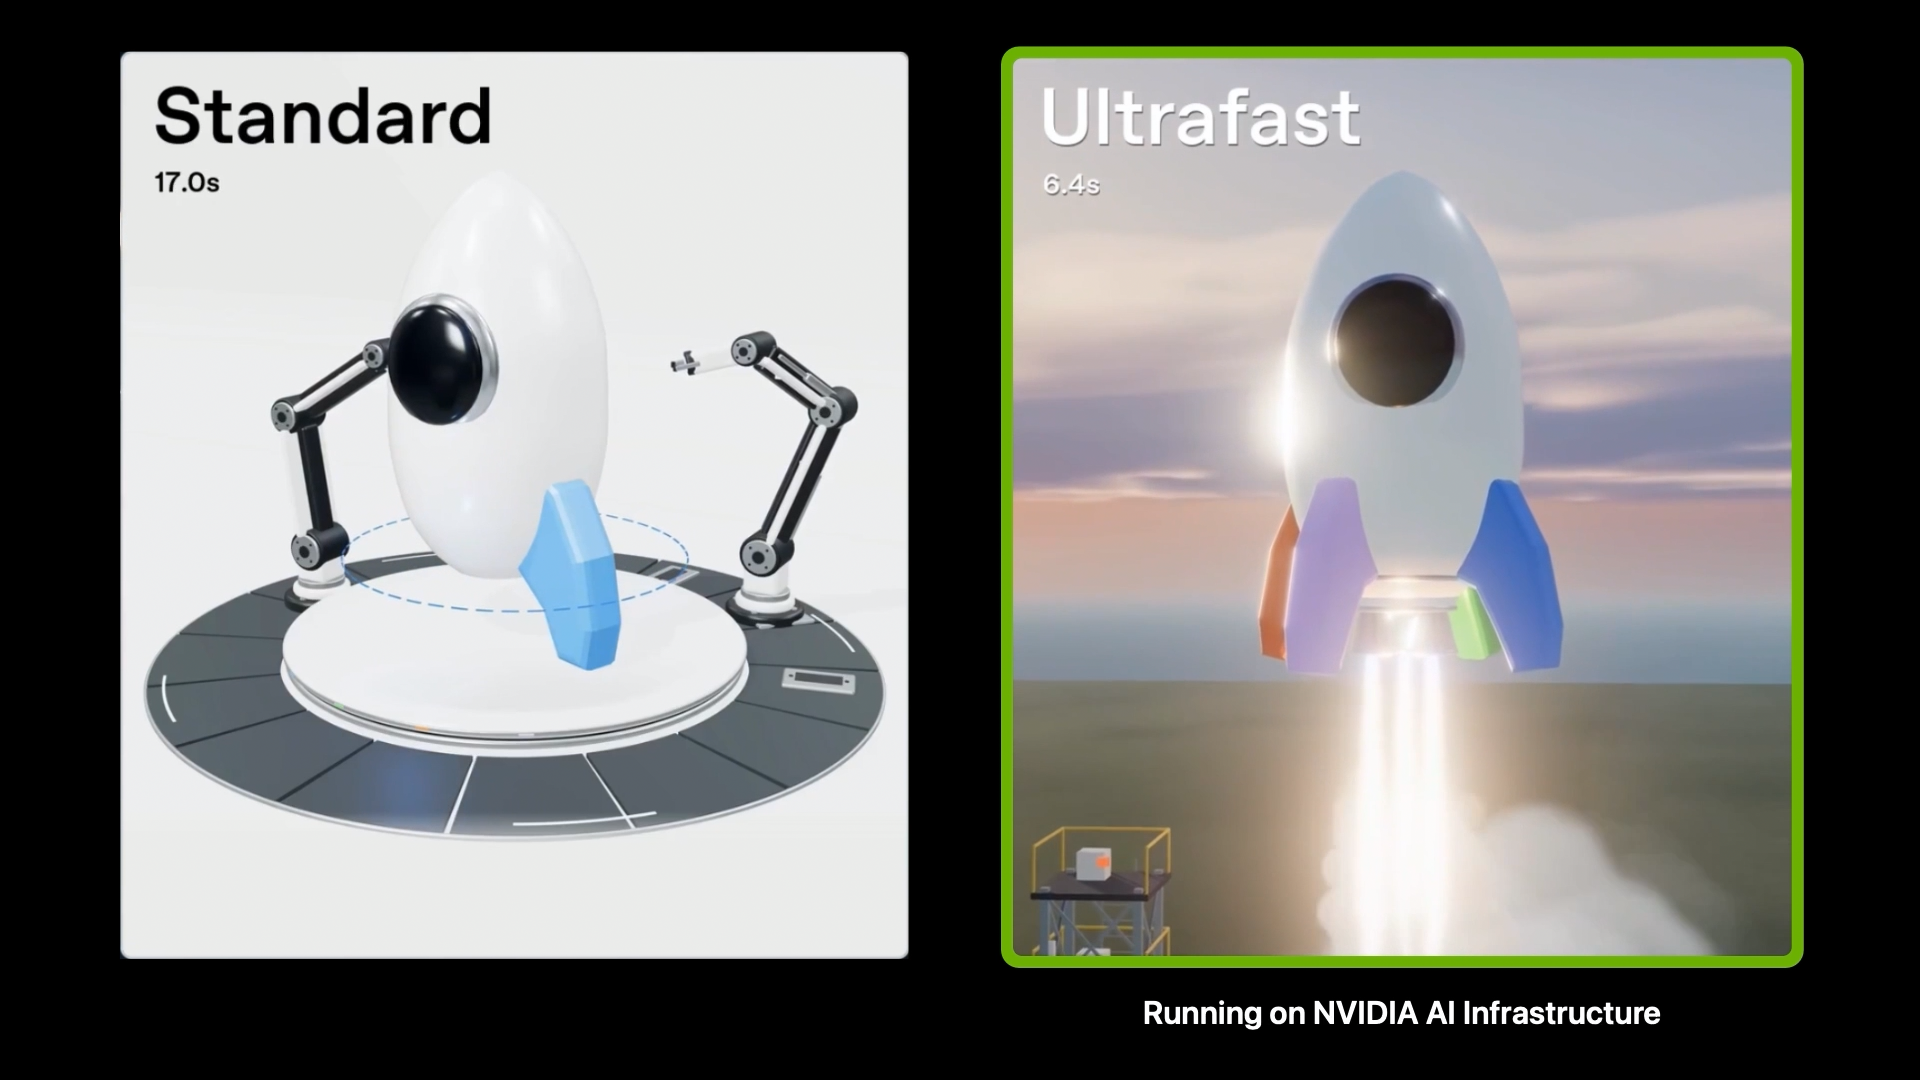
OpenAI's GPT-6 Astra Ultrafast runs on NVIDIA Blackwell GPUs
GPT-6 Astra Ultrafast is available now in the OpenAI API and to eligible ChatGPT Work and Codex users, offering up to 8x faster token generation than Astra Standard mode. OpenAI used its own models to optimize inference on NVIDIA GPUs.
Reddit user compares renting GPUs vs owning a 5090 for ComfyUI video
A ComfyUI user ran the numbers on hours spent generating image-to-video and short videos after switching from rented GPUs to a local RTX 5090. They report their usage habits changed once the hardware was owned, making them more willing to run experimental generations.
r/ComfyUI·2 hours agoSoftBank investors weigh AI bets against rising borrowing costs
SoftBank Group equity investors are looking past higher borrowing costs and credit-risk concerns to focus on potential returns from the company's AI bets, per Bloomberg. The report frames the tension between SoftBank's debt load and its AI upside.
Bloomberg Technology·2 hours ago
Reddit user modernizes 100-year-old family photos with ChatGPT
A Reddit user ran family photographs taken 90–110 years ago through ChatGPT to imagine modern hair, makeup, clothing, and body size, including one case with modern military uniforms and equipment.
r/ChatGPT·3 hours ago
The Den uses ChatGPT Work to cut grant prep from 3 days to 2 hours
The social club's grant applications now take 2 hours instead of 3 days, and liquor-license materials 3 hours instead of 4 days. It reports freeing 10-15 hours a week as it opens a new location.
OpenAI Blog·3 hours ago
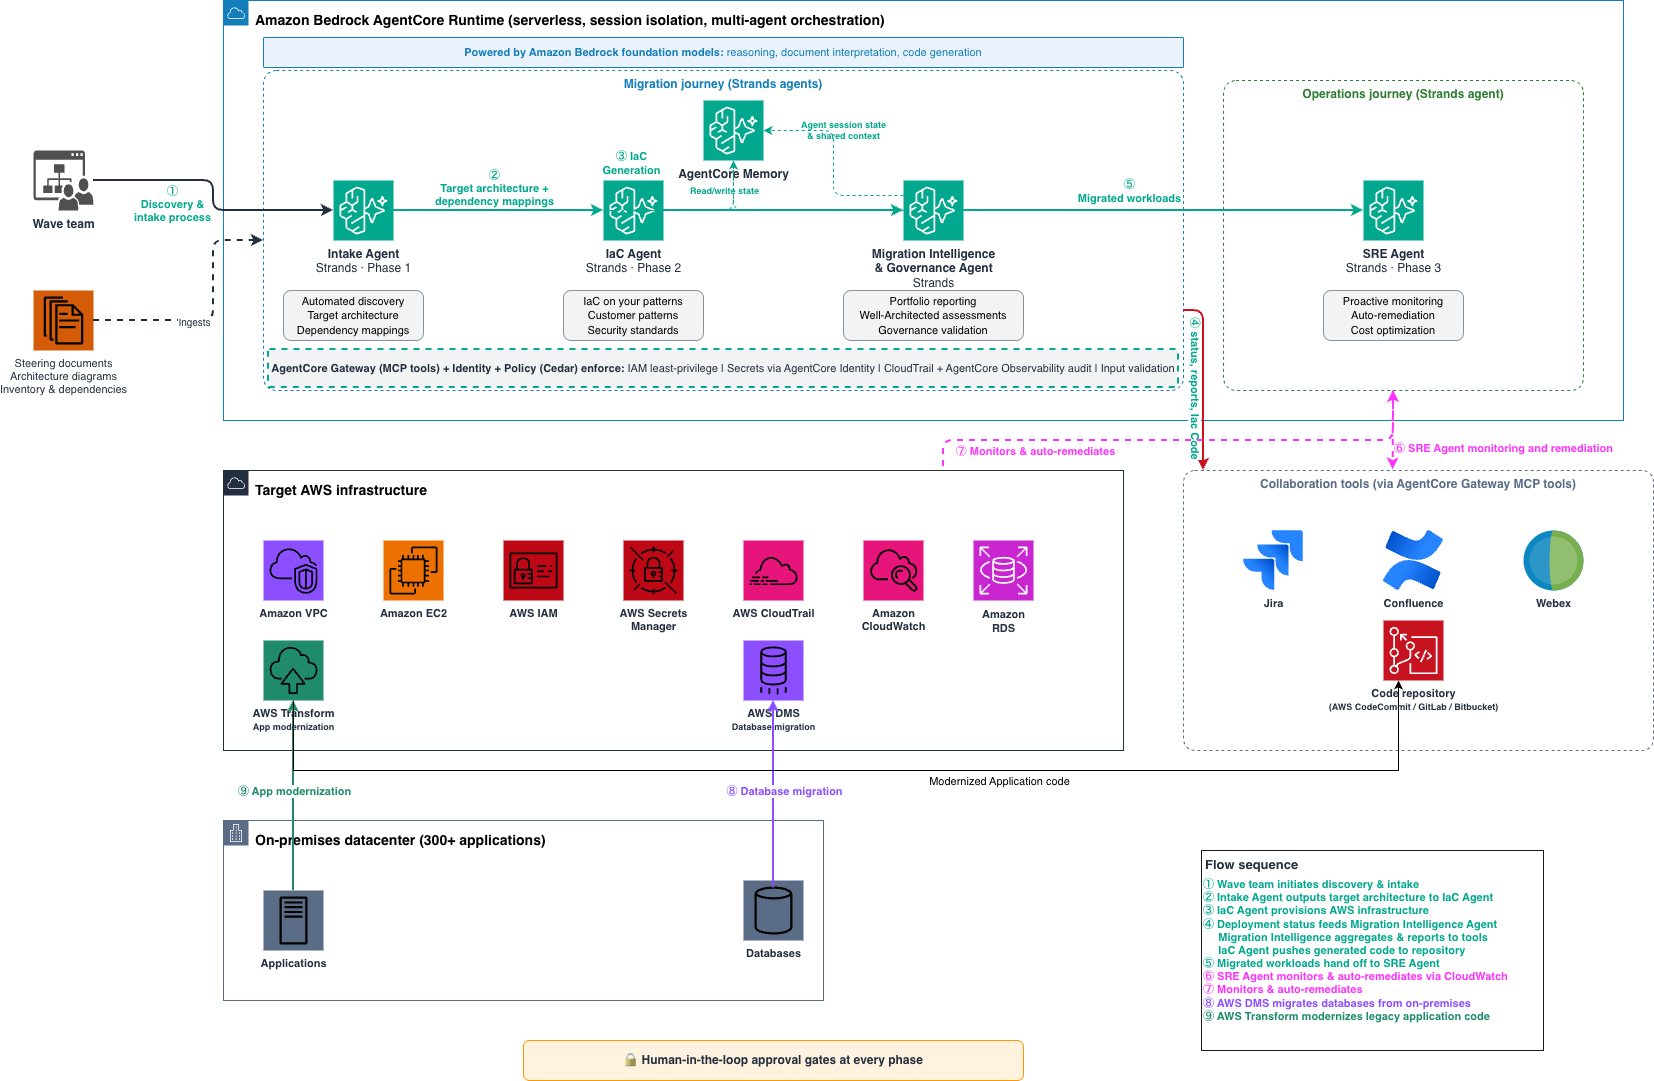
AWS details scaling cloud migrations with agentic AI on Bedrock AgentCore
AWS post weighs which parts of a large migration program belong to a managed service versus custom automation, using one enterprise program as the example. The post was reviewed and updated in October 2026.
AWS AI Blog·4 hours ago
Anima-Lightning fine-tune enables 4-step Anima inference
Anima-Lightning is a community fine-tune of Anima trained specifically for 4-step inference, released publicly on r/StableDiffusion. The creator says the goal is to make Anima significantly faster while preserving image quality and prompt adherence at only 4 steps.
r/StableDiffusion·4 hours ago