Reddit user proposes speculative decoding with 2-bit VRAM draft and exact RAM verifier
Read original source →reddit.com
A r/LocalLLaMA poster describes an unfinished experiment: keep a 2-bit copy of a model in VRAM as the draft and the exact residual in system RAM as the verifier, so models too large for the GPU can still be run. The author says work and family left no time to take it further.
1 source
More stories today
Claude Code 2.1.308 ships bug fixes and reliability improvements
Version 2.1.308 is a maintenance release with only bug fixes and reliability improvements. The prior 2.1.307 build added a /claude-api api-version command and a claude_code.safety_event OpenTelemetry event for tool calls stopped by permission rules, auto mode, hooks or the sandbox.
Claude Code Changelog·3 hours ago
Reddit user warns Railway-hosted Claude API keys are being harvested
A r/ClaudeAI poster says a Claude API key stored in Railway environment variables was stolen and used, costing them $80 before Anthropic shut off auto-reload. The post links Railway's status page and urges others to disable keys used there.
r/ClaudeAI·3 hours ago
Blog post argues LLM-generated confidence scores are untrustworthy
The post argues confidence is a calculation from evidence, not an opinion, so an LLM asked for a probability has no principled basis for the number it returns. It notes many agent designers nonetheless use LLM-generated confidence scores in their pipelines.
Hacker News·3 hours agoGuide benchmarks Cactus Whistle, a 16.9 MB CPU speech model, against Whisper
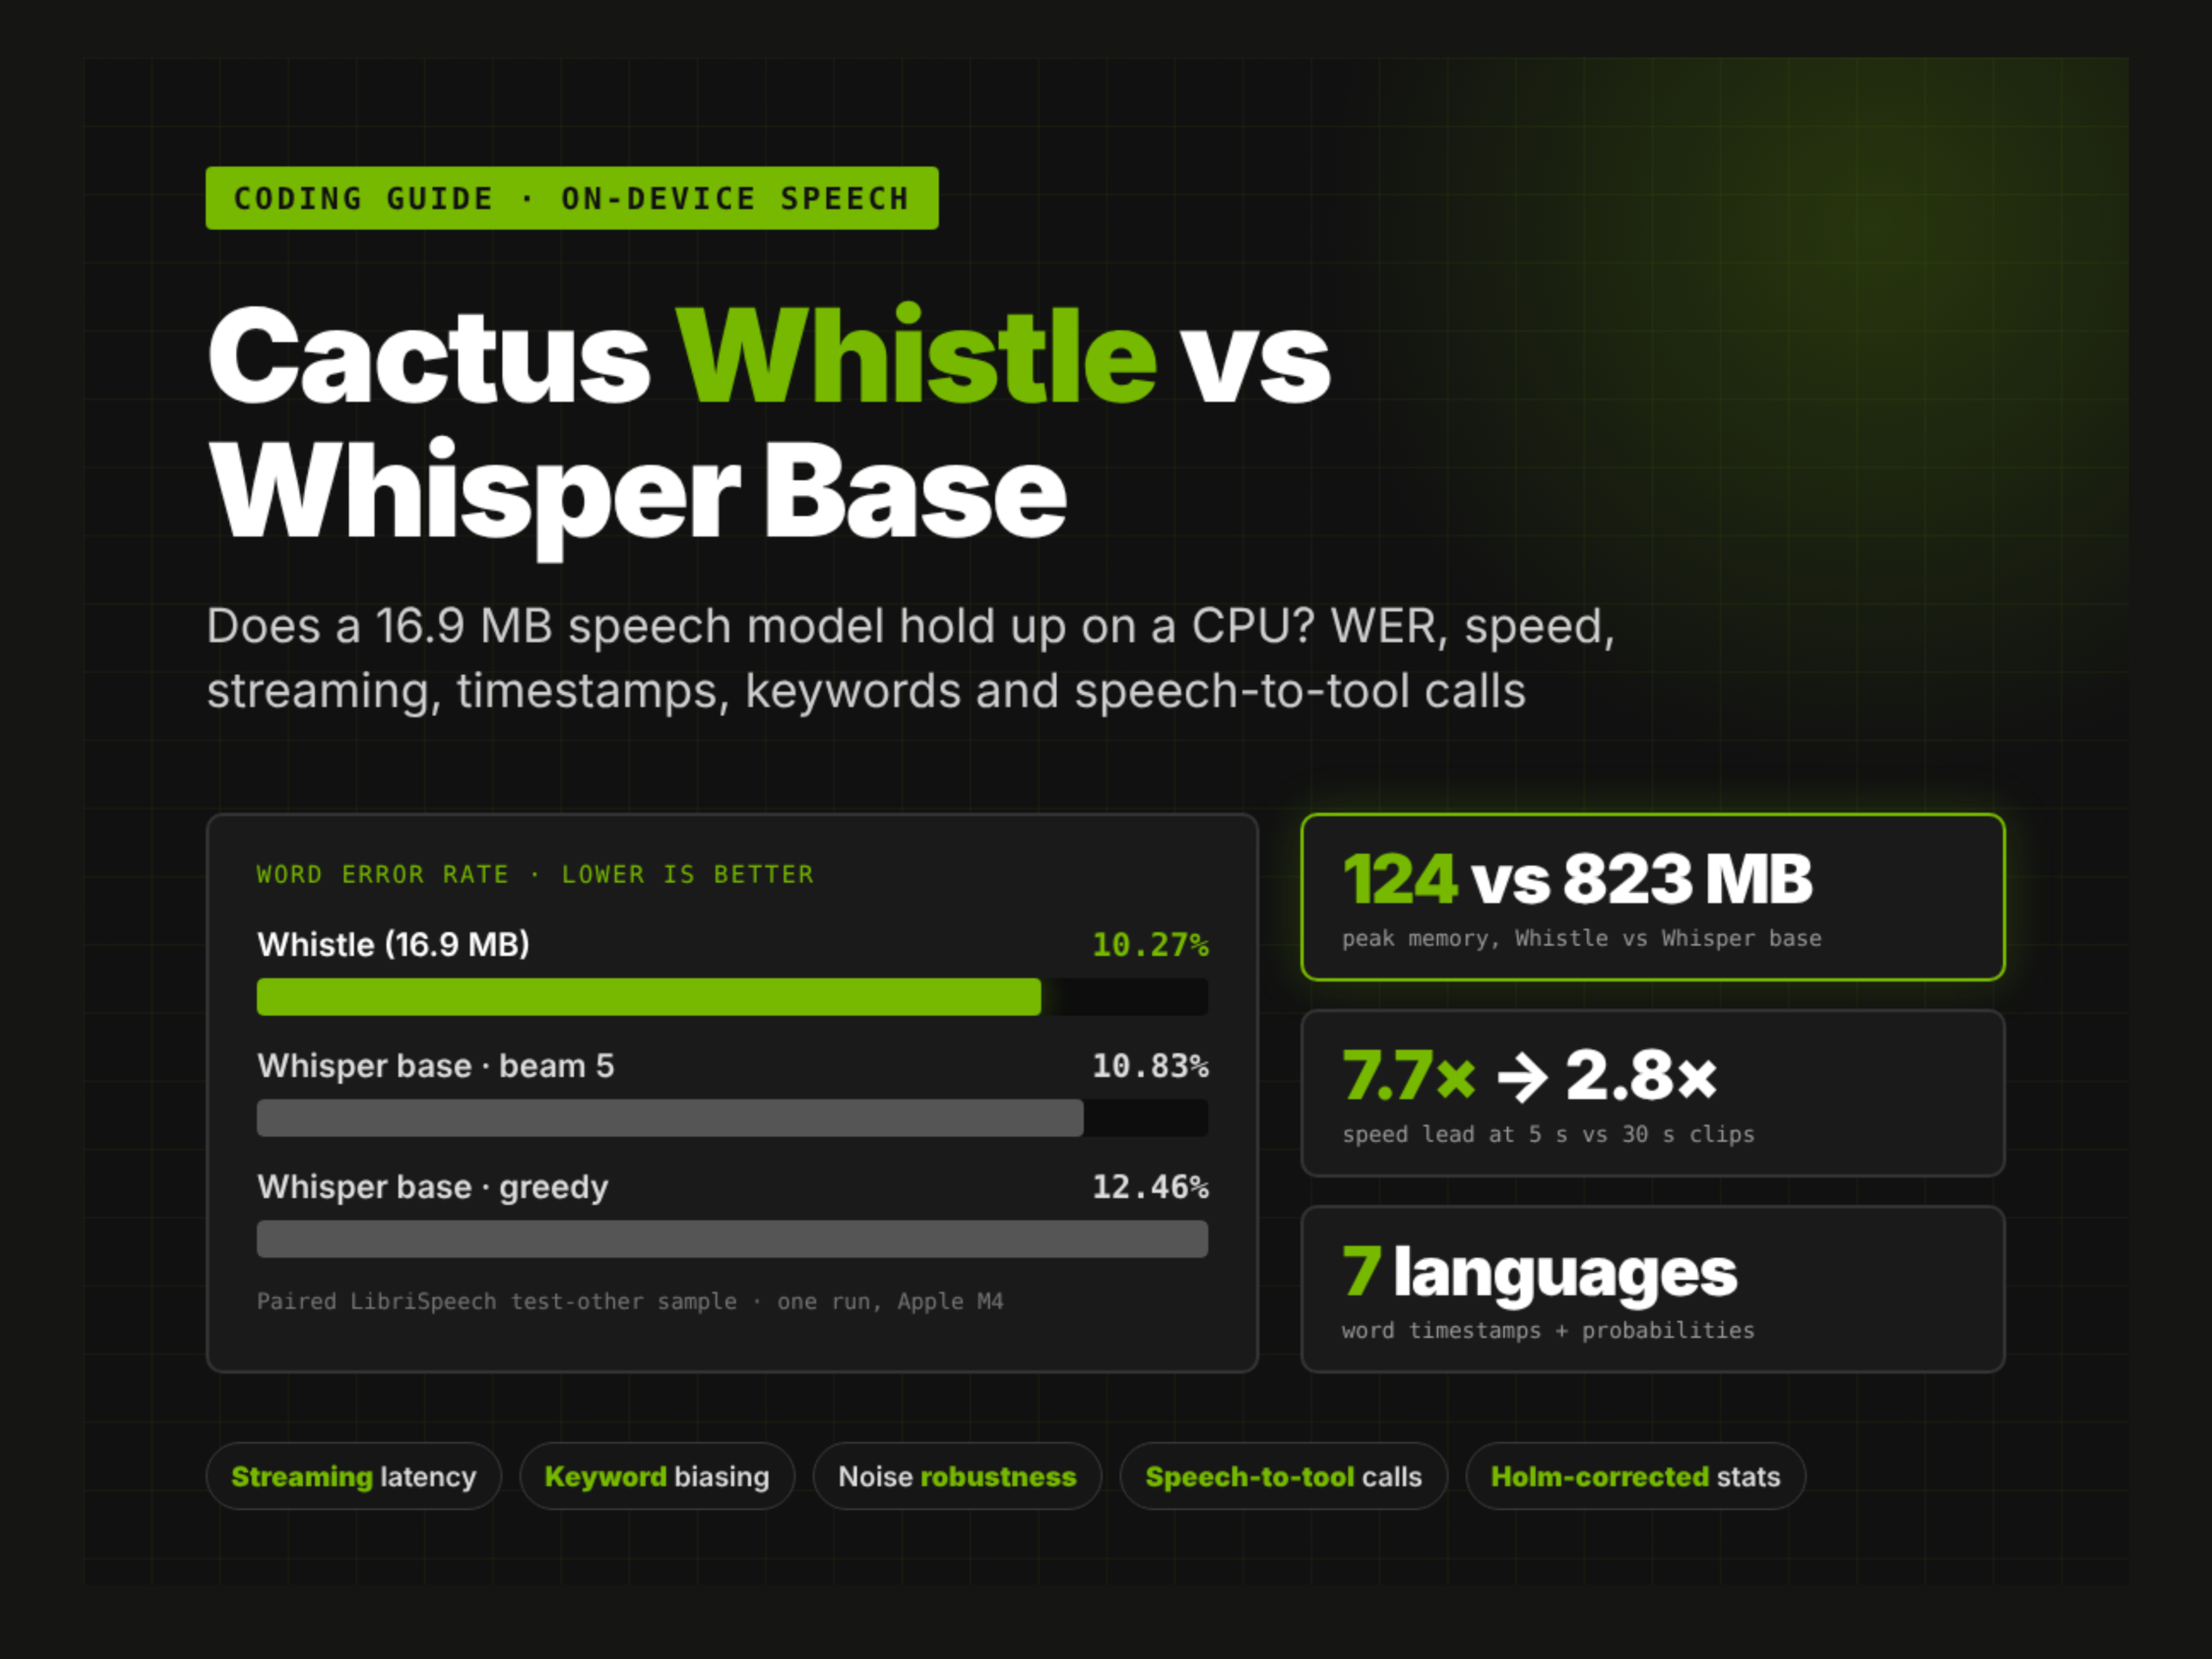
MarkTechPost tests Whistle on seeded LibriSpeech test-clean and test-other samples against Whisper tiny and base, finding a lead over greedy Whisper base on test-other but no significant gap versus beam search. The 16.9 MB model transcribes seven languages and returns word timestamps and probabilities.
MarkTechPost·3 hours ago
Omnara launches open-source API for durable AI agents
Omnara runs the agent loop server-side, provisioning sandboxes for command execution and handling secrets, permissions, and RBAC per agent. Agents are created with a single API call and their state is persisted.
Hacker News·3 hours agoVCs inflate AI startup valuations via tranched two-step rounds
Investors are competing to back Emulate, pushing its valuation into the billions though the company is three months old with no website or product. Tranched, two-step rounds are the mechanism VCs use to raise headline valuations.
Bloomberg Technology·3 hours ago
UK tax authority moves to tackle bad AI tax advice
HMRC is concerned that AI tools are giving people incorrect tax guidance, per Bloomberg. Details of the enforcement or oversight approach are behind a paywall.
NVIDIA Nsight Python tutorial profiles GPU kernels from Jupyter
Tutorial walks through Nsight Python, NVIDIA's open-source Python interface to its kernel profilers, using nsight.annotate and nsight.analyze.kernel to return per-region hardware metrics as a pandas DataFrame. Since version 1.0 it attaches Nsight Compute to the running Python process, and the upcoming 1.1 adds an experimental CUPTI backend.
