Dimuon optimizer for LoRA fine-tuning reaches lower loss in fewer steps than AdamW
Read original source →x.com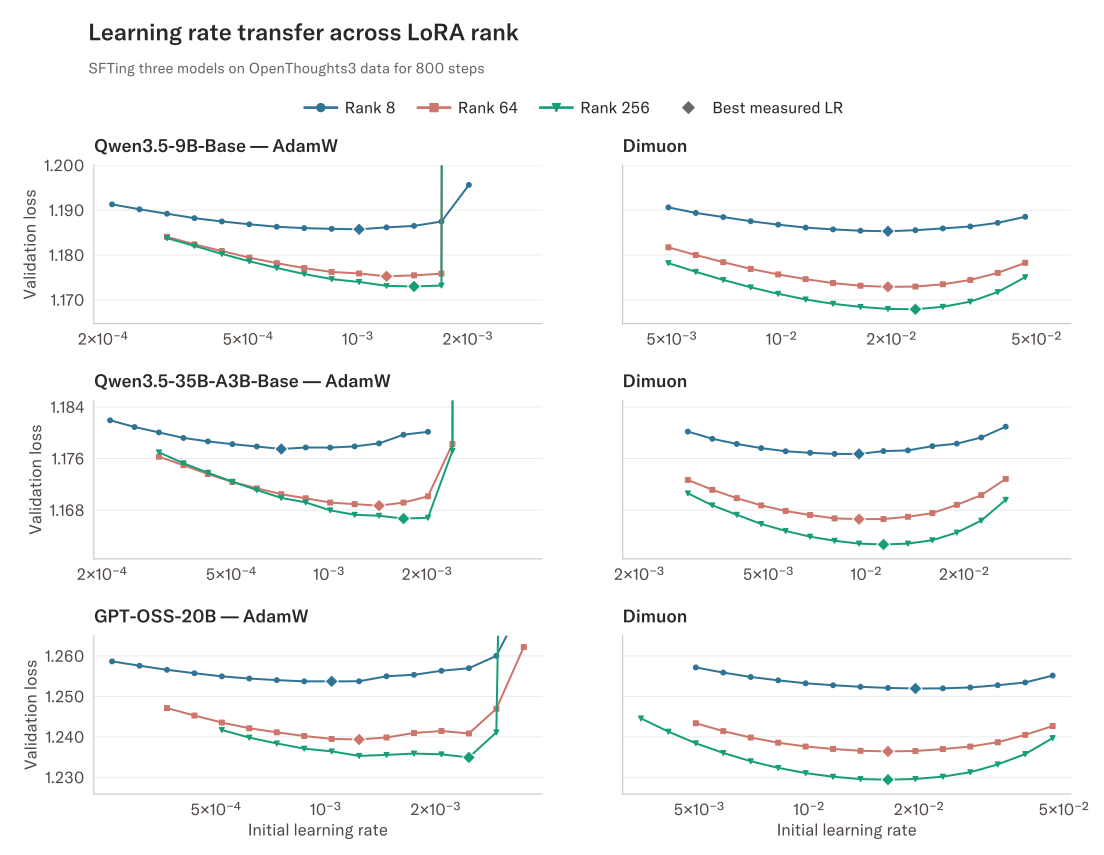
1 source
More stories today
Together AI, NVIDIA and Reflection host NYC builder event
Together AI·3 hours ago
Anthropic reportedly targets $110B annualized revenue by end of 2026
Kimmonismus·3 hours ago
Grok analyzes Bucket Robotics video
Robert Scoble·3 hours agoNous Research's Hermes powers a business, per Scoble
Robert Scoble·3 hours ago
Muon variant improves LoRA fine-tuning efficiency
Horace He·3 hours agoDream logger turns dreams into images via OpenAI image-gen API
Fede·3 hours ago
ComfyUI users test whether 12GB VRAM handles minimax h3
A ComfyUI user asks whether 12GB of VRAM is now "enough for everyone" for minimax h3, citing recent ComfyUI fast-disk and dynamic-VRAM options. The thread asks others to report peak VRAM and NVMe read throughput in MB/s.
r/ComfyUI·3 hours ago
Podcast: Kevin Roose on AI rivalries and safety
Big Technology Podcast host Alex Kantrowitz interviews Kevin Roose, author of The AGI Chronicles, about whether an AI industry marked by personal rivalries, infighting, and mistrust can be trusted to build technology more powerful than humans.
YouTube·3 hours ago