NVIDIA lifts Ling-3.0-flash MoE throughput 42.5% on DGX Spark
Read original source →marktechpost.com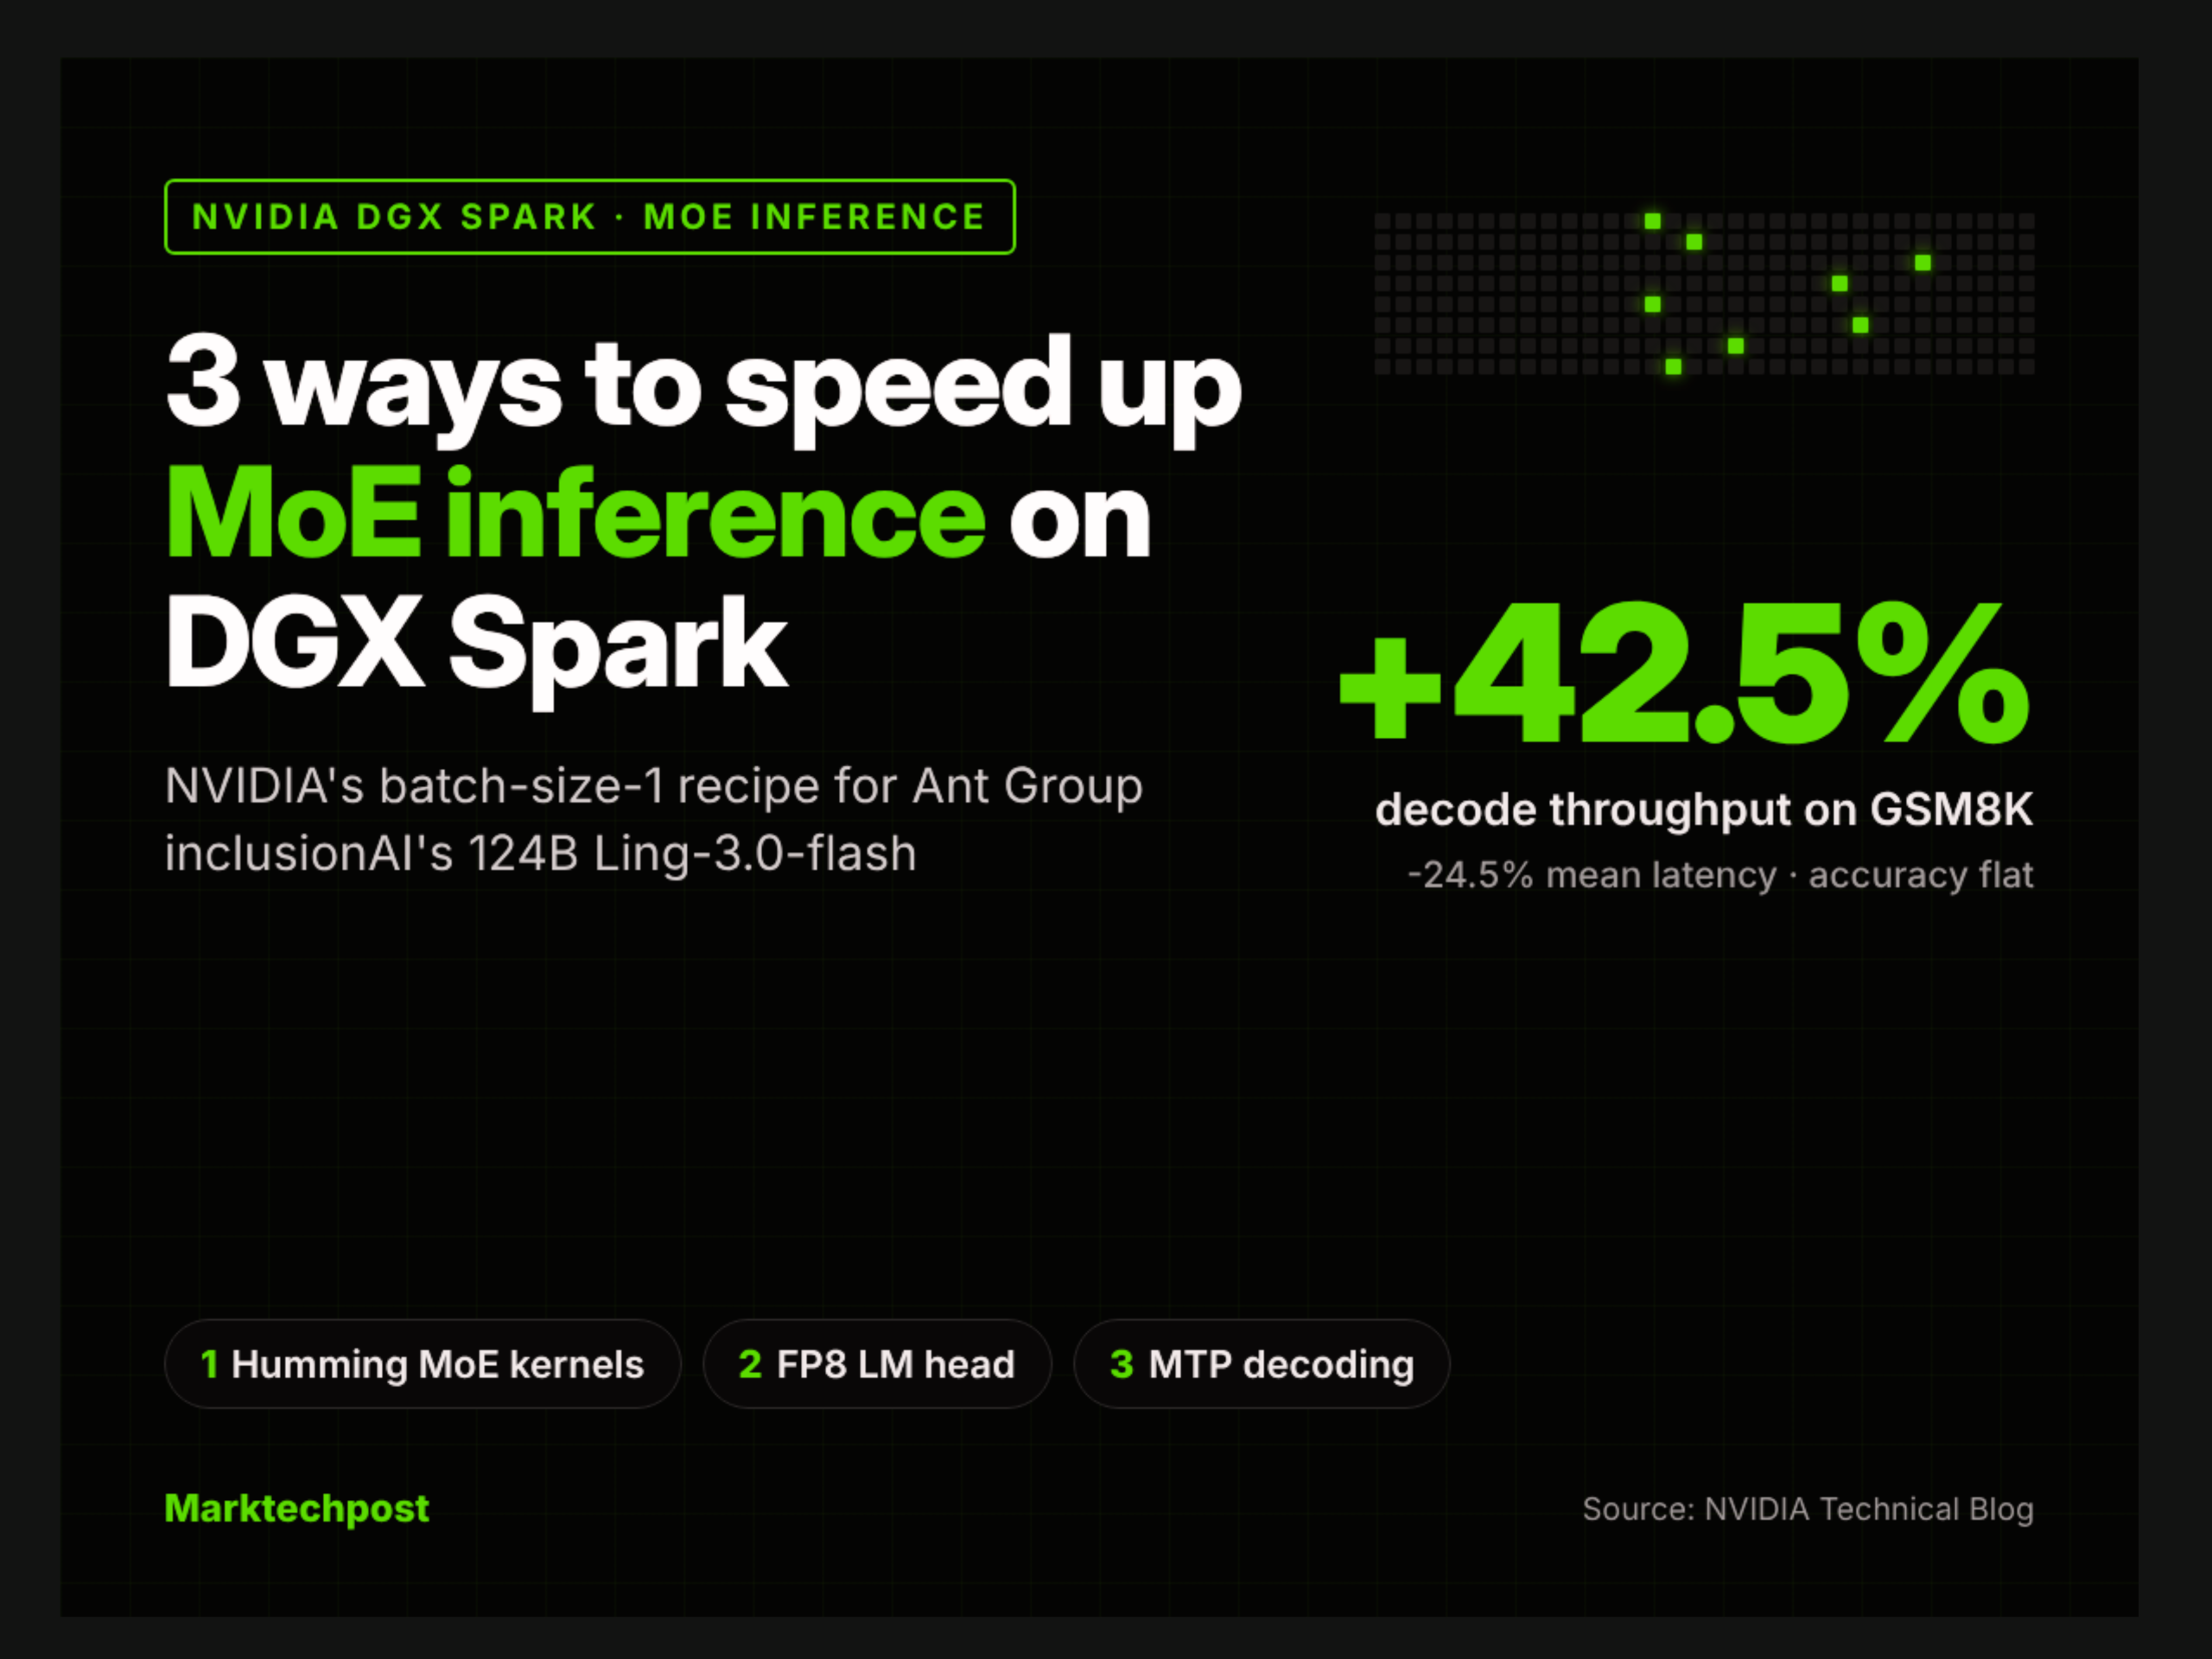
Three stacked optimizations — a new MoE kernel backend, an FP8 output layer and speculative decoding — raised GSM8K decode throughput from 37.81 to 53.89 tokens/s on one DGX Spark, with mean latency down 24.5%. Accuracy stayed flat at 96.89% vs 96.82%.
1 source
More stories today
Mercor raises $750M Series D at $20B valuation on $3B run rate
Mercor's annualized revenue went from under $500M at last year's $10B Series C to $1B in February, $2B in June, and $3B now. The data vendor reports 5 million experts on its platform.
Latent Space·1 hour ago
MDCalc launches CrossCover to vet clinical AI chatbot answers
CrossCover strips patient and provider identifiers from clinicians' queries rather than brokering privacy agreements, a contrast with OpenEvidence, Abridge and Epic. MDCalc AI head Graham Walker says the tool removes risks so physicians feel more confident using generative AI.
STAT News AI·1 hour ago

Harrison Chase: goal engineering replaces context and harness engineering
Harrison Chase·1 hour agoRauch: agentic coding will spawn purpose-built languages
Guillermo Rauch·1 hour agoACE Music v1 tops AA-Music-Vocal v1.1, ahead of Suno v6
Artificial Analysis·1 hour ago
Prompt for Grok Bot, Duet and Dots targets agent underuse
Alex Finn·1 hour agoCommentary: AGI looks more like Hugging Face than a single closed lab
Lee Penkman·1 hour agoAndreessen: AI-native startups' edge over incumbents is widest he's seen
Marc Andreessen says the gap between what AI-native startups can do with AI and how typical incumbents use it is as wide as he's seen in his career. He argues many industries are up for grabs.
Pass The Scratch·1 hour ago