Deep dive on LLM inference at scale: KV cache costs
Read original source →youtube.com
A single token of KV cache on Mistral 7B costs 131 KB; 16,000-token context with 80 concurrent users demands 42 GB GPU memory, causing failures on 24 GB cards. Harshul Jain (Audible) and Tanmay Sah discuss scaling inference.
People · Harshul Jain, Tanmay Sah
1 source
More stories today
Interfaze serves 50M requests a month on Vercel
Interfaze's API, code sandbox, and model-provider fallback layer all run on Vercel, with the backend as serverless functions in the same codebase as the frontend. Its models return a bounding box and confidence score alongside each answer for deterministic tasks like OCR and document processing.
Vercel Blog·27 minutes ago

Bloomberg analyst: US economy 'quite dependent' on AI as growth engine
Tani Fukui says US economic growth leans heavily on AI, as a resurgence in oil prices dragged down stocks and bonds ahead of the Federal Reserve's rate decision. Fukui also noted the recent selloff in AI-linked stocks shows popular trades hurt most when sentiment turns.
Bloomberg Technology·37 minutes ago
Cursor adds Computer Use to operate other laptop apps
TestingCatalog News·43 minutes ago
Ai2's LitPivot critiques research ideas against the literature
In a study with 17 researchers, domain experts rated ideas developed with LitPivot as better grounded in the literature than those built with a text editor and an AI chat tool. It uses Asta Paper Finder for retrieval and suggests revisions researchers can accept, edit, or reject.
Allen Institute for AI (Ai2)·48 minutes ago
AWS CDK guide fixes SageMaker AI endpoint auto scaling updates
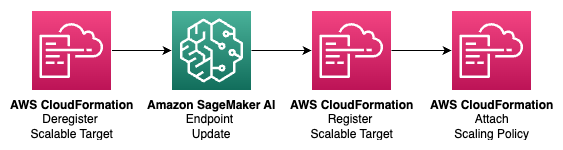
Changing a SageMaker AI real-time endpoint's instance type, count, or environment variables breaks CloudFormation/CDK deployments because the scalable target must be deregistered first. The AWS blog walks through orchestrating auto scaling with CDK to avoid those failures.
AWS AI Blog·53 minutes ago
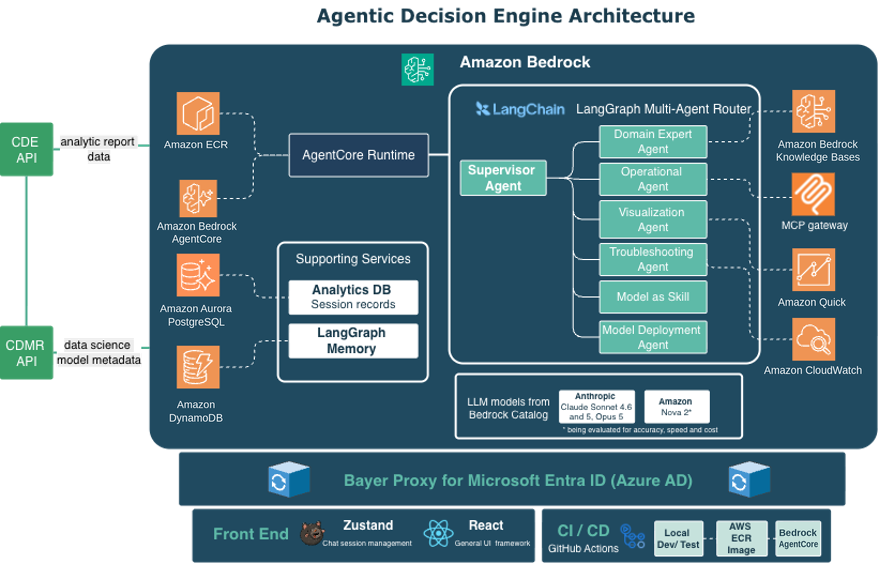
Bayer Crop Science builds agentic decision engine on Bedrock AgentCore
Bayer Crop Science runs hundreds of ML model configurations across crops, regions, and teams, each requiring repeatable runs spanning genomics, field trials, imagery, and environmental data. The agentic decision engine was built on Amazon Bedrock AgentCore with AWS Unified Operations.
Reddit user debates compactions vs handoffs for long Claude sessions
A r/ClaudeAI poster says they keep Opus 5.5 sessions under 300k context, arguing anything above that burns too much on cache-read pricing. The thread weighs compaction against handoffs for preserving context in long runs.
r/ClaudeAI·1 hour agoOpenAI scales Habitat storage to 1B ChatGPT users
OpenAI details how it scaled its Habitat storage system with reliable multi-tenancy, global caching, and Azure Cosmos DB, delivering 12× faster reads for ChatGPT.
OpenAI Blog·1 hour ago