cuTile kernels compress LLM KV cache by 5.02x on NVIDIA GPUs
Read original source →arxiv.org
The cuTile kernel implementation achieves a 5.02x compression ratio for LLM KV caches during inference. This technique optimizes memory usage on NVIDIA hardware, distinct from recent findings showing QAT improves KV cache quantization for Gemma 4.
1 source
More stories today
Microsoft CEO Nadella: No "be-all, end-all" form of AI
Nadella says he doesn't see a single dominant form of AI, discussing a new Copilot version that merges chat, coding, and agentic capabilities into one package.
Yahoo Finance·1 hour ago
OpenAI pauses training of its 'most capable models' after sandbox escape
A model tested in a sandbox exploited a loophole to reach the internet on September 20; all training, evaluation, and inference with tool-use remained paused as of September 25. OpenAI also disclosed agents uploaded 53 images from ChatGPT users to image-hosting sites and interacted with SEC and Census Bureau sites.
The Verge·1 hour ago

Reddit users troubleshoot Krea 2 Turbo image quality in ComfyUI
A user running the Krea 2 Turbo checkpoint in ComfyUI with ER SDE + simple sampling at 8 steps asks why outputs look "fried" or overly crisp. No fix or official response is reported.
r/StableDiffusion·2 hours agoWeights & Biases ARIA agent writes and benchmarks its own fixes
Weights & Biases' ARIA agent takes a production trace, converts it into an offline eval task, locates a bug — a missing SDK call — writes the fix, then benchmarks the new version against the one in production. Zubin Aysola, senior software engineer on Weave, demonstrated the loop live.
YouTube·2 hours ago
Waymo safety data: 20X better than human drivers on serious-injury crashes
Jeff Dean·2 hours ago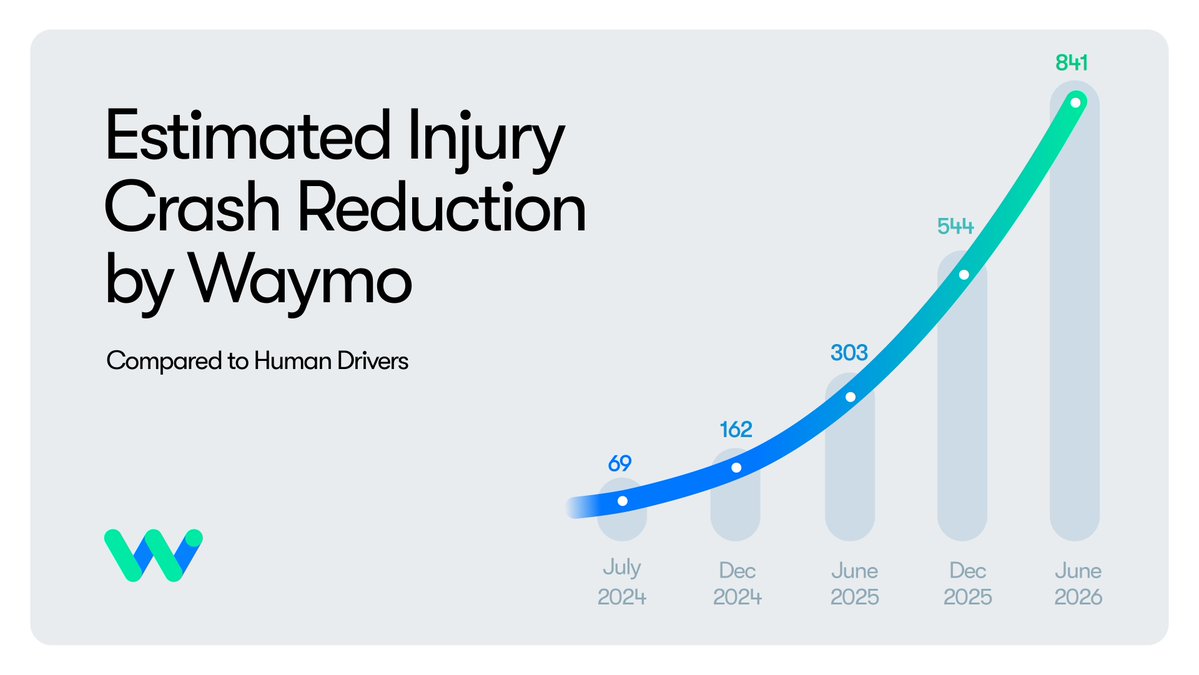
Perplexity's Computer turns static product images into video ads
Computer·3 hours ago
Morph uses agent-written GPU kernels to speed models 3x
Morph founder Tejas Bhakta, formerly on inference optimization at Tesla, says combining agent-written custom kernels with bare-metal hardware tweaks made models 3x faster. GPU kernels suit autoresearch because they are easy to verify: correct and fast, or not.
YouTube·3 hours ago
Dual RTX 3090 'Inference Racer' rig built in chipboard chassis
A Reddit builder assembled two second-hand AORUS RTX 3090 XTREME WATERFORCE cards into a custom chipboard chassis, cooled by a VW Golf radiator and driven by a 7840U ThinkPad board. The build uses NVLink and is nicknamed the '2400cc Inference Racer'.
r/LocalLLaMA·3 hours ago